
Tutorial
How to Use the qwen-image-3.0 API: curl, Python, and a Working Request
Qwen Image 3.0 is Alibaba's image model, live on hiapi's async task API in four entries: qwen-image-3.0/text-to-image, qwen-image-3.0/image-to-image, and the Pro versions qwen-image-3.0-pro/text-to-image and qwen-image-3.0-pro/image-to-image. This guide gives you a working request in curl and Python, the current input schema, and the production patterns you need before shipping it.
Updated October 2026. The earlier model id
qwen-image-3.0and itssizefield no longer work: the old id returnsMODEL_UNAVAILABLEandsizeis rejected as an unknown field. Use the model ids above withaspect_ratioandresolution.
What it costs
| Entry | 1K | 2K |
|---|---|---|
| Standard text-to-image / image-to-image | $0.0358 | $0.0358 |
| Pro text-to-image / image-to-image | $0.0497 | $0.0993 |
Standard costs the same at 2K as at 1K, so ask it for 2K. Editing costs the same as generating, and 1–3 reference images add nothing. Failed tasks aren't charged. Full breakdown: Qwen Image 3.0 API pricing.
A real output
Standard, 16:9. The sign reads 山止川行 with TEA & STORIES beneath, exactly as the prompt asked:
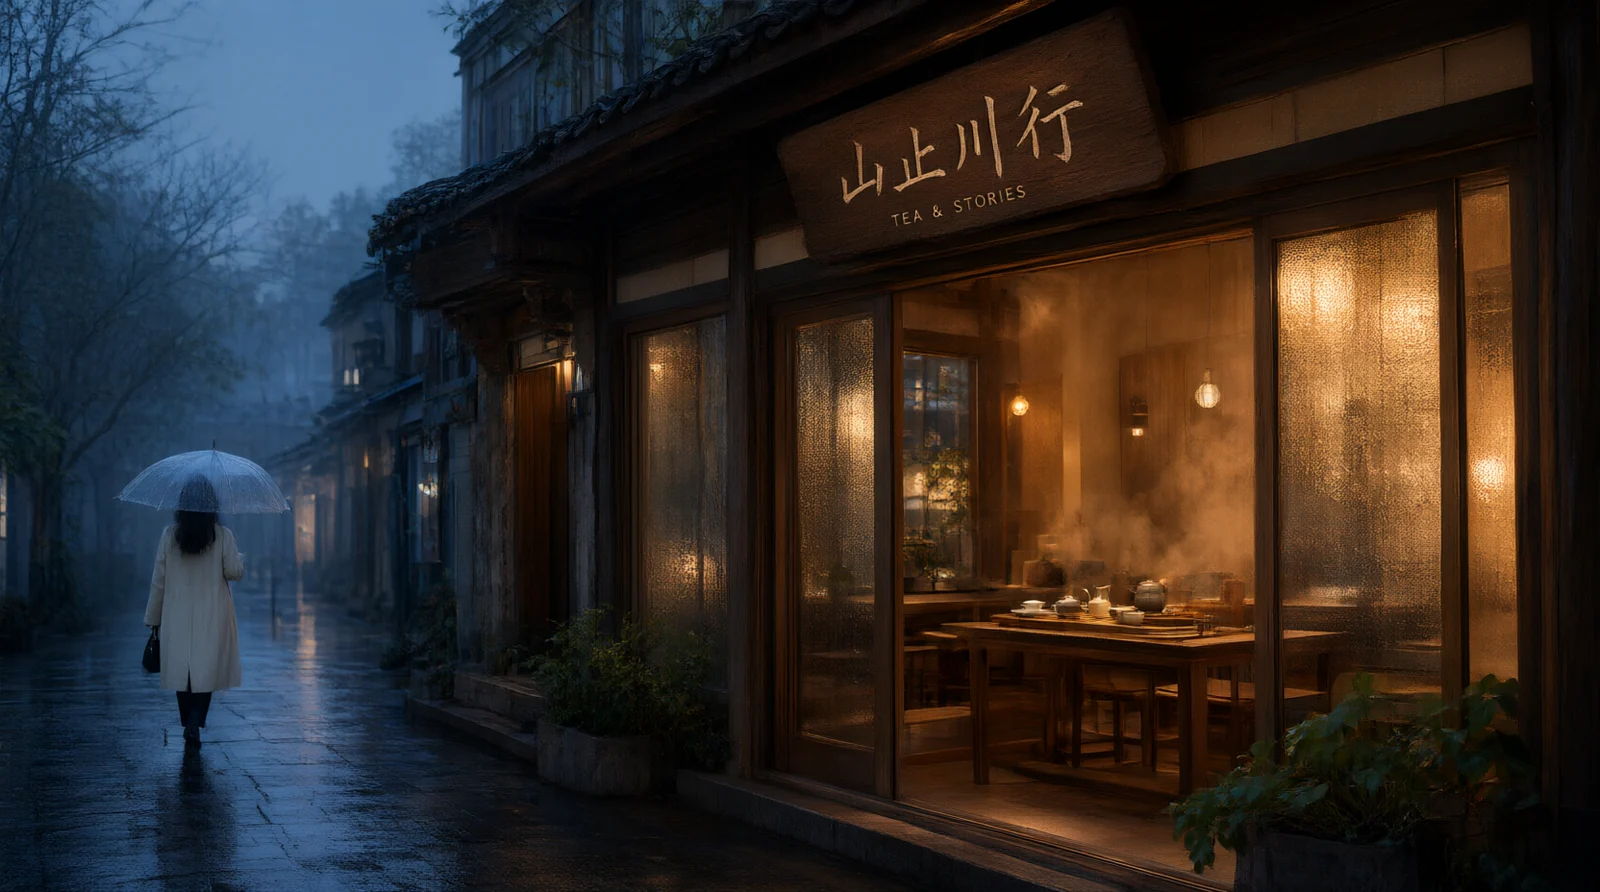
qwen-image-3.0/text-to-image, 16:9, $0.0358.
Minimal working example
Prerequisite: a hiapi API key from the dashboard.
curl
curl -s -X POST https://api.hiapi.ai/v1/tasks \
  -H "Authorization: Bearer $HIAPI_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "qwen-image-3.0/text-to-image",
    "input": {
      "prompt": "Product photo of a kraft-paper tea box on slate, the label reads exactly \"CLOUD MIST GREEN TEA\", soft top light, no other text",
      "aspect_ratio": "1:1",
      "resolution": "2K",
      "prompt_extend": false
    }
  }'
This returns a task id immediately:
{ "code": 200, "data": { "taskId": "tk-hiapi-01..." }, "message": "success" }
Poll GET /v1/tasks/{taskId} until status is success, then download data.output[0].url. The URL carries an expireAt timestamp, so copy the bytes to your own storage right away.
Python: generate, then edit
# pip install requests; export HIAPI_KEY=your-key
import os, time, uuid, requests

API = "https://api.hiapi.ai/v1/tasks"
H = {"Authorization": f"Bearer {os.environ['HIAPI_KEY']}"}

def run(model, timeout_s=300, **inp):
    # Reuse the same Idempotency-Key if you retry this submission, so it is billed once
    r = requests.post(API, json={"model": model, "input": inp},
                      headers={**H, "Idempotency-Key": str(uuid.uuid4())}, timeout=30)
    r.raise_for_status()
    task_id = r.json()["data"]["taskId"]
    deadline = time.time() + timeout_s
    while time.time() < deadline:
        d = requests.get(f"{API}/{task_id}", headers=H, timeout=30).json()["data"]
        if d["status"] == "success":
            return d["output"][0]["url"]
        if d["status"] in ("fail", "failed"):
            raise RuntimeError(d)
        time.sleep(4)
    raise TimeoutError(task_id)

# Text-to-image, Standard at 2K ($0.0358)
box = run("qwen-image-3.0/text-to-image",
          prompt='Product photo of a kraft-paper tea box on slate, the label reads exactly "CLOUD MIST GREEN TEA", no other text',
          aspect_ratio="1:1", resolution="2K", prompt_extend=False)

# Edit it: new background, label unchanged (also $0.0358)
edited = run("qwen-image-3.0/image-to-image",
             prompt="Keep the box and its label text exactly as they are; change the background to dark green velvet with a soft side light",
             image_urls=[box], aspect_ratio="1:1", resolution="2K")

with open("tea.png", "wb") as f:
    f.write(requests.get(edited).content)
To use Pro, change only the model id; the parameters are identical.
Input schema
The schema is strict: unknown fields return HTTP 400 naming the field.
| Field | Required | Values | Notes |
|---|---|---|---|
prompt |
Yes | up to 18,000 characters | Put any text that must appear in quotes |
aspect_ratio |
No | 1:1 (default), 3:2, 2:3, 4:3, 3:4, 16:9, 9:16, 21:9 |
|
resolution |
No | 1K (default), 2K |
Same price on Standard; Pro 2K costs double |
output_format |
No | png (default), jpeg |
|
prompt_extend |
No | boolean, default true |
Rewrites your prompt; turn off when wording must be exact |
negative_prompt |
No | up to 500 characters | What to keep out of the image |
seed |
No | 0–2147483647 | Fix to reproduce a result |
image_urls |
Image-to-image only, required | 1–3 URLs | JPEG, PNG, WEBP, BMP, GIF or TIFF, up to 10 MB each |
Production patterns
Use callbacks instead of polling. Add a top-level callback next to model:
{
  "model": "qwen-image-3.0/text-to-image",
  "input": { "prompt": "..." },
  "callback": { "url": "https://your-app.com/webhooks/hiapi", "when": "final" }
}
when: "final" fires once, on success or failure. Deduplicate by taskId. See the create task reference.
Send an Idempotency-Key header. Retrying a timed-out submission with the same key creates the task only once and bills once, as in the Python example above.
Handle errors explicitly. A bad or missing key returns HTTP 401 with permission_denied. Malformed input returns HTTP 400 with INVALID_REQUEST and a message naming the field, for example resolution: value must be one of '1K', '2K'. Generation failures arrive later as status: "fail" with details in data.error.
FAQ
What's the difference between Standard and Pro? Same parameters. Pro adds detail and layout density and costs about 39% more at 1K. Both render Chinese and bilingual text reliably.
My old code returns "model not available". Why? The bare id qwen-image-3.0 was retired. Switch to qwen-image-3.0/text-to-image (or /image-to-image), and replace size with aspect_ratio and resolution.
How many reference images can I send to image-to-image? One to three, in image_urls, at no extra cost.
Should I leave prompt_extend on? It helps short prompts, but it can rewrite text you need verbatim. Turn it off for signs, labels and posters.
Try a bilingual poster on the Qwen Image 3.0 model page, or compare it with Nano Banana 2.1 in Qwen Image 3.0 vs Nano Banana 2.1.
Related articles
View all articles →-

Tutorial
How to Call hailuo-2.3-fast/image-to-video via the HiAPI API: curl and Python
A first working request for the fast, low-cost image-to-video tier — from model ID to downloaded MP4
9 min read -

Tutorial
How to Use hailuo-2.3/text-to-video via the HiAPI API: curl, Python, and a Working Request
11 min read -

Tutorial
Kandinsky 6.0 Pro Text-to-Video on HiAPI: curl and Python Tutorial
A request-first walkthrough: build the prompt-to-clip call, submit it, poll for completion, and download the result
11 min read