
ByteDance
Seedream 4.5
seedream-4.5/text-to-image
ByteDance's commercial-grade image model, featuring cinematic lighting, cross-shot character consistency, and multi-image reference editing, ideal for high-resolution outputs for e-commerce and marketing assets
Try seedream-4.5/text-to-image
Input
Showcases
View all showcasesOutput
image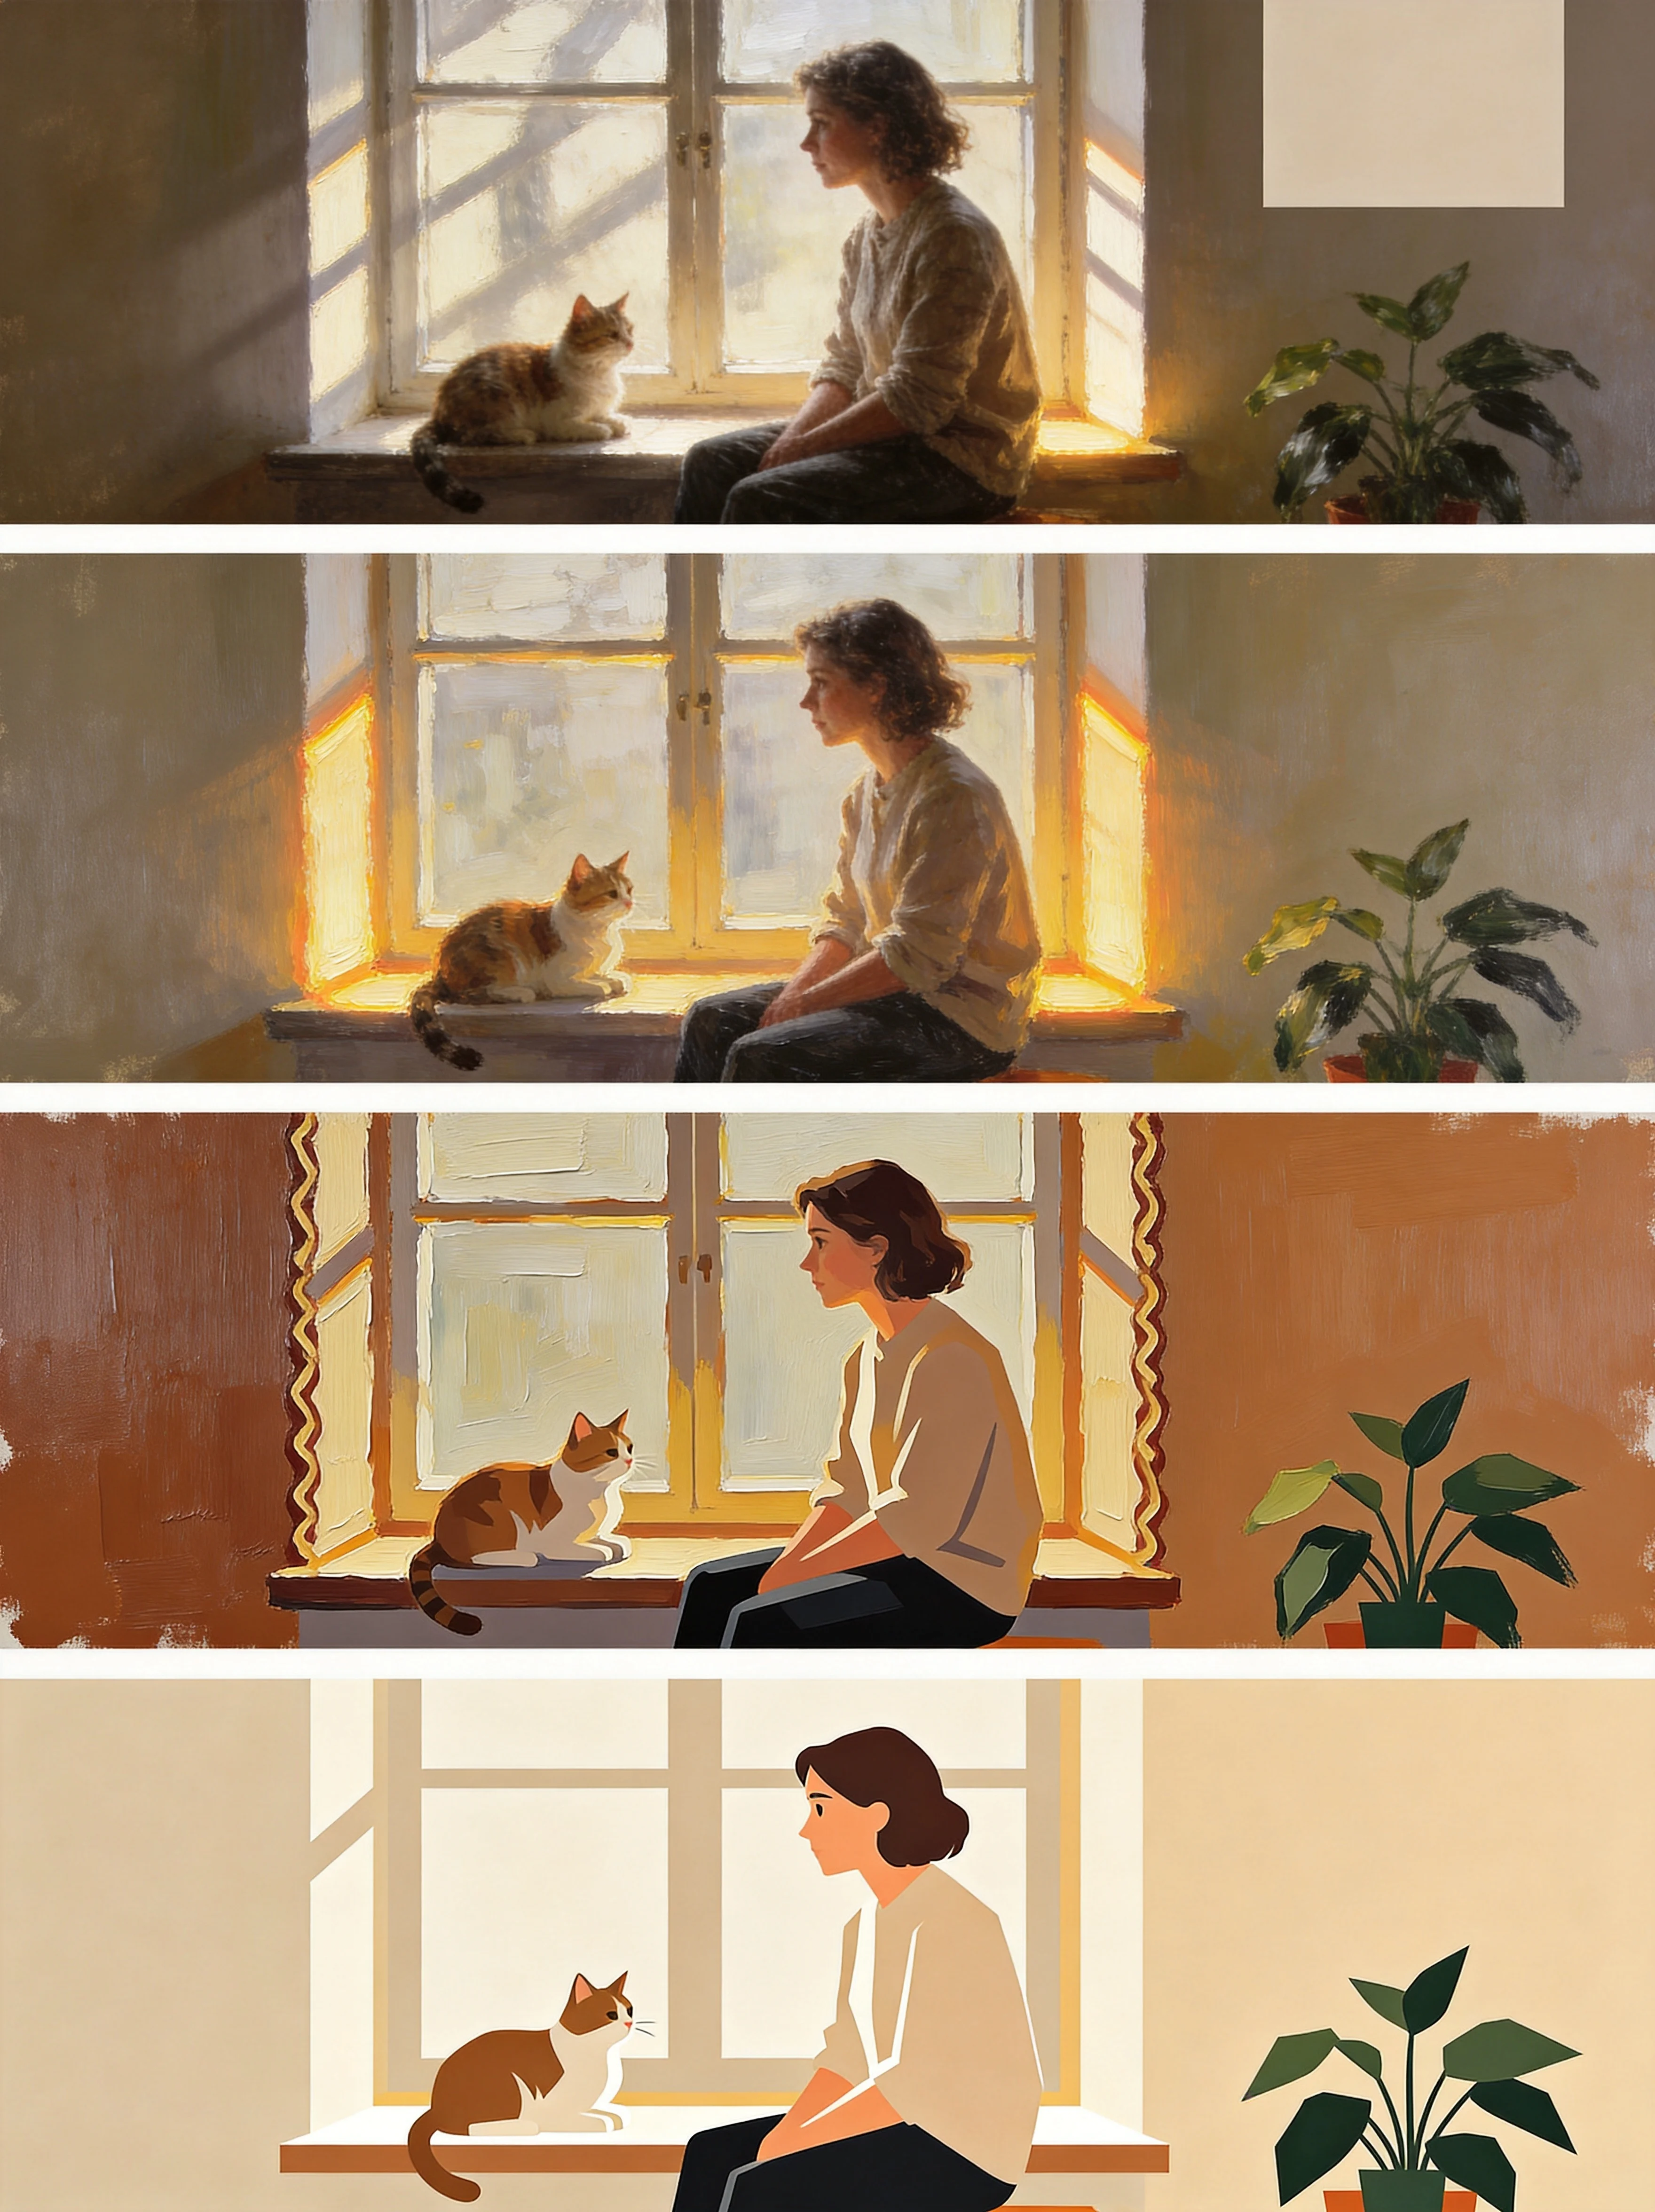
Realistic to Flat: A Four-Panel Illustration Across a Style Spectrum
Style style-spectrum · editorial-illustration · Lighting
Prompt
An editorial illustration concept presented as a four-panel horizontal comparison strip, with all panels sharing the same composition: a seated figure and a cat on a low windowsill, a plant on the right, a simple window frame behind, the subject facing left, and ample negative space in the upper right. Panel 1, photorealistic cinematic: volumetric window light, complex soft shadows, visible skin and fabric textures, shallow depth of field. Panel 2, semi-realistic painterly: soft brushstrokes, warm rim light, simplified but retaining volume. Panel 3, decorative impasto: thick visible brushstrokes, highly saturated tones, flattened perspective with textured edges. Panel 4, minimal flat vector: two-tone shapes, clean crisp edges, no gradients, geometric simplification. Consistent color temperature progression across panels, clean panel dividers, 16:9 widescreen composition, high detail, professional art direction quality.
Copy the full prompt and adapt it for your own generation.
Tags
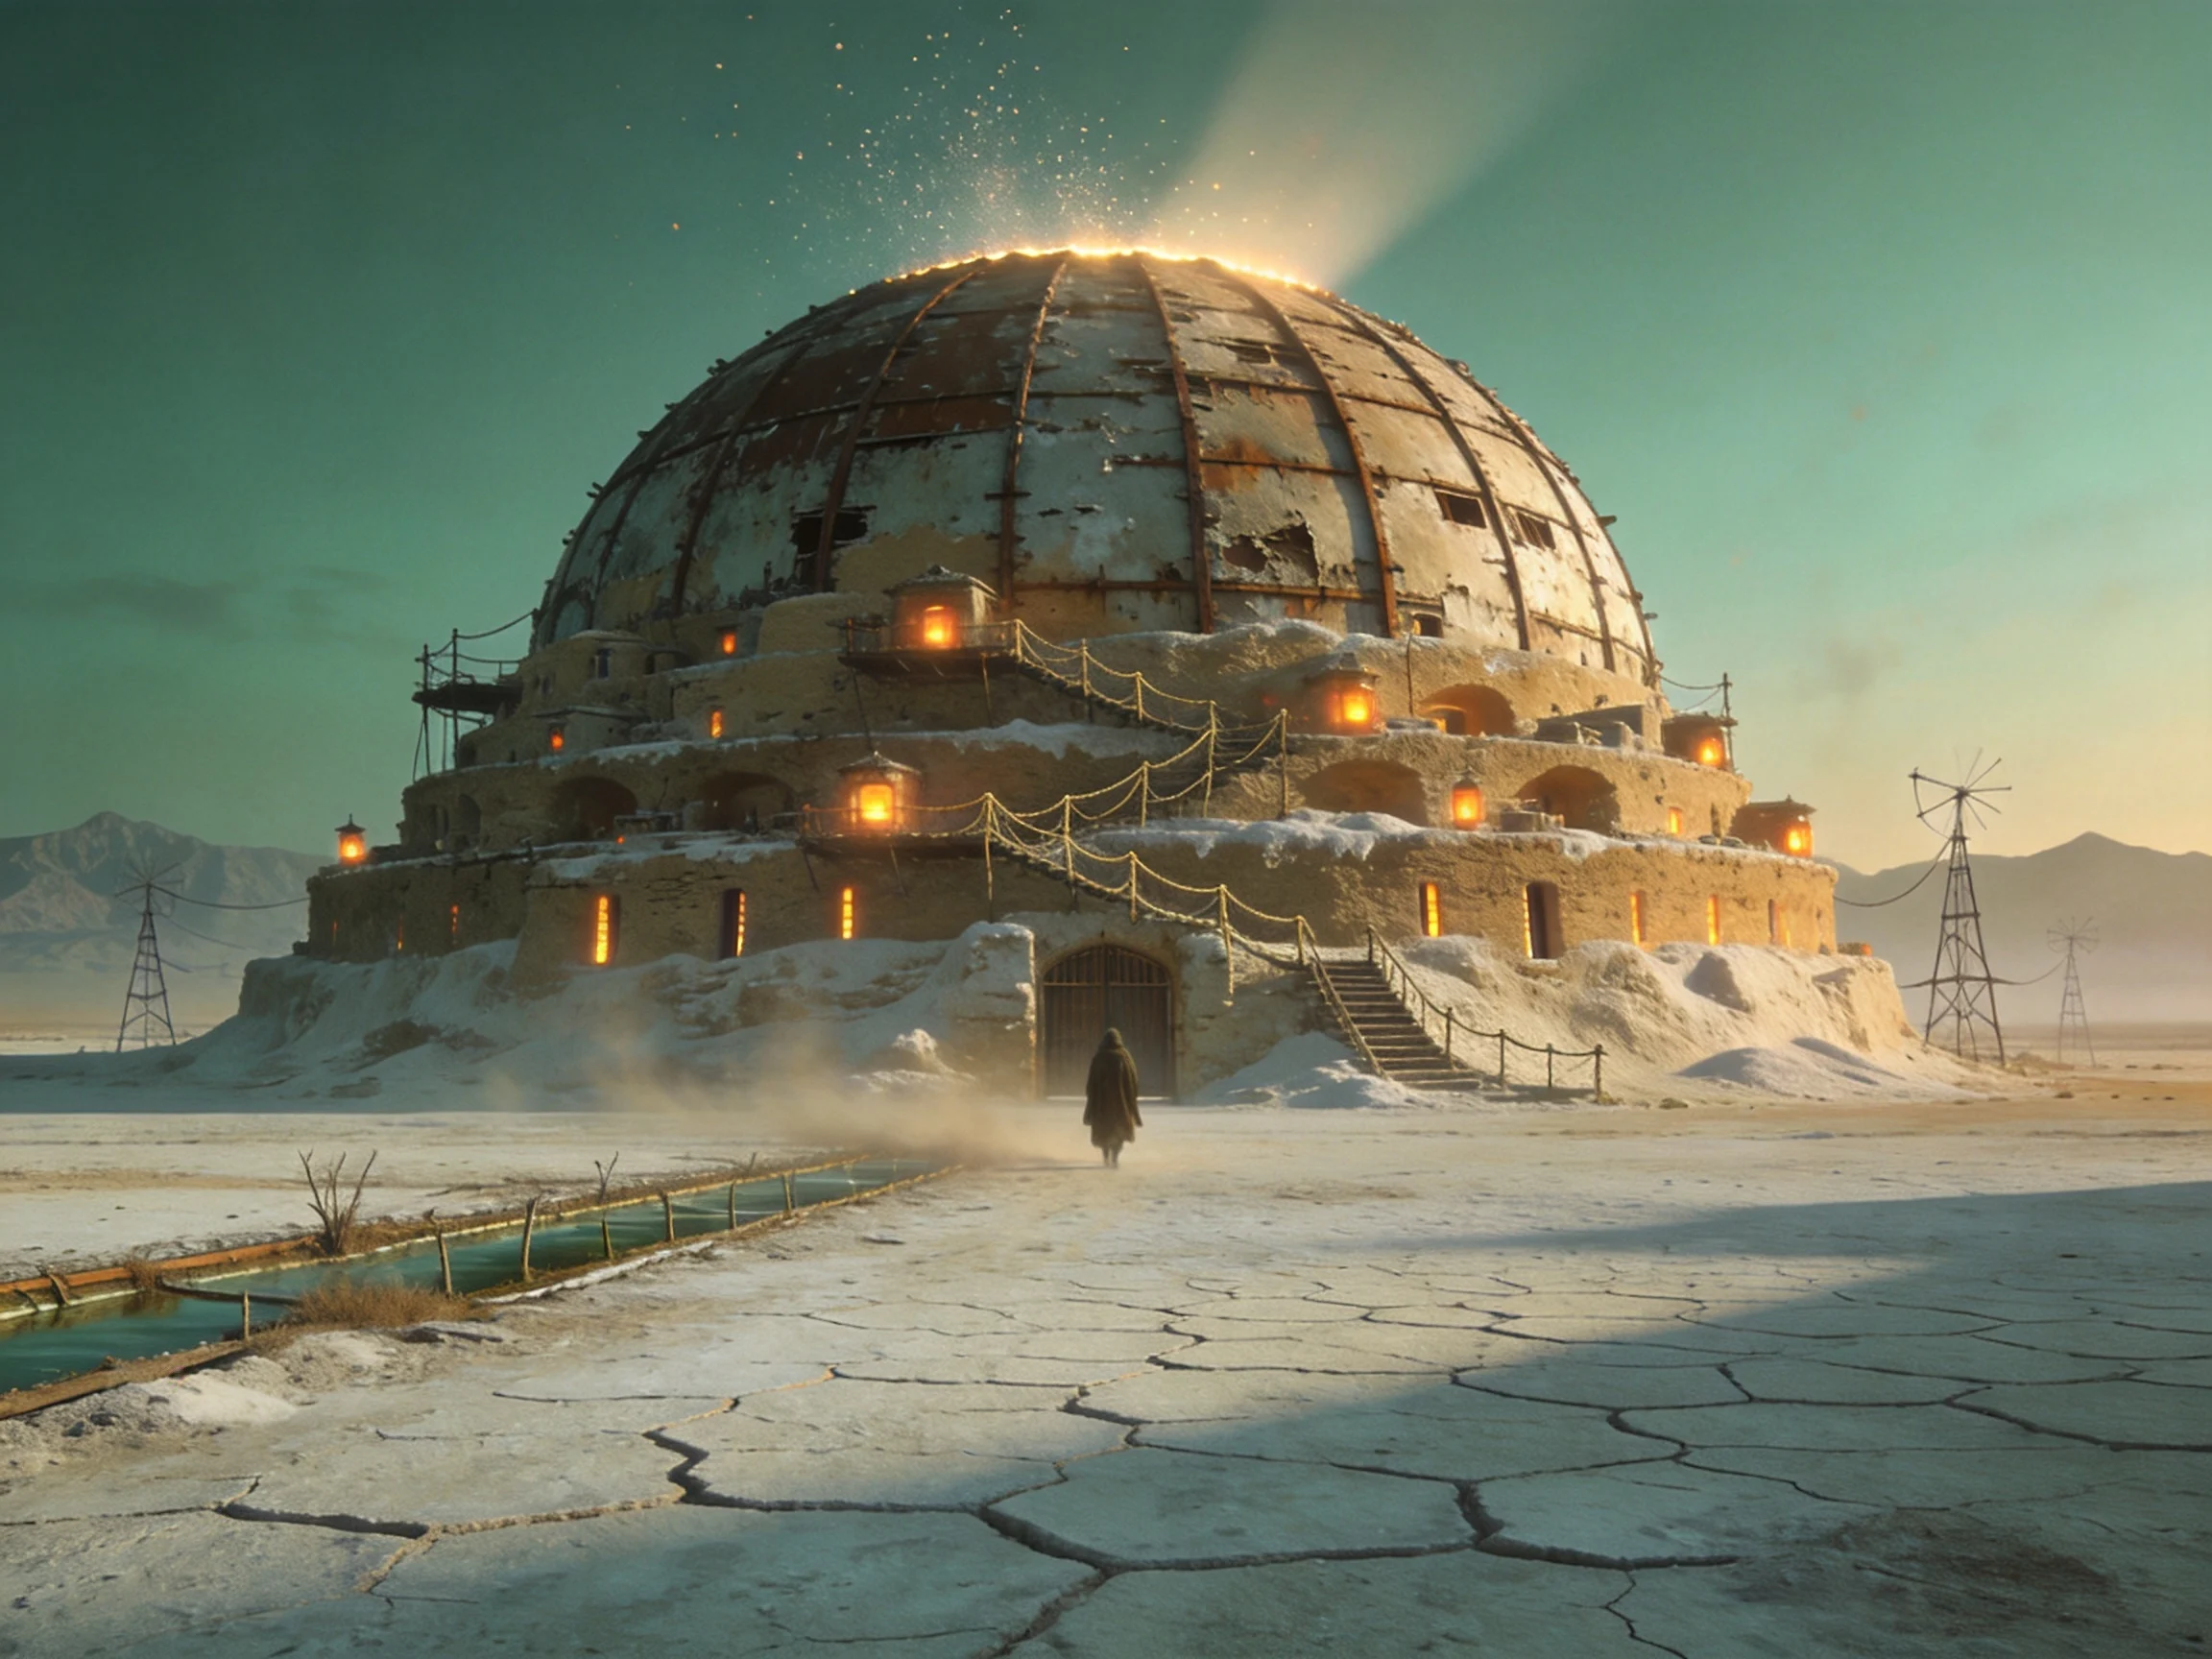
Worldbuilding Concept Art: Dusk at the Sand-Sea Dome City
Style Concept Art · Cinematic · Worldbuilding
Prompt
Cinematic widescreen panoramic shot: a massive dome-shaped settlement stands on a pale alkaline desert salt flat at dusk, built from salt-crusted sandstone and salvaged metal ribs. Layered architectural structure: a weathered outer dome, terraced dwelling rings carved into the base, narrow stairways and rope bridges, small clusters of warm amber lanterns glowing through slender window slits. Foreground: wind-blown fine dust drifting over cracked polygonal salt-flat terrain, a lone figure in a dust cloak walking toward the gate to convey scale. Midground: dried-out irrigation channels and bone-like wind towers. Background: low, hazy mountain silhouettes fading into atmospheric mist. Volumetric god rays spilling from beneath the dome's rim, soft long shadows, dust motes suspended in the air, realistic stone and metal material textures, subtle film grain, anamorphic lens depth of field, 35mm cinematic color grading, teal shadows and warm highlights, photorealistic concept art, extreme detail, 16:9 composition, horizon placed very low.
Copy the full prompt and adapt it for your own generation.
Tags
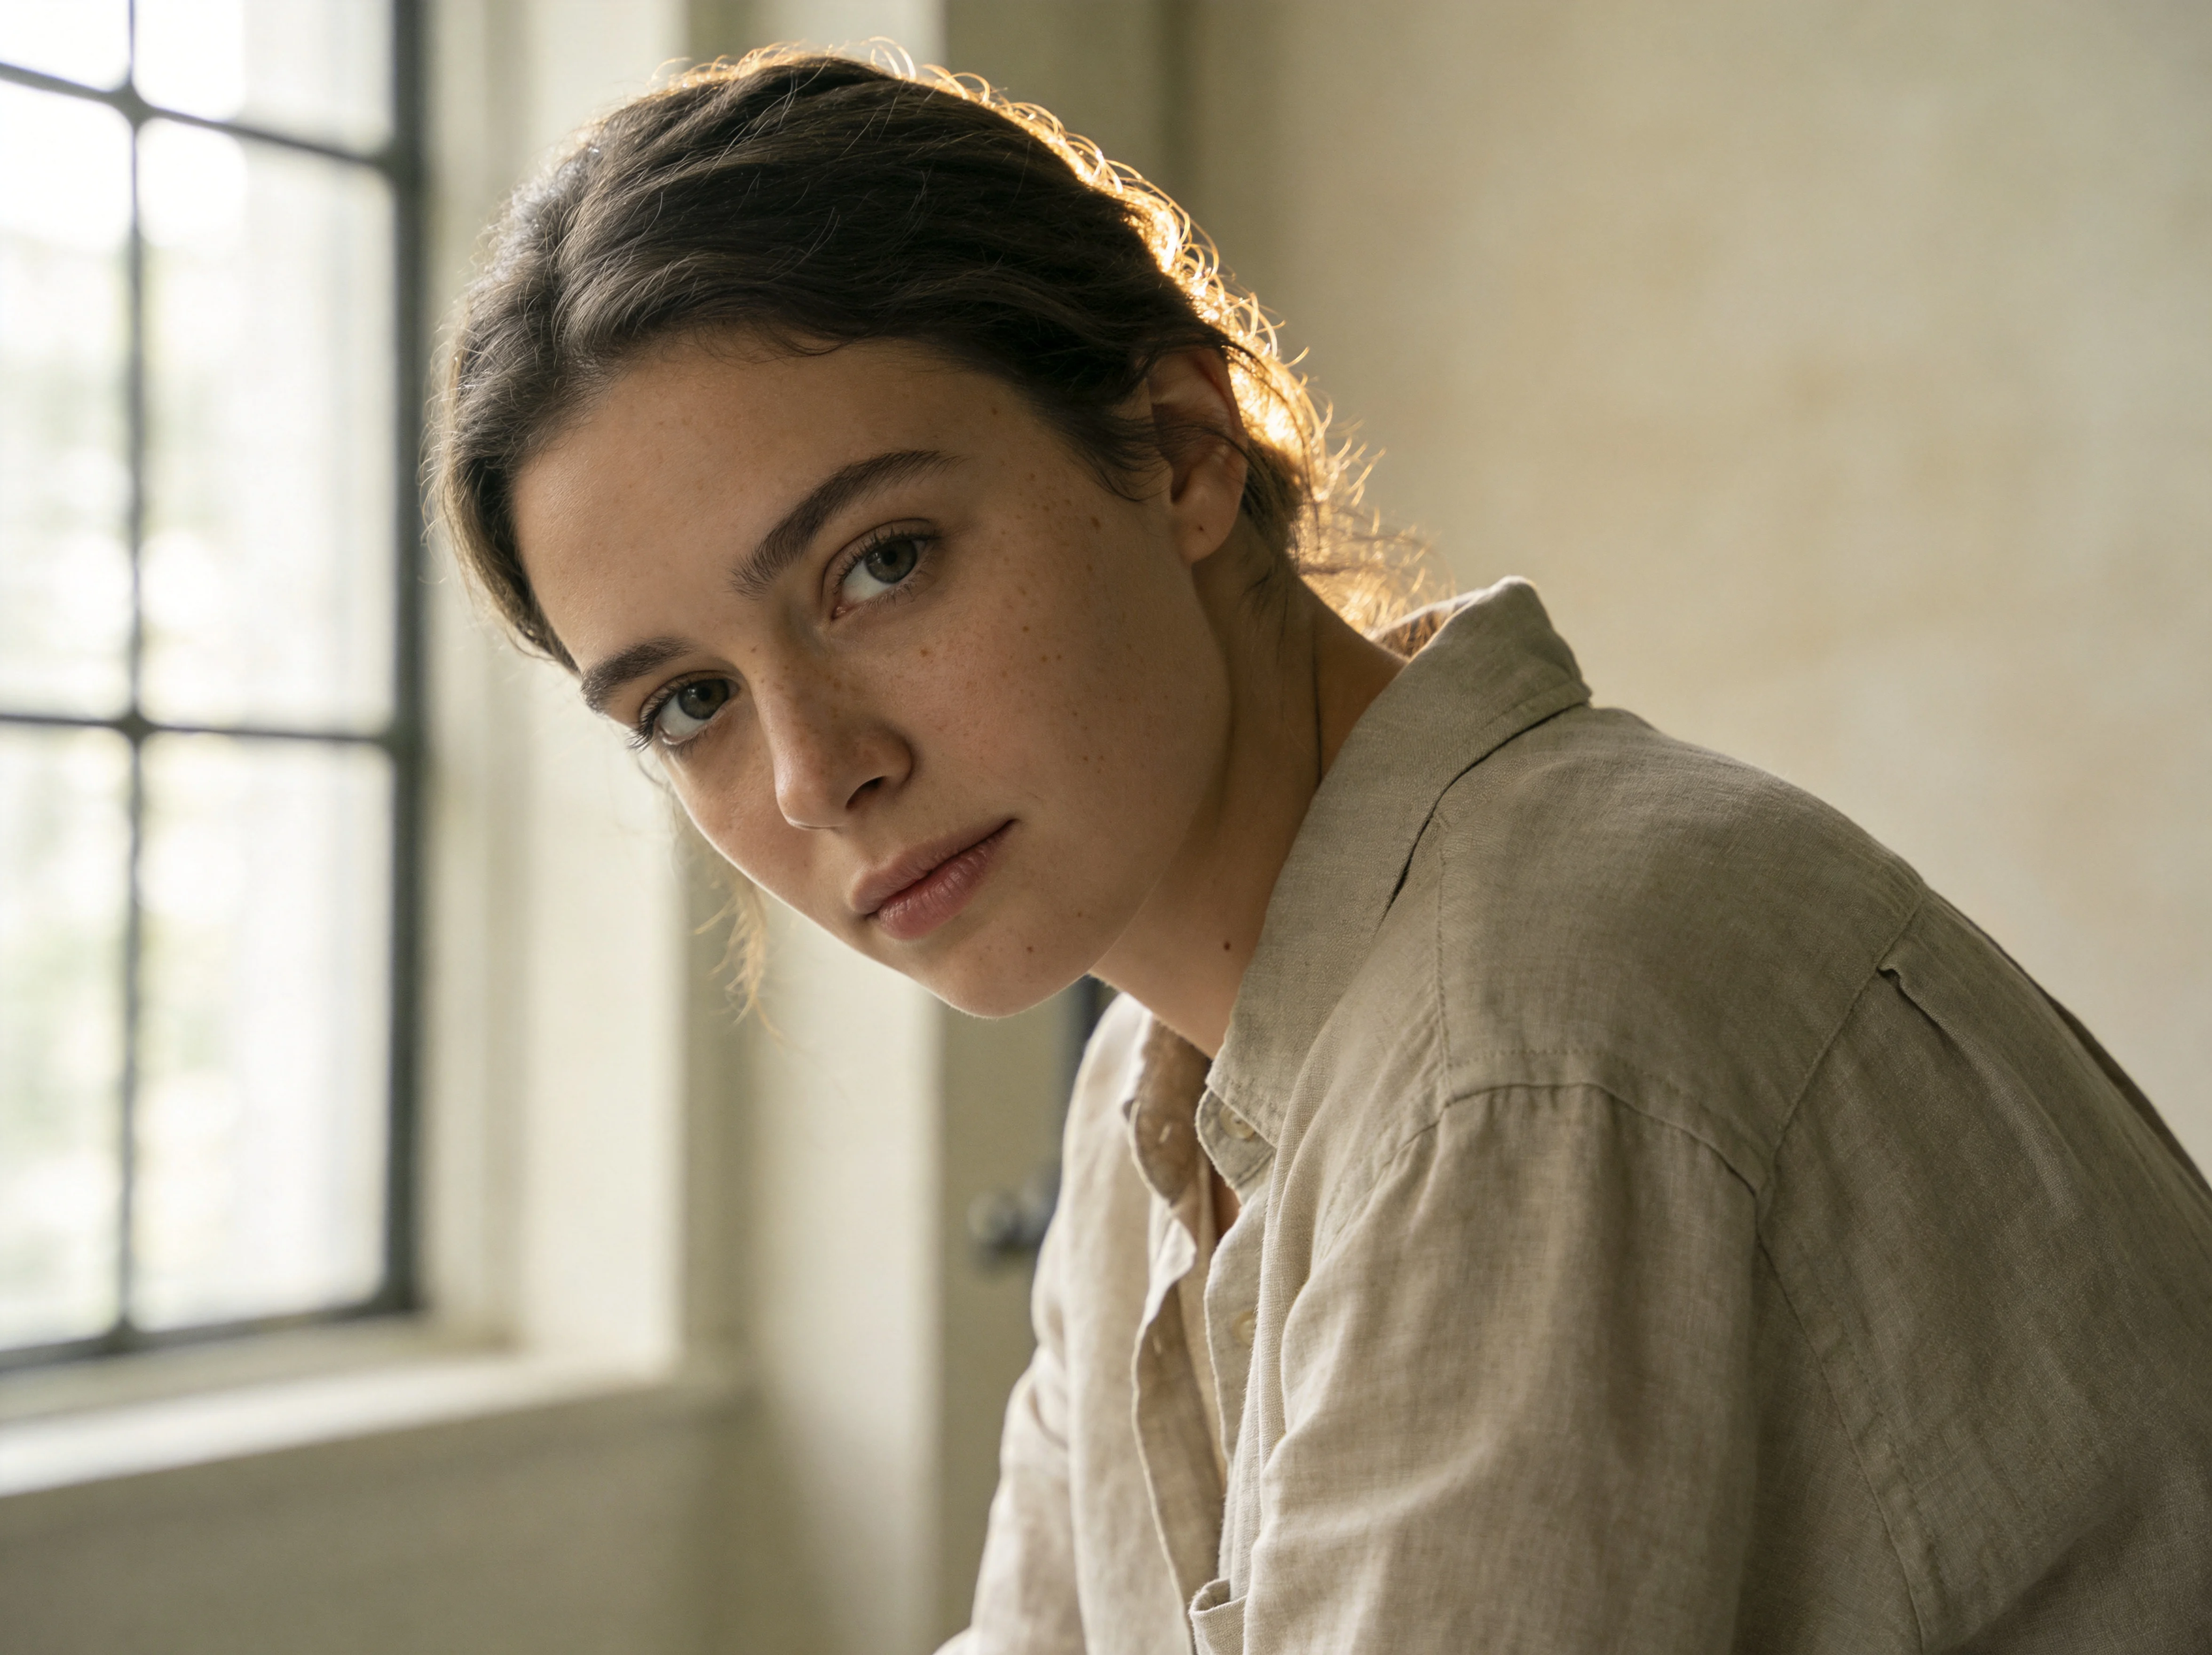
Seedream 4.5 Portrait Dual-Style Reference: Realistic and Artistic
Style Portrait & Photography · Photorealistic · Editing
Prompt
A realistic editorial-style portrait: a young woman in a linen shirt sitting beside a large window in a quiet studio, soft diffused daylight entering from camera left and creating a gradual, soft volumetric falloff, subtle rim light on the hair strands, visible natural skin texture including fine pores and light freckles, shallow depth of field with creamy-smooth background bokeh, an 85mm lens look, low-saturation warm neutral tones, cinematic color grading, high dynamic range, sharp and clear eye details, no text, ultra-fine detail
Copy the full prompt and adapt it for your own generation.
Tags
Pricing
seedream-4.5/text-to-image per image
| Unit Price | $0.045 |
|---|
Overview
The Seedream 4.5 text-to-image pipeline is designed for developers who need controllable, reusable visual output, generating photorealistic images directly from text prompts. It supports two native resolution tiers, 2K and 4K, along with eight aspect ratios ranging from 1:1 to 21:9, and accepts prompts of up to 3,000 characters. It is well suited to batch image generation tasks with clear requirements for image quality and composition, such as e-commerce product images, marketing assets, film and television concept art, and design mockups; it can be integrated into existing generation workflows by calling the unified HiAPI.ai interface.
Key Highlights
- Native 2K/4K high-resolution output — Output can be set to 2K standard or 4K ultra-high definition, eliminating the need to upscale low-resolution images afterward.
- Eight aspect ratios covering mainstream placements — From 1:1 square images to 21:9 widescreen, ratios can be specified directly, fitting different formats such as e-commerce, social media, and banners.
- Cinematic lighting and photorealistic texture — Research shows that its lighting simulates the volumetric fog and complex shadows of real photography, giving the final image a look closer to actual footage.
- Longer prompts accommodate complex descriptions — With a prompt limit of 3,000 characters, scene, materials, and spatial relationships can be fully described in a single request.
Capabilities
Text-to-photorealistic image generation: Enter a text description to produce a photorealistic image, turning creative descriptions directly into deliverable visual drafts and reducing the cost of manual drawing or photography.
Controllable resolution and aspect ratio: Use the resolution and aspect_ratio parameters to specify 2K or 4K output and one of eight aspect ratios; a single call yields an image that fits the target placement, with no need for secondary cropping.
Complex prompt parsing: Prompts of up to 3,000 characters can hold layered descriptions of scene, subject, and composition; research shows this version improves on its predecessor in prompt adherence and detail accuracy.
Commercial-grade image quality: Research shows its lighting, skin texture, and text rendering approach the look of photography, making it suitable for direct external delivery rather than drafts only.
Use Cases
- E-commerce operations: batch product scene images — Describe products and scene atmosphere in text to produce high-resolution main images and scene images ready for listing, for use in product detail pages and advertising assets.
- Marketing teams: marketing posters with text — Input layout and copy requirements to generate posters and banners with clear, legible text, ready for social media and ad placements.
- Film and games: concept art and storyboards — Generate images in batches from script or setting descriptions to produce concept designs and storyboard frames for early-stage discussion and art direction approval.
- Design teams: multi-format visual drafts — Leverage multiple aspect ratios and 2K/4K resolutions to quickly produce visual drafts suited to different devices, for client proposals and iteration.
Limitations and Selection Advice
This pipeline accepts text input only; if you need to edit or reference-composite from existing images, choose the image-to-image pipeline in the same series. Research notes that 4K-level generation places high demands on compute and generation latency, so latency-sensitive scenarios should evaluate the waiting cost of image generation. Most capability descriptions are improvements relative to Seedream 4.0, and independent benchmark comparisons with other contemporary models are lacking; when selecting a model, it is advisable to test actual results on your own business samples before deciding.
Frequently asked questions
View all FAQs →-
What is the difference between Seedream 4.5 image-to-image and text-to-image?
The image-to-image endpoint uses uploaded images as editing references for recoloring, scene changes, relighting, style transfer, and multi-image composition. Text-to-image starts from a written prompt without a source image. Use this image-to-image model when subjects, composition, or in-image text should remain recognizable.
-
How many reference images does Seedream 4.5 support?
Each request accepts 1–14 JPEG, PNG, or WebP images up to 10 MB each; SVG is not supported. For multi-image jobs, refer to inputs as “image 1” and “image 2” in the prompt, matching their order in the image_urls array.
-
How is Seedream 4.5 image editing priced, and do more references cost extra?
Billing is per successful output image, not per reference image. The current public rate is the same for 2K and 4K output. See the live model price and task record for the final charge.
-
How do I preserve a subject, composition, or text during an edit?
State both what should change and what must remain unchanged, such as the subject silhouette, camera angle, contact shadow, storefront layout, or calligraphy. Review the result in the Playground first. Keep human review for brand text or layouts that must be exact.
Create a generation task
https://api.hiapi.ai/v1/tasks Headers
AuthorizationstringRequiredAccount API key. Required on every request. Example: Bearer YOUR_HIAPI_API_KEY. Get your API key
Content-TypestringOptionalThe request body is always parsed as JSON; when sent, only application/json (optionally with charset) is accepted — any other value returns 415. Example: application/json.
Idempotency-KeystringOptionalIdempotency key, up to 255 bytes. Retries with the same key from the same account create the task only once; replays return the original taskId.
On network timeouts or client retries, the same key creates the task only once — no double charges (scope: the API key's account). Use a business-unique identifier as the key (e.g. "order-42"); replays return the original taskId, and keys expire 24 hours after the first request. See the Unified Async API overview for the full scenario matrix.
Body
modelstringRequiredCurrent fixed value: seedream-4.5/text-to-image
routestringOptionalCurrent fixed value: default
inputobjectRequired
Business parameters for seedream-4.5/text-to-image and route default — see the parameter table below.
promptstringRequiredminLength 4maxLength 3000Text prompt describing the desired image content, provided as a string, with a maximum length of 3000 characters.
resolutionstringRequiredDefault: "2K"Clarity tier of the output image, provided as a string: 2K is standard quality, 4K is ultra-high definition; defaults to 2K.
2K4Kaspect_ratiostringRequiredDefault: "1:1"Aspect ratio of the generated image, provided as a string; defaults to 1:1.
1:14:33:416:99:162:33:221:9callbackobjectOptional
Terminal-state notification config. When omitted, no callback is delivered — poll the task yourself. See the callback note below.
Provide callback.url when creating a task and HiAPI POSTs to your service once the task reaches a terminal state — no polling needed. The callback payload mirrors the task detail structure; signature verification, delivery retries and idempotency are documented on the Unified Async API overview page.
urlstringRequiredRequired when callback is present. A POST is sent to this URL once the task reaches a terminal state; must be a valid http(s) URL.
whenstringOptionalDefault: "final"Only final is supported today — notified on both success and fail.
finalstoragestringOptionalDefault: "temp"Artifact storage tier: temp (default, retained about 7 days) or persistent (long-term, billed by size). Insufficient balance or exceeding the storage cap silently downgrades to temp; the effective tier is shown in the task detail response.
temppersistentRequest examples
# Submit an async task; returns a taskId immediately (no waiting for generation)
curl -X POST "https://api.hiapi.ai/v1/tasks" \
  -H "Authorization: Bearer $HIAPI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "seedream-4.5/text-to-image",
  "input": {
    "prompt": "…",
    "resolution": "2K",
    "aspect_ratio": "1:1"
  }
}'
const res = await fetch("https://api.hiapi.ai/v1/tasks", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.HIAPI_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
model: "seedream-4.5/text-to-image",
input: {
"prompt": "…",
"resolution": "2K",
"aspect_ratio": "1:1"
}
}),
});
const task = await res.json();
// { code: 200, message: "success", data: { taskId } }import os, requests
res = requests.post(
"https://api.hiapi.ai/v1/tasks",
headers={"Authorization": f"Bearer {os.environ['HIAPI_API_KEY']}"},
json={
"model": "seedream-4.5/text-to-image",
"input": {
"prompt": "…",
"resolution": "2K",
"aspect_ratio": "1:1"
}
},
)
print(res.json()) # { code, message, data: { taskId } }200 OK
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-01HZTQ8BX2N3GM3YFK4Z9D7VQR"
  }
}
400 Bad Request
{
  "code": 400,
  "message": "invalid request",
  "data": null,
  "error_code": "INVALID_REQUEST"
}
Get task detail
https://api.hiapi.ai/v1/tasks/:id Response fields
taskIdstringRequiredTask ID, always prefixed with tk-hiapi-.
modelstringRequiredResolved full model name. Tasks submitted with the route parameter return base@route (e.g. gpt-image-2/text-to-image@ext); otherwise identical to the name passed at creation.
routestringOptionalPresent only when the task was submitted with an explicit route parameter; echoes the submitted value.
statusstringRequiredTask status.
queued Queued, not started yet.
handling Being processed.
archiving Processing finished, artifacts being prepared.
success Terminal: completed, artifacts available (output returned).
fail Terminal: failed (error returned).
After submission, check status: success and fail are terminal, everything else is non-terminal. Poll every 1–3 seconds until terminal. On success, download artifacts from output[].url and transfer them before expireAt; pass storage: "persistent" at creation time when long-term retention is needed.
creatednumberRequiredTask creation time (Unix seconds).
completednumberRequiredUnix seconds when the task reached a terminal state; fixed to 0 while not terminal.
outputarrayOptional
Present only when status == success. Artifact list — always an array; a single task may return multiple types at once (e.g. video + first_frame).
Array [ object ]
Array items
urlstringRequiredArtifact URL, directly downloadable.
typestringRequiredCurrent possible values: video, image, audio, first_frame, last_frame, thumbnail; more may be added later.
expireAtnumberRequiredUnix seconds until which the artifact remains accessible; download or transfer before it expires.
errorobjectOptional
Present only when status == fail.
codestringRequiredBusiness error code.
messagestringRequiredError description.
Response examples
Success
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-01HZTQ8BX2N3GM3YFK4Z9D7VQR",
    "model": "happyhorse-1-0",
    "status": "success",
    "created": 1777282033,
    "completed": 1777282099,
    "output": [
      {
        "url": "https://cdn.hiapi.ai/tasks/.../video.mp4",
        "type": "video",
        "expireAt": 1777886899
      }
    ]
  }
}
Processing (non-terminal)
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-...",
    "model": "happyhorse-1-0",
    "status": "archiving",
    "created": 1777282033,
    "completed": 0
  }
}
Failed
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-...",
    "model": "happyhorse-1-0",
    "status": "fail",
    "created": 1777282033,
    "completed": 1777282099,
    "error": {
      "code": "TASK_FAILED",
      "message": "task failed"
    }
  }
}Articles
View all articles →Related Models
View all models →Same Type
-
 FLUX.2 Black Forest Labs $0.035 /image
-
 Qwen Image 3.0 Alibaba $0.036 /image
-
 Imagen 4 Google $0.030 /image
-
 FLUX.2 Klein 4B Black Forest Labs $0.0004 /image
-
 BRIA Eraser Bria $0.058 /image
-
 851 Labs Background Remover 851 Labs $0.002 /image
-
 Ideogram V4.5 Ideogram $0.011 /image
-
 GPT Image 2.5 OpenAI $0.017 /image
-
 Ideogram V4 Ideogram $0.050 /image
-
 FASHN Tryon v1.6 FASHN $0.107 /image
-
 FLUX.1 Fill Pro Black Forest Labs $0.071 /image
-
 Wan 2.7 Image Alibaba $0.035 /image



