
Guide
Gemini Omni 1.2 Flash Integration Guide: Input Modes, Parameters, and Spec-Based Billing
The minimal integration path for the public model gemini-omni-1.2-flash: input modes, parameter constraints, copyable requests, and resolution-based billing

On this page
Model and capability boundaries
HiAPI currently offers public access to gemini-omni-1.2-flash for outputting video. It supports text-to-video, first-frame image-to-video, first/last-frame transition, and reference-image-to-video. Video editing, continuation, video or audio input are not available, and the seed parameter is not provided.
Tasks are always submitted via POST /v1/tasks; the request body uses the structure {"model":"gemini-omni-1.2-flash","input":{...},"storage":"temp"}.
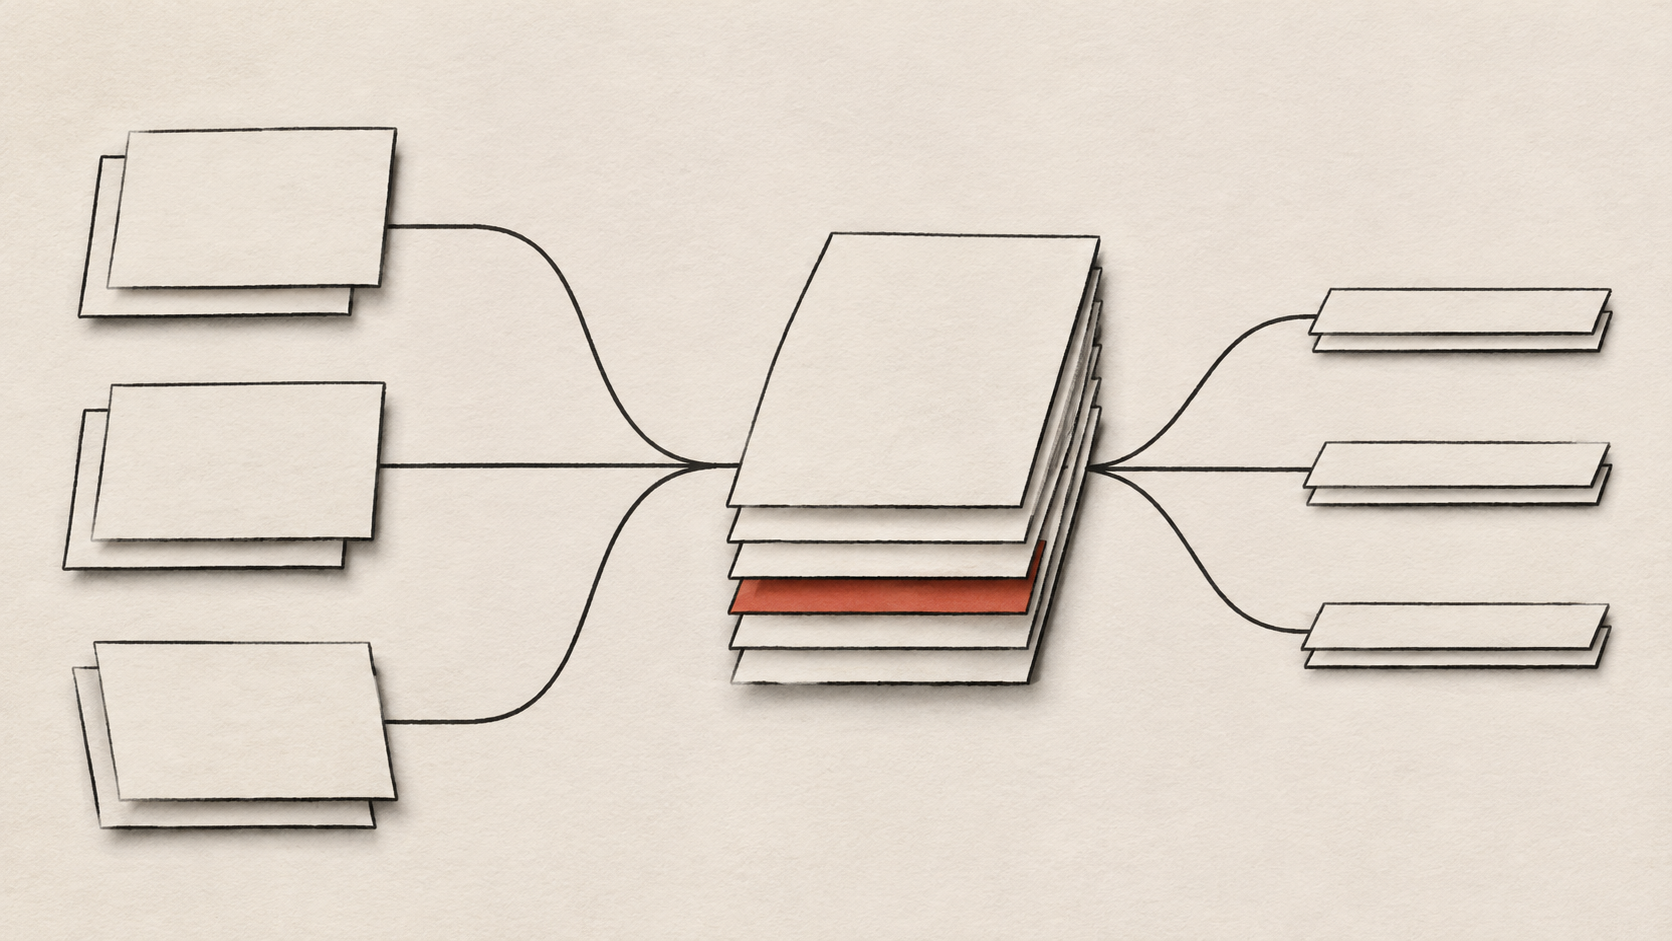
Input modes and mutual exclusion rules
Choose a mode based on the material:
- Text-to-video: pass only
prompt, with no image fields. - First-frame image-to-video: pass
promptandfirst_frame_url, using a public image to specify the starting frame. - First/last-frame transition: pass both
first_frame_urlandlast_frame_url;last_frame_urldepends onfirst_frame_url. This mode has a maximum length of 10 seconds and cannot includenegative_promptorsystem_prompt. - Reference-image-to-video: pass
promptandimage_urls, using 1–10 public HTTP(S) reference images to constrain style or subject. If only oneimage_urlsimage is passed, it remains a reference image, not a first frame.
image_urls is mutually exclusive with first_frame_url and last_frame_url and cannot be mixed in the same request. All image parameters accept only public HTTP(S) URLs; Base64 is not supported.
Parameters and default values
| Field | Type | Default | Constraint |
|---|---|---|---|
prompt | string | None, required | The only required field; non-empty, up to 20000 characters |
duration | integer | 10 | 3–15 seconds |
resolution | enum | 720p | 360p / 720p / 1080p / 4k; 1080p and 4k are upscaled outputs, and 4k may not include an audio track |
aspect_ratio | enum | 16:9 | 16:9 or 9:16 |
image_urls | array | None | 1–10 public HTTP(S) reference images; mutually exclusive with the first-frame/last-frame fields |
first_frame_url | string | None | Public HTTP(S) URL; can separately specify the starting frame |
last_frame_url | string | None | Public HTTP(S) URL; depends on first_frame_url; first/last-frame mode has a maximum length of 10 seconds and cannot include negative_prompt or system_prompt |
Do not assume that all modes include sound, lip sync, accurate text, or exact subject/brand consistency; none of these are guaranteed.
Two copyable POST /v1/tasks requests
The API Key in the calls is represented only by YOUR_API_KEY; no real key is written. Both requests use storage: "temp".
3-second 360p text-to-video
{
  "model": "gemini-omni-1.2-flash",
  "input": {
    "prompt": "A white paper airplane takes off from a desktop, glides past blue glass, and the camera slowly follows",
    "duration": 3,
    "resolution": "360p",
    "aspect_ratio": "16:9"
  },
  "storage": "temp"
}
10-second 720p first-frame image-to-video
The https://example.com/first-frame.png in the example is a placeholder address and must be replaced with a real, publicly accessible image before calling; it is not an actual test input.
{
  "model": "gemini-omni-1.2-flash",
  "input": {
    "prompt": "The building in the frame transitions from early morning to dusk, light moves slowly, and the camera pushes in slightly",
    "first_frame_url": "https://example.com/first-frame.png",
    "duration": 10,
    "resolution": "720p",
    "aspect_ratio": "16:9"
  },
  "storage": "temp"
}
Do not add image_urls to a first-frame image-to-video request; the two are mutually exclusive.
Submission, querying, and retry
After submission, save the returned task ID, query the task status and result via GET /v1/tasks/{id}, replacing {id} with the actual task ID. Query requests use the same API Key as submission requests.
If a network timeout occurs and the task ID has already been obtained, query the existing task first; if the task ID has not yet been obtained, retry submission with the original Idempotency-Key to recover the same task and avoid creating a duplicate task. Re-creating a task because the successful result is unsatisfactory will increase the budget.
Resolution-based billing and 10-second budget
The current default multiplier pricing is as follows:
| Resolution | Unit price (USD/second) |
|---|---|
| 360p | $0.0229 |
| 720p | $0.0343 |
| 1080p | $0.0343 |
| 4k | $0.0800 |
Budget = unit price of the selected resolution × requested duration × number of items. The budget for a single 10-second item is: 360p $0.229, 720p $0.343, 1080p $0.343, 4k $0.80.
Actual billing and applicable multipliers are subject to final settlement; billing cannot be inferred from the fractional seconds in the file container. Do not assume that failed tasks are always charged or always free, and do not estimate by doubling the cost per round or assuming text request costs are constant.
In one production verification on November 11, 2026, a 3-second 360p text-to-video task took about 34 seconds and was actually charged $0.0687, consistent with that specification's unit price multiplied by the requested duration. This sample does not mean that the quality and billing of other specifications or modes have all been tested.
Related articles
View all articles →-
Guide
Run Claude Code on Free DeepSeek: Set It Up Now, Start Nov 24
Claude Code, Python and curl setups you can verify for free today
4 min read -
Guide
How Much to Top Up This Black Friday: 18% Extra at $100, 30% at $500
Four budgets from $50 to $500, in video seconds and images
3 min read -
Guide
Get a DeepSeek API Key Before Black Friday 2026 + 4 More Steps
Key, test run, job queue, one top-up, and your local start time
3 min read