
Review
gpt-image-2-pro on hiapi: Pricing, Quality Tier, and How to Call the New Image Models
Two new Pro entries on hiapi — text-to-image at $0.35 and image-to-image at $0.42 — built for the small fraction of jobs where a bad render costs more than ten good ones.
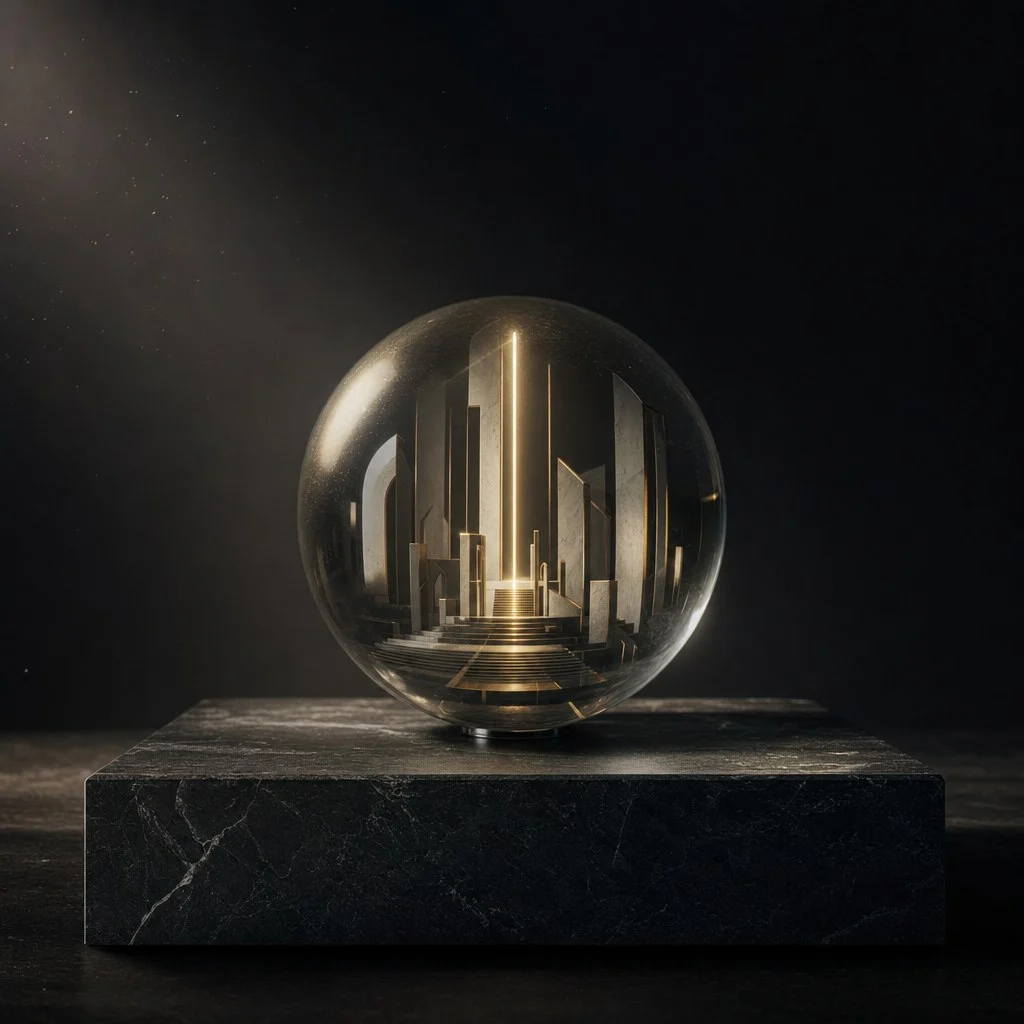
- Text-to-image Pro (1K)
- $0.35
- Image-to-image Pro (1K)
- $0.42
- 2K multiplier
- 2.0×
When hiapi's /api/pricing endpoint refreshed this month, two new entries climbed to the top of the image roster: gpt-image-2-pro and gpt-image-2-image-to-image-pro. Both wear the purple "Pro" badge. Both are pinned to the top of the model picker. Both cost more than ten times what the standard gpt-image-2 call does. So the obvious question is: what exactly are you paying for?
This piece walks through what the Pro variants actually are, what the live pricing matrix looks like, and how to call each one through hiapi's unified task API. If you are deciding whether to pay $0.35 a frame on top of an existing pipeline, the math you need is below.
What "Pro" Means On The Pricing Page
Both new entries describe themselves in the official pricing payload as "高质稳定档" — a stability-first tier built for production runs where success rate and latency need to be predictable, not just average-case good.
That phrasing matters more than it looks. gpt-image-2 standard at $0.03 a call is excellent for exploration, for batch fan-outs, for anything where a few duds in a hundred are fine because you regenerate cheaply. Pro is the variant you reach for when a single failed image is more expensive than ten extra dollars of compute — a scheduled marketing render that has to come out clean the first time, a paid-ad asset where the next attempt costs you a publishing window, a hero shot blocking a release.
The image-to-image Pro variant adds one more capability: it takes one to five reference images alongside the prompt, then edits, composites, or restyles them. Same stability promise, same Pro tier, just a different input shape.
The Live Pricing Matrix
Confirmed against the live pricing page at the time of writing — that page is the source of truth and the numbers below come straight from it:
| Model | 1K (1024 class) | 2K | Notes |
|---|---|---|---|
gpt-image-2 (standard, text-to-image) |
$0.03 | $0.04 | Exploration tier; 4K also available |
gpt-image-2-pro (text-to-image) |
$0.35 | $0.70 | Stability tier, pinned rank 1 |
gpt-image-2-image-to-image-pro |
$0.40 | $0.80 | 1–5 reference images, edit / composite |
A few practical reads:
- Pro is ~12–14× standard at 1K, ~17–21× at 2K. That is a real budget delta. If you cannot articulate why this specific image needs Pro, you probably want standard.
- 2K is a flat 2× multiplier on Pro. Unlike some image vendors that taper the high-resolution surcharge, the Pro variants double cleanly. Easy to forecast.
- Image-to-image runs about 14% above text-to-image at both tiers ($0.40 vs $0.35 at 1K, $0.80 vs $0.70 at 2K). You are paying for the additional reference-image processing.
For comparison, gpt-image-2 standard uses a different shape: 1K = $0.03, 2K = $0.04 (1.33× multiplier), 4K = $0.06 (2× multiplier). The standard variant exposes a 4K tier; the Pro variants currently top out at 2K but at materially higher fidelity per pixel. If you need raw resolution, standard at 4K is still the cheapest path to a large canvas; if you need consistent, production-grade quality, Pro at 2K is the call.
When Pro Earns Its Keep
The Pro tier is a stability bet, not a magic-quality button. The cases where it pays for itself share a shape: the cost of regeneration is high, and the cost of an off-render is asymmetric.
Pay for Pro when:
- The image is shipping to a customer-facing surface that will be reviewed before the next batch (paid ads, marketing emails, press kit, store hero).
- You need character or product consistency across a small set of renders and cannot afford one frame to drift.
- You have a stability SLA you are accountable for — a scheduled job that has to produce a usable image inside a known time window.
- The downstream pipeline is expensive: human review, brand approval, manual touch-up. Cheaper to spend a bit more per image on input than to send a bad render down the chain.
Stay on standard when:
- You are running large fan-outs (50, 500, 5000 images) where you score-and-filter on output.
- You are exploring prompts, not shipping them. Pro on a draft is wasted money.
- The image lives in a non-critical surface (blog body filler, internal slide, dev fixture) and a regeneration is one click away.
The image-to-image Pro variant has a narrower band: it is overwhelmingly the right call when you have a reference asset that the brand cares about — a product photo, a designer-approved character sheet, a campaign moodboard — and you need an edit that does not break what made the reference work. Spending $0.40 to keep a $4,000 product shoot's lighting consistent across twelve variants is obvious math.
Calling The Models From hiapi
Both Pro variants speak hiapi's unified task API: POST /v1/tasks creates the job and returns a task ID, GET /v1/tasks/:id reports status and, on success, a downloadable image URL in output[]. You hand them a prompt in input (plus, for image-to-image, one to five reference image URLs).
Text-to-image Pro
import time, requests

API = "https://api.hiapi.ai/v1/tasks"
HEADERS = {"Authorization": f"Bearer {HIAPI_TOKEN}"}

resp = requests.post(API, headers=HEADERS, json={
    "model": "gpt-image-2-pro",
    "input": {
        "prompt": "A pristine editorial magazine cover composition: a single "
                  "matte glass sphere resting on a polished dark slate plinth, "
                  "refracted interior architecture, studio key light, fine-grain "
                  "film texture, premium dark fashion-magazine aesthetic.",
        "aspect_ratio": "1:1",
        "resolution": "1K",
    },
}).json()
task_id = resp["data"]["taskId"]

while True:
    task = requests.get(f"{API}/{task_id}", headers=HEADERS).json()["data"]
    if task["status"] in ("success", "fail"):
        break
    time.sleep(5)

open("hero.png", "wb").write(
    requests.get(task["output"][0]["url"]).content)
For 2K output, set "resolution": "2K" (and pick whatever aspect ratio your asset needs). The billing engine multiplies cleanly — one call, $0.70.
Image-to-image Pro
The image-to-image variant accepts one to five reference image URLs in the input_urls array. References are hosted URLs — if yours live on disk, upload them somewhere reachable (object storage, your CDN) and pass the links.
import time, requests

API = "https://api.hiapi.ai/v1/tasks"
HEADERS = {"Authorization": f"Bearer {HIAPI_TOKEN}"}

resp = requests.post(API, headers=HEADERS, json={
    "model": "gpt-image-2-image-to-image-pro",
    "input": {
        "prompt": "Restyle the product photo into a vintage Polaroid look: "
                  "warm tones, soft vignetting, retain product silhouette and "
                  "logo placement exactly. Magazine-grade output.",
        "input_urls": ["https://your-cdn.example.com/reference-product.png"],
        "aspect_ratio": "1:1",
        "resolution": "1K",
    },
}).json()
task_id = resp["data"]["taskId"]

while True:
    task = requests.get(f"{API}/{task_id}", headers=HEADERS).json()["data"]
    if task["status"] in ("success", "fail"):
        break
    time.sleep(5)

open("restyled.png", "wb").write(
    requests.get(task["output"][0]["url"]).content)
Two things worth knowing for production traffic:
- A Pro render takes 60–120 seconds end to end. The async flow means nothing is held open while you wait — poll every few seconds, or set
callback.urlon the create call and let hiapi notify your server at the terminal state. - If you front this from a serverless worker, persist the
taskIdand let a poller or the callback pick up the result — do not hold an invocation open across a Pro generation.
A Practical Routing Pattern
For teams that already run gpt-image-2 at $0.03, the cleanest way to adopt Pro is to keep the standard tier as your default and route to Pro only on a marked subset of jobs. A minimal pattern:
def pick_model(job):
    if job.get("tier") == "hero" or job.get("brand_critical"):
        return "gpt-image-2-pro"
    if job.get("reference_image"):
        return "gpt-image-2-image-to-image-pro" \
            if job.get("brand_critical") else "gpt-image-2/image-to-image"
    return "gpt-image-2/text-to-image"
Tag your jobs at submission time (one field, one boolean), and your bill stays predictable. The Pro variants then act as a precision tool rather than a default — which is the shape they were designed for.
The Short Version
gpt-image-2-pro and gpt-image-2-image-to-image-pro are not "better gpt-image-2." They are the stability-tier entries in the same model family — built for the small fraction of your jobs where one bad render costs you more than ten good renders. Standard at $0.03 still wins for exploration and batch work. Pro at $0.35 (or $0.40 with references) is what you reach for when the image is the deliverable, not a draft.
Confirm the live numbers on the pricing page, mark the jobs that genuinely need stability, and route accordingly. Both models answer at POST /v1/tasks — the same task shape your existing gpt-image-2 worker already speaks.
Related articles
View all articles →-
Review
Most Realistic AI Image Generator: 4 Models Tested Head-to-Head
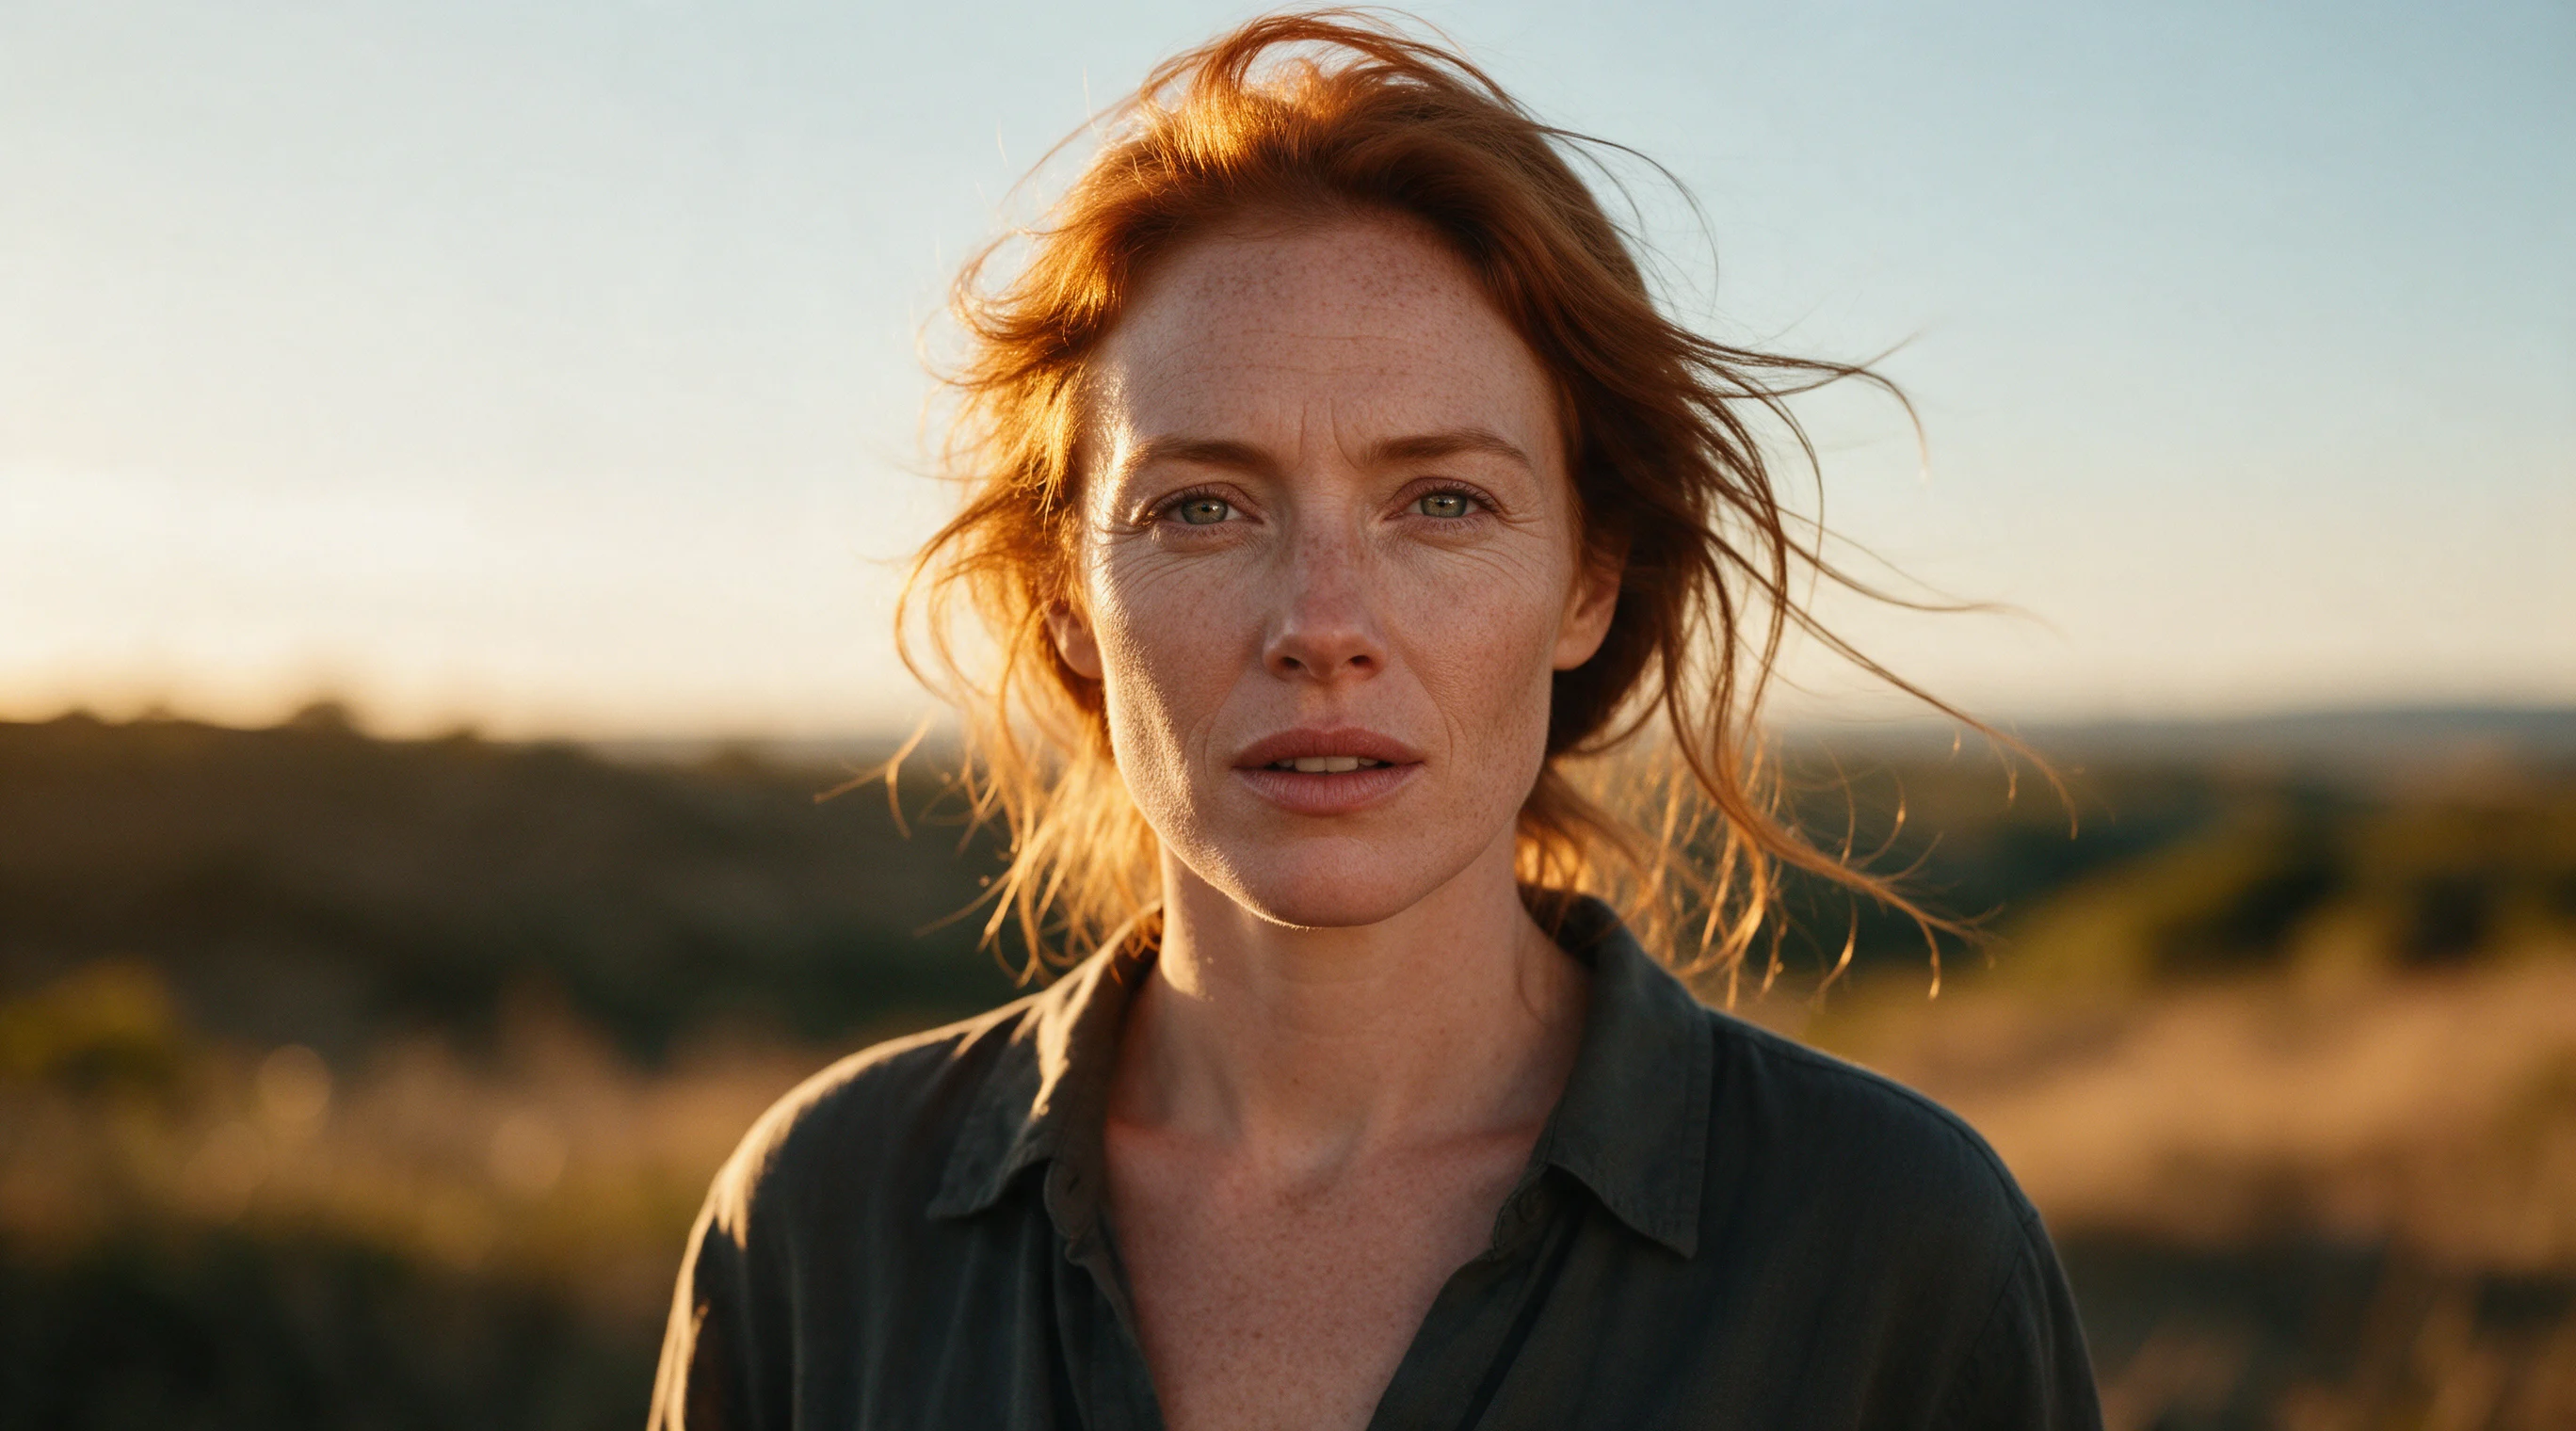
We ran the identical photorealistic portrait prompt through Seedream 5.0 Pro, Nano Banana 2, Qwen Image 3.0 Pro, and FLUX.2 to see which one actually nails skin, light, and detail — plus what each one costs per image.
7 -
Review
GPT Image 2 Review: A Hands-On Honest Take
What holds up, what doesn't, and where it actually belongs in your workflow
9 -
Review
GPT Image 2 Review: Image Quality, Text and Speed Tested
Based on three same-prompt samples from May 2026, with the real comparison images kept and the current model, routes and migration notes updated
7