
Alibaba
Qwen Image 3.0
qwen-image-3.0-pro/text-to-image
Alibaba's third-generation image generation and editing model, skilled at dense layout and multilingual text rendering under long prompts, and supports reference-image editing
Try qwen-image-3.0-pro/text-to-image
Input
Showcases
View all showcasesOutput
image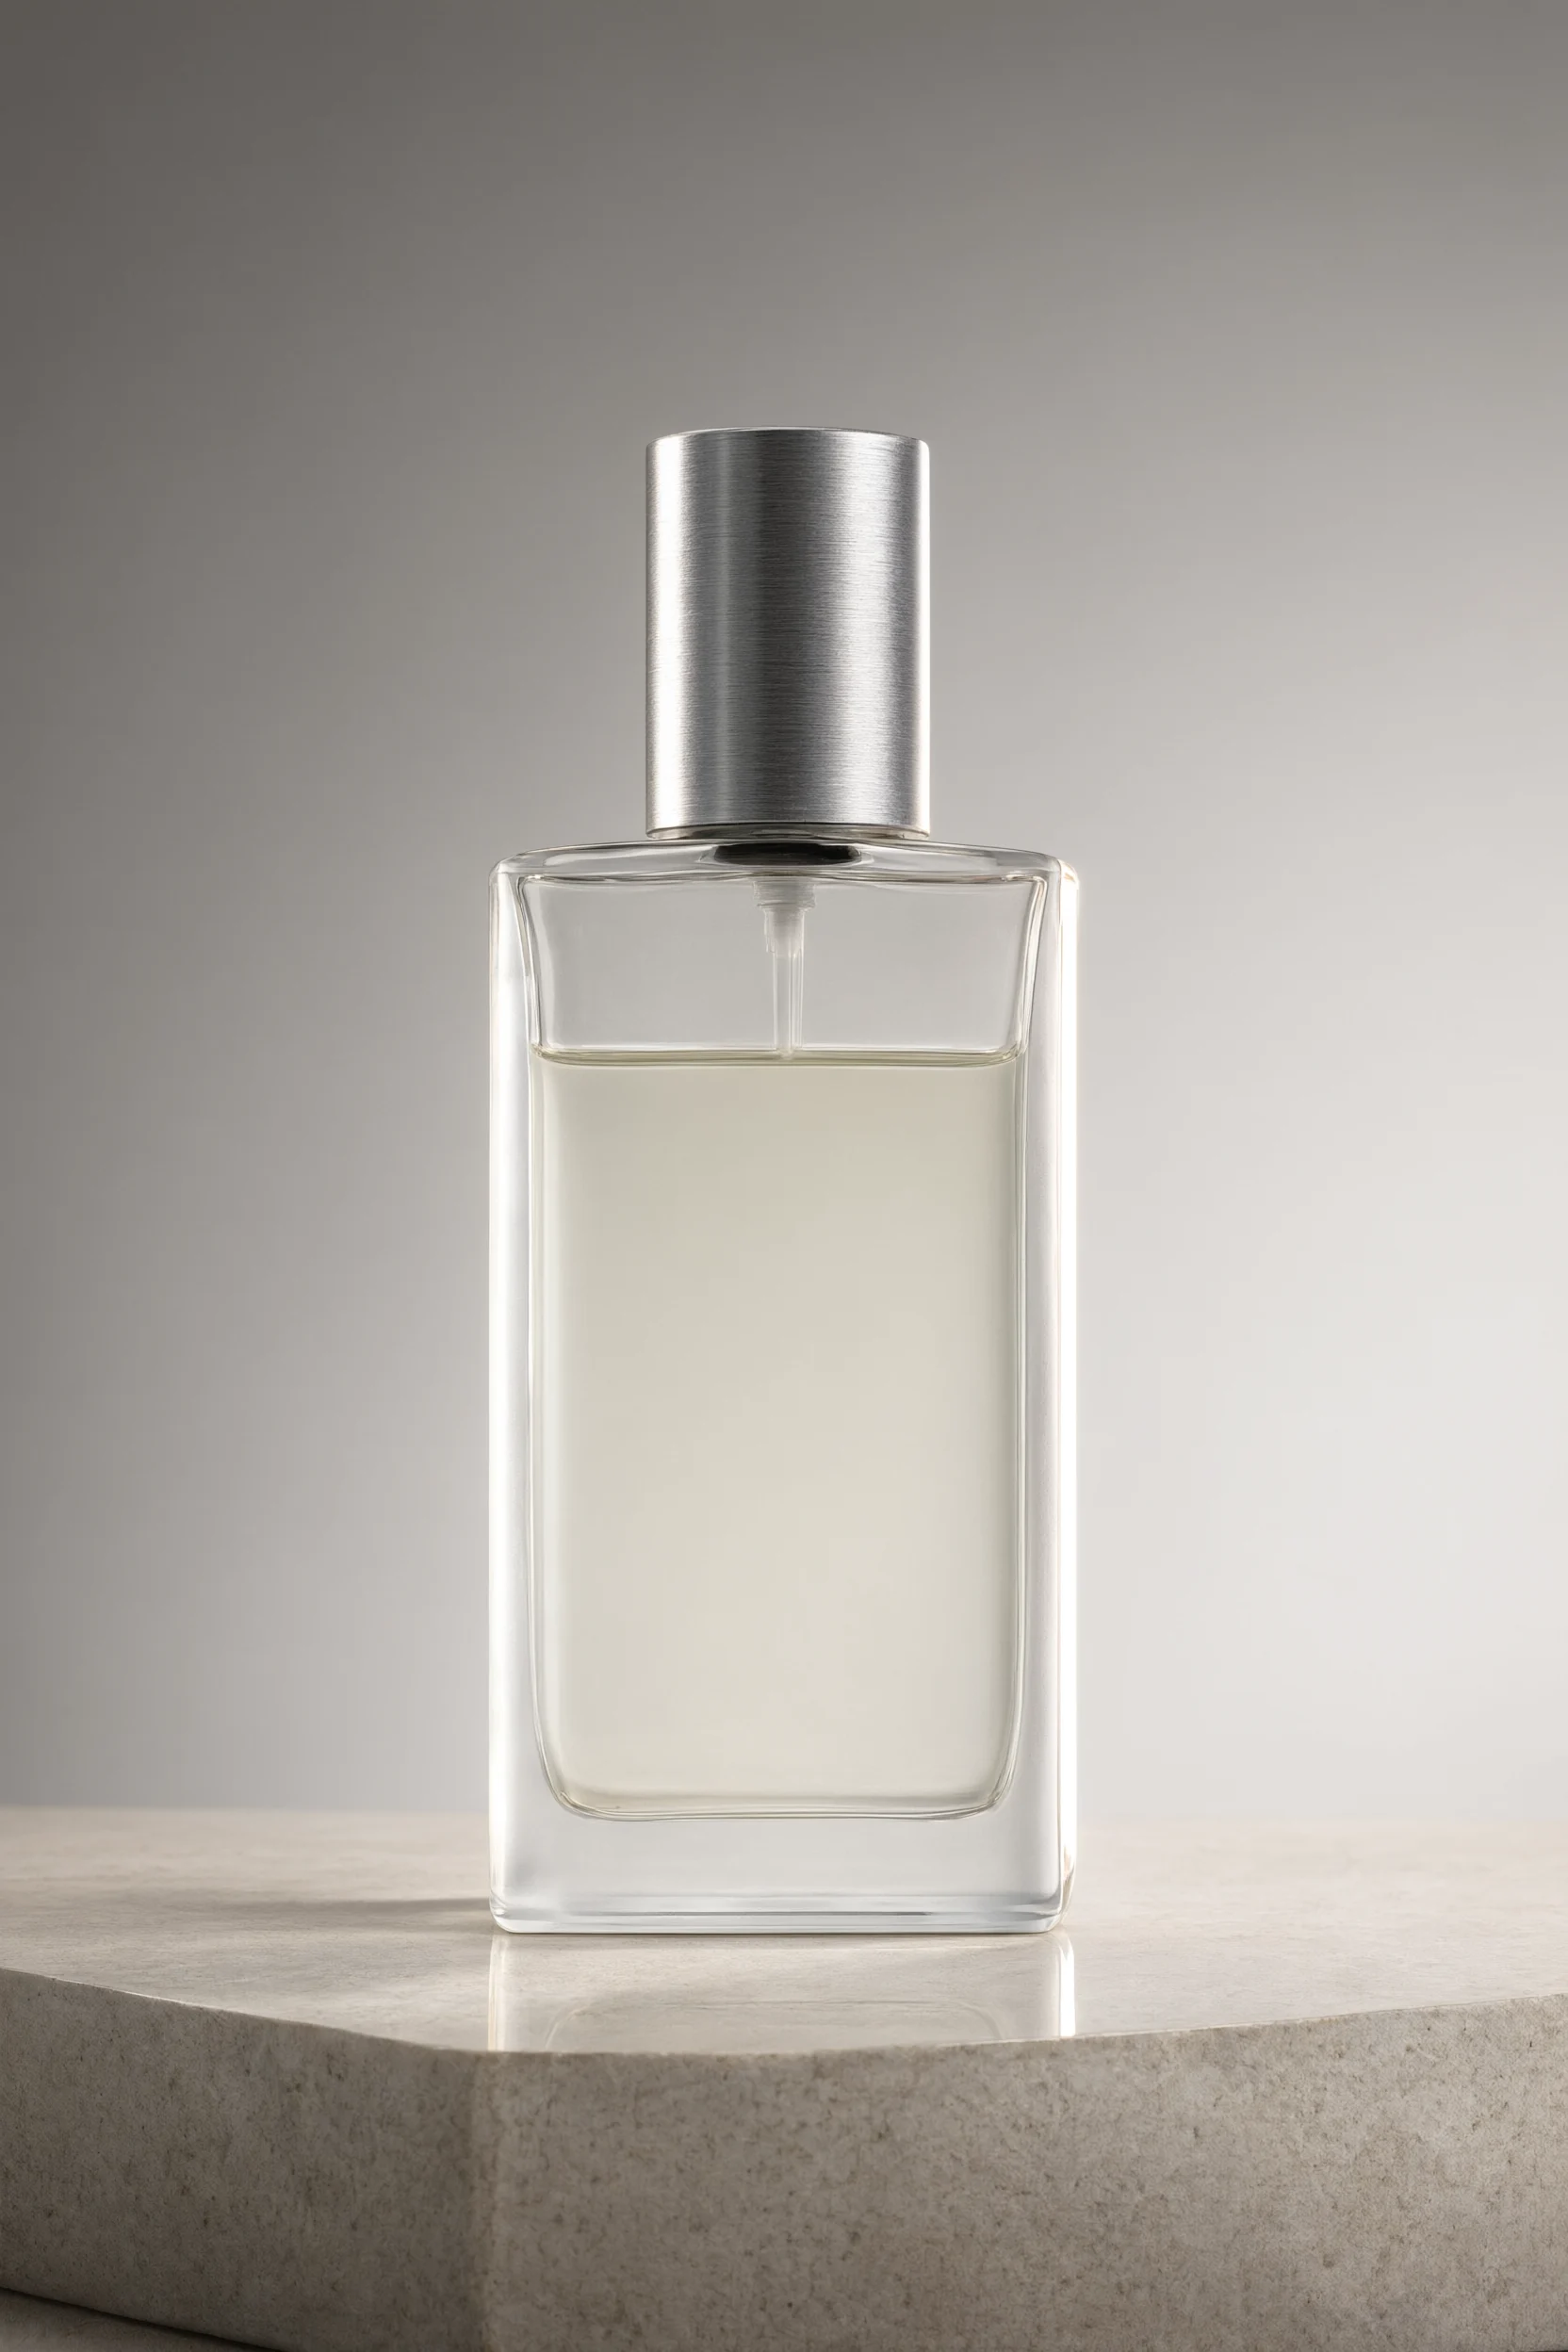
E-commerce Product Photography: Prompt Structure and Image Quality
Style Product Image · ecommerce · Studio lighting
Prompt
E-commerce product photography: a matte glass perfume bottle with a brushed aluminum cap, centered on a light warm gray stone pedestal. Studio lighting setup: a large softbox key light from the upper left creates a soft vertical highlight along the left edge of the bottle, a narrow strip rim light on the right separates the bottle silhouette from the seamless gradient background, and a subtle frontal fill reflection ensures the label area is clearly legible. On the polished stone surface, a contact shadow and a slight, controlled reflection are visible. Shot with an 85mm macro lens at f/8, the product is fully in focus with minimal distortion, and the eye level is slightly above the base of the bottle. Low-saturation neutral tones with only one low-saturation accent color, leaving clean negative space at the top for typography. Photorealistic material rendering: the transparent liquid has correct refraction, delicate glass thickness, the metal surface shows brushed micro-texture, and the surface is dust-free. 16:9 horizontal composition, commercial catalog aesthetic style, high dynamic range, no text, no logo.
Copy the full prompt and adapt it for your own generation.
Tags
Pricing
qwen-image-3.0-pro/text-to-image per image
| Specifications | Unit Price |
|---|---|
| 1K | $0.0497 |
| 2K | $0.0993 |
Overview
Qwen Image 3.0 Pro is the text-to-image model in Alibaba's Qwen series, focused on production-grade images that carry real information: a single image can lay out dense content such as infographics, newspaper pages, interface concept drafts, and product grids, and render multilingual text with correct layout. It targets developers who need to reliably turn long prompts into usable visual assets, and suits batch image generation for design, content, e-commerce, and education applications.
Highlights
- Long prompts support complex layouts — prompts can be up to 18,000 characters, enough to describe multi-block layouts, hierarchy, and the copy for each block.
- Text and layout rendering are the focus — aimed at generating images with dense elements and text, reducing the rework of adding and typesetting text after generation.
- Controllable parameters cover common generation needs — supports aspect ratio, 1K/2K resolution, png/jpeg formats, negative prompts, and seed-based reproducibility.
Capabilities
Long-text prompt generation: Pass a complete image description through the prompt field, supporting lengthy layout and element specifications; a single call produces the finished image directly, reducing step-by-step assembly.
Controlled resolution and aspect ratio: resolution can be 1K or 2K, and aspect_ratio covers 1:1, 3:2, 2:3, 4:3, 3:4, 16:9, 9:16, and 21:9, making it easy to generate the exact size for a given placement.
Automatic prompt enhancement and negative constraints: prompt_extend is enabled by default, automatically completing and refining the prompt; negative_prompt excludes content you do not want, improving generation stability.
Random seed reproducibility: A seed parameter is available; entering a seed from 0 to 2147483647 reproduces the same result, making parameter tuning comparisons and batch workflows stable.
Direct format output: output_format supports png and jpeg, letting you choose the file format directly for downstream use and skip extra transcoding steps.
Use Cases
- Content teams: generate posters and layouts from long copy — Write headlines, body text, and layout requirements into the prompt to produce posters or newspaper-style pages containing text, ready for content publishing and operational materials.
- Design developers: interface concept generation — Generate UI concept images and high-fidelity mockups in 16:9 or 9:16 as visual references for product reviews and front-end implementation.
- E-commerce operations: product display image creation — Generate product grids and display images in 1:1 or 4:3, and use a fixed seed to batch-produce marketing assets with a consistent style.
- Education: mixed text-and-image instructional materials — Use long prompts to describe the structure of knowledge points and generate explanatory images with text and graphics side by side for courseware and training materials.
Limitations and Selection Advice
The model is positioned for informational visual production; images are dense with elements and contain text, and it is not the first choice for purely aesthetic illustration or artistic creation. Prompts must clearly specify layout and copy, placing high demands on descriptive ability; complex multi-image reference composition is outside the scope of this pipeline (this pipeline is text-to-image only). Results are affected by layout density and language, so before formal batch generation you should validate with small samples and control stability using a fixed seed and negative prompts.
What's new
View changelog →- New model New model available: qwen-image-3.0-pro/text-to-image
- New model qwen-image-3.0-pro image-to-image model now live
- New model New model docs
Frequently asked questions
View all FAQs →-
How many references does Qwen Image 3.0 Image to Image accept?
It accepts 1 to 3 reference images. At least one is required in input.image_urls.
-
How does standard editing differ from Pro?
Standard prioritizes lower cost and rapid iteration. Pro is better for exact text replacement, complex materials, and final layouts.
-
How are 1K, 2K, and reference images billed?
1K and 2K use the same output tier, and each reference adds a fee. See the live page price for current amounts.
-
How do I reduce subject, layout, or text drift?
Separate what should change from the subject, text, position, material, camera, and lighting that must remain fixed. Put exact replacement text in quotation marks.
Create a generation task
https://api.hiapi.ai/v1/tasks Headers
AuthorizationstringRequiredAccount API key. Required on every request. Example: Bearer YOUR_HIAPI_API_KEY. Get your API key
Content-TypestringOptionalThe request body is always parsed as JSON; when sent, only application/json (optionally with charset) is accepted — any other value returns 415. Example: application/json.
Idempotency-KeystringOptionalIdempotency key, up to 255 bytes. Retries with the same key from the same account create the task only once; replays return the original taskId.
On network timeouts or client retries, the same key creates the task only once — no double charges (scope: the API key's account). Use a business-unique identifier as the key (e.g. "order-42"); replays return the original taskId, and keys expire 24 hours after the first request. See the Unified Async API overview for the full scenario matrix.
Body
modelstringRequiredCurrent fixed value: qwen-image-3.0-pro/text-to-image
routestringOptionalCurrent fixed value: default
inputobjectRequired
Business parameters for qwen-image-3.0-pro/text-to-image and route default — see the parameter table below.
seedintegerOptionalmin 0max 2147483647Random seed used to control the randomness of generation; the value is an integer, and the same seed can reproduce similar generation results.
promptstringRequiredminLength 1maxLength 18000Positive prompt, a string describing the content, style, and composition of the desired image; it is the main basis for image generation.
resolutionstringOptionalDefault: "1K"Output resolution tier, a string specifying the resolution level of the generated image; default is 1K.
1K2Kaspect_ratiostringOptionalDefault: "1:1"Aspect ratio of the output image, specified as a string; default is 1:1.
1:13:22:34:33:416:99:1621:9output_formatstringOptionalDefault: "png"File format of the generated image, specified as a string; default is png.
pngjpegprompt_extendbooleanOptionalDefault: trueWhether to automatically optimize the prompt, a boolean; default is true. When enabled, the input prompt is automatically expanded and optimized.
negative_promptstringOptionalDefault: ""maxLength 500Negative prompt, describing content that should not appear in the image; a string, defaulting to an empty string.
callbackobjectOptional
Terminal-state notification config. When omitted, no callback is delivered — poll the task yourself. See the callback note below.
Provide callback.url when creating a task and HiAPI POSTs to your service once the task reaches a terminal state — no polling needed. The callback payload mirrors the task detail structure; signature verification, delivery retries and idempotency are documented on the Unified Async API overview page.
urlstringRequiredRequired when callback is present. A POST is sent to this URL once the task reaches a terminal state; must be a valid http(s) URL.
whenstringOptionalDefault: "final"Only final is supported today — notified on both success and fail.
finalstoragestringOptionalDefault: "temp"Artifact storage tier: temp (default, retained about 7 days) or persistent (long-term, billed by size). Insufficient balance or exceeding the storage cap silently downgrades to temp; the effective tier is shown in the task detail response.
temppersistentRequest examples
# Submit an async task; returns a taskId immediately (no waiting for generation)
curl -X POST "https://api.hiapi.ai/v1/tasks" \
  -H "Authorization: Bearer $HIAPI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "qwen-image-3.0-pro/text-to-image",
  "input": {
    "prompt": "…",
    "resolution": "1K",
    "aspect_ratio": "1:1",
    "output_format": "png",
    "prompt_extend": true,
    "negative_prompt": ""
  }
}'
const res = await fetch("https://api.hiapi.ai/v1/tasks", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.HIAPI_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
model: "qwen-image-3.0-pro/text-to-image",
input: {
"prompt": "…",
"resolution": "1K",
"aspect_ratio": "1:1",
"output_format": "png",
"prompt_extend": true,
"negative_prompt": ""
}
}),
});
const task = await res.json();
// { code: 200, message: "success", data: { taskId } }import os, requests
res = requests.post(
"https://api.hiapi.ai/v1/tasks",
headers={"Authorization": f"Bearer {os.environ['HIAPI_API_KEY']}"},
json={
"model": "qwen-image-3.0-pro/text-to-image",
"input": {
"prompt": "…",
"resolution": "1K",
"aspect_ratio": "1:1",
"output_format": "png",
"prompt_extend": True,
"negative_prompt": ""
}
},
)
print(res.json()) # { code, message, data: { taskId } }200 OK
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-01HZTQ8BX2N3GM3YFK4Z9D7VQR"
  }
}
400 Bad Request
{
  "code": 400,
  "message": "invalid request",
  "data": null,
  "error_code": "INVALID_REQUEST"
}
Get task detail
https://api.hiapi.ai/v1/tasks/:id Response fields
taskIdstringRequiredTask ID, always prefixed with tk-hiapi-.
modelstringRequiredResolved full model name. Tasks submitted with the route parameter return base@route (e.g. gpt-image-2/text-to-image@ext); otherwise identical to the name passed at creation.
routestringOptionalPresent only when the task was submitted with an explicit route parameter; echoes the submitted value.
statusstringRequiredTask status.
queued Queued, not started yet.
handling Being processed.
archiving Processing finished, artifacts being prepared.
success Terminal: completed, artifacts available (output returned).
fail Terminal: failed (error returned).
After submission, check status: success and fail are terminal, everything else is non-terminal. Poll every 1–3 seconds until terminal. On success, download artifacts from output[].url and transfer them before expireAt; pass storage: "persistent" at creation time when long-term retention is needed.
creatednumberRequiredTask creation time (Unix seconds).
completednumberRequiredUnix seconds when the task reached a terminal state; fixed to 0 while not terminal.
outputarrayOptional
Present only when status == success. Artifact list — always an array; a single task may return multiple types at once (e.g. video + first_frame).
Array [ object ]
Array items
urlstringRequiredArtifact URL, directly downloadable.
typestringRequiredCurrent possible values: video, image, audio, first_frame, last_frame, thumbnail; more may be added later.
expireAtnumberRequiredUnix seconds until which the artifact remains accessible; download or transfer before it expires.
errorobjectOptional
Present only when status == fail.
codestringRequiredBusiness error code.
messagestringRequiredError description.
Response examples
Success
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-01HZTQ8BX2N3GM3YFK4Z9D7VQR",
    "model": "happyhorse-1-0",
    "status": "success",
    "created": 1777282033,
    "completed": 1777282099,
    "output": [
      {
        "url": "https://cdn.hiapi.ai/tasks/.../video.mp4",
        "type": "video",
        "expireAt": 1777886899
      }
    ]
  }
}
Processing (non-terminal)
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-...",
    "model": "happyhorse-1-0",
    "status": "archiving",
    "created": 1777282033,
    "completed": 0
  }
}
Failed
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-...",
    "model": "happyhorse-1-0",
    "status": "fail",
    "created": 1777282033,
    "completed": 1777282099,
    "error": {
      "code": "TASK_FAILED",
      "message": "task failed"
    }
  }
}Articles
View all articles →Related Models
View all models →Same Type
-
 Ideogram V3 Character Ideogram $0.090 /image
-
 Qwen Image 2.1 Alibaba $0.020 /image
-
 Google Virtual Try-On Google $0.107 /image
-
 Muse Image 1.0 Meta $0.015 per task
-
 Recraft Creative Upscale Recraft $0.357 /image
-
 Wan 2.7 Image Alibaba $0.035 /image
-
 GPT Image 2.5 OpenAI $0.017 /image
-
 Qwen Image 2.0 Alibaba $0.042 /image
-
 Z-Image Alibaba $0.008 /image
-
 Nano Banana 2 Lite Google $0.033 /image
-
 Nano Banana Pro Google $0.057 /image
-
 Nano Banana 2 Google $0.036 /image
Same Provider
- Qwen Image 2.0 Alibaba $0.042 /image
-
 Qwen Image 3.0 Alibaba $0.036 /image
- Qwen Image 2.1 Alibaba $0.020 /image
-
 Qwen Audio 3.0 TTS Alibaba $0.030 /1,000 characters
-
 Wan 3.0 Video Alibaba $0.040 /second
-
 HappyHorse 1.0 Alibaba $0.168 /second
-
 HappyHorse 1.1 Alibaba $0.160 /second
- Wan 2.7 Image Alibaba $0.035 /image
- Z-Image Alibaba $0.008 /image
-
 Wan 2.7 Video Alibaba $0.100 /second
-
 Wan 2.6 Flash Alibaba $0.043 /second