
Tutorial
flux-3-max/keyframes-to-video in Practice: 5 High-Value Image-to-Video Application Scenarios
From Keyframes to Final Cuts: Scenario Selection, Integration Essentials, and Cost Estimation for Developers
Why Use Keyframes for Video Instead of Pure Text Generation
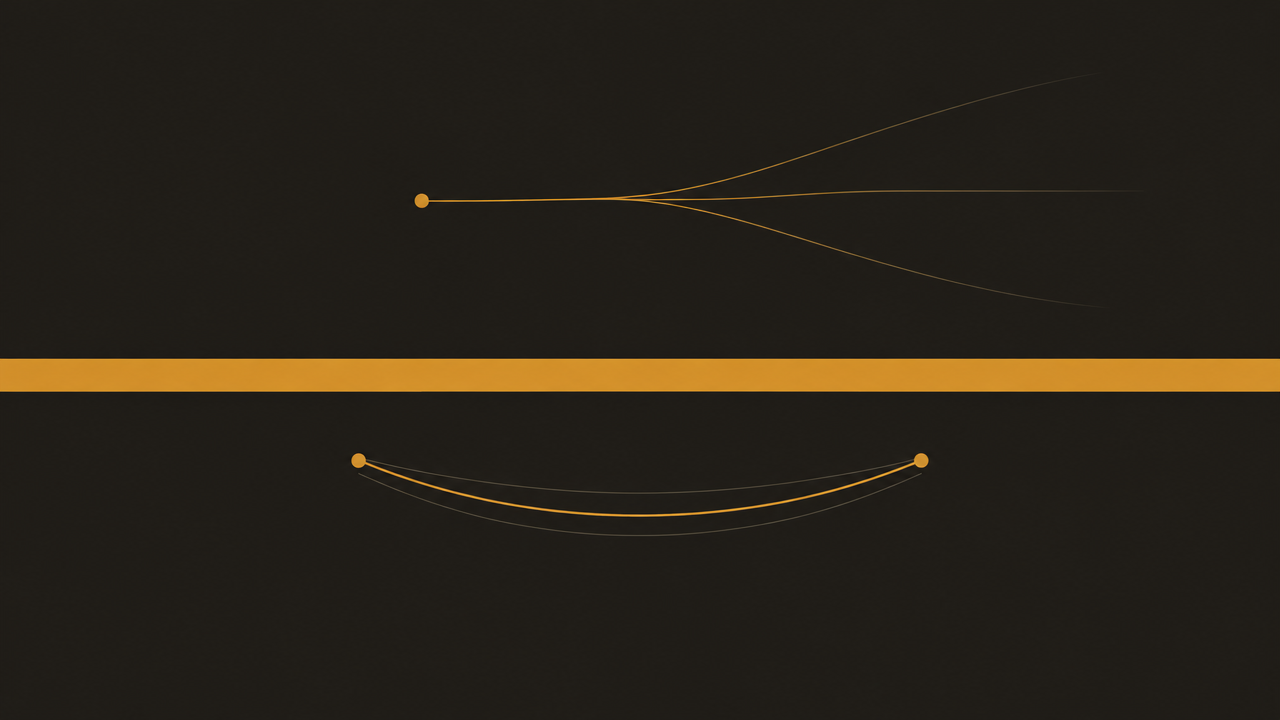
Text-to-video takes only a text prompt as input, leaving the model free to explore a space where "anything is possible"; keyframes (image-to-video), by contrast, first pin down the first frame and, when needed, a last frame, so the model only has to fill in motion between two given anchors. For developers, this difference directly determines business controllability.
Pure text generation has three typical problems: repeated calls with the same prompt may drift in composition, character orientation, and product angle; the visual subject may not match brand assets, requiring manual secondary screening; and once the result is unsatisfactory, you can only reword and rerun, with very limited debugging space.
The keyframe approach moves this uncertainty forward onto static images you can already control precisely—images can come from designers, rendering pipelines, or product image libraries, and the video model's job is to "make this image move." This makes the floor of deliverables predictable and gives failure troubleshooting a clear direction: first check whether the image is right, then check whether the motion is right.
This article uses Black Forest Labs' flux-3-max/keyframes-to-video as an example; its output type on HiAPI.ai is video, its capability is image-to-video, and billing is by output seconds. Below, we break down the selection criteria, keyframe design approach, and integration essentials across 5 scenario types.
Scenario 1: Dynamic E-commerce Product Hero Images and Short Video Assets
The most direct use: take a product image on a white background or in a scene as the first frame and generate a few seconds of dynamic footage for the detail page hero, feed assets, or on-site recommendation slots.
Selection Criteria
- The product itself has clear motion semantics: liquid pouring, fabric draping, accessory rotation, light sweeping across a surface.
- The static image is high enough quality and the subject edges are clean; blurry or heavily compressed images will amplify flaws in the final video.
- The SKU count is large and assets update frequently, so manual shooting cannot keep up.
Keyframe Design
The first frame determines composition, so crop the product image to the target aspect ratio beforehand; do not expect the model to recompose it for you. If there is a clear end state (for example, a lid closes or packaging rotates upright), also pass the last frame as an anchor to significantly reduce motion drift; if unsure, it is better to omit the last frame, provide only the first frame, and request small motion amplitude.
The prompt should describe only motion and not repeat the product itself—the product information is already carried by the image; the more focused the prompt, the less likely the model is to "improvise."
Duration and Cost Trade-off
E-commerce assets usually need only a few seconds of looping-style footage. Billing by output seconds means duration is the main cost switch: first confirm how long the placement actually needs, then decide the generation length, rather than uniformly generating at the maximum length and trimming. For batch scenarios, it is advisable to run a small number of SKUs to validate image quality before scaling up.
Scenario 2: Extended Motion Effects for Brand Key Visuals and Marketing Assets
A brand key visual (KV) is usually a carefully designed static image, and marketing teams need it to appear in splash screens, short video covers, building screens, and multi-size social media versions, where the motion version is often the most expensive part.
Fit Points
Using the KV as the first frame can generate slight camera pushes, flowing light effects, and eased background elements, making the same key visual feel like "a single piece of footage" across channels rather than a simple static placement.
How to Ensure Visual Consistency
- Generate in batches by size rather than one image for all: first crop an appropriate first frame for each channel's aspect ratio, then generate separately. Forcing the model to change aspect ratio during generation carries higher composition risk.
- Write "what not to move" in the prompt: explicitly require the subject position, logo area, and text area to remain stable, with motion occurring only in the background layer.
- Control motion amplitude: brand assets pursue restraint, so prompts should emphasize slow, small-scale, loop-friendly motion.
Boundaries to Know in Advance
Keyframe video models are not responsible for layout; text and logos within the frame should be finalized at the static image stage before generation. If the motion version requires precise transition rhythm or beat-synced editing with music, such needs are better handled through traditional editing, using generated clips as source material.
Scenario 3: Storyboard Previs for Games and Animation
Previs needs to answer "is this rhythm right, does this camera language work," not final image quality. In traditional pipelines, validating these questions requires modeling, rigging, and rendering, which is costly and slow; generating intermediate transitions from two keyframes lets you get a discussable motion draft within minutes.
How It Works
Create one static keyframe each for shot A and shot B, pass them as the first and last frames, and generate the transitional segment between them. Stitching multiple segments together forms a playable previs timeline for checking edit points, shot lengths, and action continuity.
Integration Essentials
- The first and last frames' compositions must connect: camera position and subject scale in the two frames should be broadly continuous; otherwise the model will generate large camera movements to "bridge" them, which looks less like a real shot.
- Validate one thing at a time: to validate rhythm, fix the camera; to validate camera movement, reduce action elements—avoid mixing multiple variables, which makes rework judgment difficult.
- Output is process material: previs clips do not enter final delivery, so lower resolution and shorter duration are acceptable to reduce cost.
Inapplicable Boundaries
Requirements that must strictly match actual playable in-game viewpoints, or must exactly match existing skeletal animation, are not suitable for replacement by generative models; the value of previs lies in rapid trial and error, not in replacing formal production.
Scenario 4: Templated Creation for Social and Content Platforms
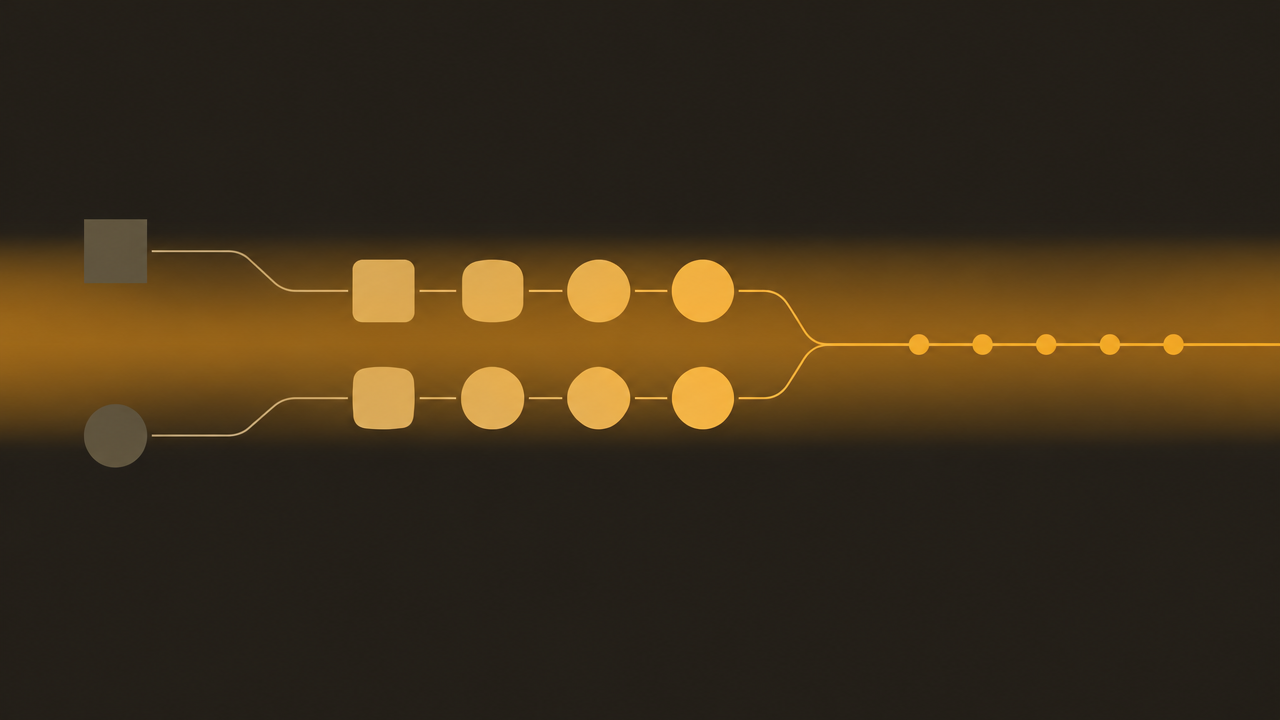
When serving consumers or creator tools, the real product form of image-to-video is the "template": the user uploads an image or selects a preset, clicks once, and gets a publishable short video.
Encapsulation Approach
- Converge inputs: let users provide only the first-frame image; the last frame, prompt, duration, and resolution are all preset by the template, so users do not need to understand the model.
- Fixed prompt templates: each template type corresponds to a validated set of motion descriptions, preventing excessive variance in output quality caused by free-form user input.
- Instant feedback: video tasks are asynchronous, so the product side must design queuing, progress, and completion notifications; users must not be left staring at a blank page.
Cost Control
Usage of templated products is unpredictable, and billing by output seconds means the per-call cost is linearly related to the duration the user selects. A common approach is to limit selectable durations by template tier, treating longer durations as a higher-threshold capability; at the same time, perform pre-validation on generation requests (image size, format, content compliance) to avoid invalid tasks consuming quota.
Quality Fallback
The quality of user-uploaded images is uncontrollable, so it is recommended to perform basic checks before generation and provide a retry entry on the results page. Treating "regenerate once" as a product capability rather than exception handling can significantly reduce customer complaints.
Scenario 5: Visual Demonstration for Architecture, Exhibition, and Product Concepts
Architectural renderings, exhibition schemes, and industrial product appearance renders are usually produced as static renders. During proposal and review communication, clients want to see "what it feels like to walk inside" and "what this looks like when it rotates," while the cost and cycle of redoing an animated demo far exceed those of static images.
Usage
Use a static rendering as the first frame to generate a short clip with a slow camera push-in, orbit, or ambient light changes, for proposal presentations, looping exhibition playback, and concept demos on crowdfunding pages. Such scenarios require less accuracy for specific details in the frame than e-commerce, but demand high "atmospheric credibility."
Design Essentials
- Motion should match physical intuition: in architectural demos, the scale of camera translation and viewpoint height should remain consistent; describing camera behavior in the prompt is more effective than describing scene content.
- Generate multiple renderings in batches: generate one clip per angle and then connect them in editing; this is more controllable than having the model complete multiple angles in one go.
- Clearly label the concept nature: generated clips are concept demos and should be distinguished in delivery documents from construction drawings and mass-production images to avoid being understood as the final form.
When Not to Use
Formal review materials that require precise dimensions and verifiable material parameters should still rely on professional rendering and modeling; generated video is suitable for carrying the communication and imagination parts.
Engineering Integration Essentials: Asynchronous Tasks, Retries, and Result Management
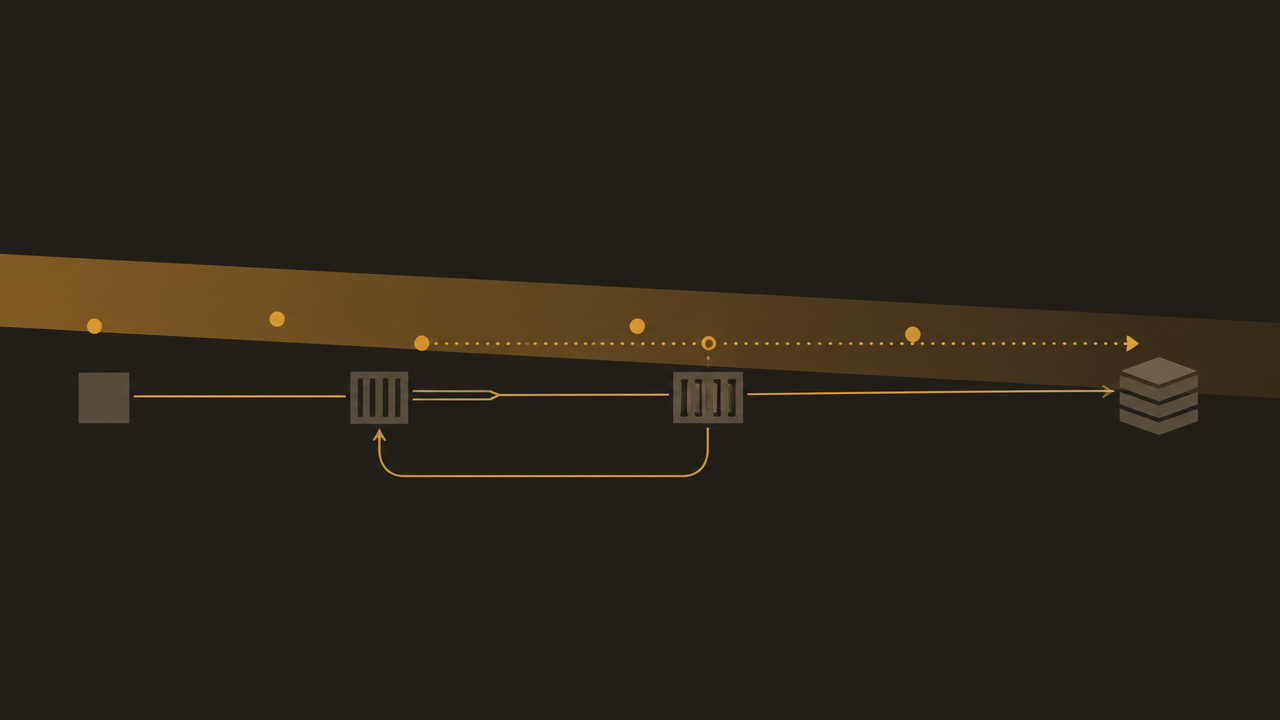
Video generation is not a synchronous request. Regardless of scenario type, the engineering side must design around asynchronous tasks.
Task Lifecycle
After submitting a task, obtain a task identifier, retrieve status via polling or callbacks, and download the output from the returned address once complete. Split these three steps into an independent state machine rather than hardcoding wait logic into a single request.
Timeouts and Retries
- Distinguish failure types: parameter errors and non-compliant input images are non-retryable; temporary server errors and queue timeouts are retryable.
- Retries must be idempotent: each task uses its own request identifier associated with a business-side ID; retries must avoid duplicate billing and duplicate database writes.
- Set a task-level timeout ceiling: tasks that still have no result beyond the expected duration should be marked as failed and sent to manual inspection rather than polled indefinitely.
Result Storage
Generated result addresses are usually temporary; be sure to transfer results to your own object storage as soon as the task completes, and record the task ID, input image, prompt, duration parameters, and final file path in the database. This record is both a basis for reproduction and the foundation for subsequent cost attribution.
Concurrency and Quotas
Batch scenarios (such as e-commerce multi-SKU) should use queues to smooth peaks and allocate concurrency by business priority; set independent quota ceilings for different business lines to prevent one batch task from crowding out online requests. Also explicitly record generation duration and resolution as task parameters to facilitate later analysis of cost structure.
Cost Model and Pre-Launch Acceptance Checklist
Cost Estimation Method
flux-3-max/keyframes-to-video is billed by output seconds. To estimate the cost of a single video, use "output seconds × per-second unit price"; for batch scenarios, multiply by the number of items. There are three variables to note:
- Duration: the most direct cost switch; in most scenarios, first confirm the shortest usable duration, then consider lengthening it.
- Retries and discarded clips: actual cost = cost of valid final clips + retry cost. Including failure rate and retry rate in the estimate is closer to real spending than calculating unit price alone.
- Resolution and aspect ratio strategy: determine aspect ratio and clarity according to the target placement, avoiding uniform generation at the highest specification followed by compression.
For real-time pricing, refer to the pricing panel on the HiAPI.ai site; this article does not list information beyond specific figures.
Pre-Launch Acceptance Checklist
- Keyframe quality: whether the first frame is cropped to the target aspect ratio, whether subject edges are clean, and whether any text needs to be resolved at the static stage.
- Motion controllability: whether the variance of results from multiple generations with the same input is within an acceptable range, and whether failed samples have clear attribution.
- Duration and aspect ratio: whether generation specifications are minimized according to the placement.
- Asynchronous pipeline: whether polling/callbacks, timeouts, idempotent retries, and result transfer are complete.
- Cost dashboard: whether call counts, output seconds, and failure rates can be counted by business line.
- Boundary documentation: clarify which requirements do not go into the video model (precise text layout, strict physical consistency, formal construction materials, etc.).
Treating keyframes as controllable inputs and duration as the cost knob, validating with small batches before scaling up, is the most reliable path for landing this type of capability. To view model capabilities and integration methods, start from the flux-3-max/keyframes-to-video model page on HiAPI.ai.
Related articles
View all articles →-

Tutorial
How to Call hailuo-2.3-fast/image-to-video via the HiAPI API: curl and Python
A first working request for the fast, low-cost image-to-video tier — from model ID to downloaded MP4
9 min read -

Tutorial
How to Use hailuo-2.3/text-to-video via the HiAPI API: curl, Python, and a Working Request
11 min read -

Tutorial
Kandinsky 6.0 Pro Text-to-Video on HiAPI: curl and Python Tutorial
A request-first walkthrough: build the prompt-to-clip call, submit it, poll for completion, and download the result
11 min read