
Guide
gpt-image-2-image-to-image for E-commerce Product Images: A Developer Workflow Guide
Why edit product images instead of regenerating them
Product photography is expensive to reshoot and risky to fake. When you already have a clean source photo of the actual SKU, an image-to-image edit is almost always the safer path: the model starts from real geometry, real color, and real material detail, then changes only what you ask it to change.
Full generation is the better fit when no usable photo exists (concept mockups, pre-production packaging, placeholder art) or when you need an entirely new composition that no source can anchor. But for catalog work, the failure mode of generation is subtle: the model invents a plausible-looking variant of your product. A slightly wrong zipper pull, a different label kerning, an off-brand shade of blue. Those defects are hard to catch at scale and expensive to fix after publishing.
Editing keeps a fidelity anchor. In practice, the split looks like this:
- Edit when you need a new background, a lifestyle context, a seasonal scene, or a corrected crop — and the product itself must remain byte-for-byte believable.
- Generate when you need composition freedom and no authoritative source exists.
- Hybrid when you generate a scene first and then composite the real product into it with an edit pass, using the generated scene as a reference.
The rest of this guide assumes the edit path, because that is where most e-commerce volume lives: a stable SKU catalog that needs many visual variants per product without touching the product itself.
Calling gpt-image-2-image-to-image through HiAPI
All calls go through the HiAPI unified API surface, so you authenticate once and keep the same request shape across models. The image-to-image model takes your source image plus a text instruction and returns an edited image you persist yourself.
Request shape
A minimal flow has three parts: authenticate, send the source image with a prompt, and handle the response.
curl -X POST https://api.hiapi.ai/v1/images/edits \
  -H "Authorization: Bearer $HIAPI_API_KEY" \
  -F "model=gpt-image-2-image-to-image" \
  -F "image=@./sku-1042-front.jpg" \
  -F "prompt=Replace the background with a soft neutral studio gradient, keep the product unchanged" \
  -F "size=1024x1024"
The response contains the edited image, either inline or as a URL depending on the response format you request. Store the bytes in your own object storage immediately — treat the API as transient and your bucket as the record of truth. Persist the prompt, the source image hash, and the model identifier alongside the output so any asset can be reproduced later.
Practical integration notes
- Send the highest-quality source you have. Downscaled thumbnails lose the texture detail that makes edits convincing.
- Keep prompts declarative. Describe the target state, not a sequence of Photoshop operations.
- Pin the model name in config, not in scattered call sites, so you can swap variants without a code hunt.
- Log request IDs. When an output looks wrong, the request ID is what lets you compare against a re-run.
- Time out generously but bound it. Image edits are slower than chat completions; set client timeouts above your p95 and fail fast beyond that.
A simple sequence: your service reads the source asset, calls HiAPI with image plus prompt, receives the edited image, writes it to storage, and enqueues it for validation. Keep validation asynchronous so a slow reviewer never blocks a batch job.
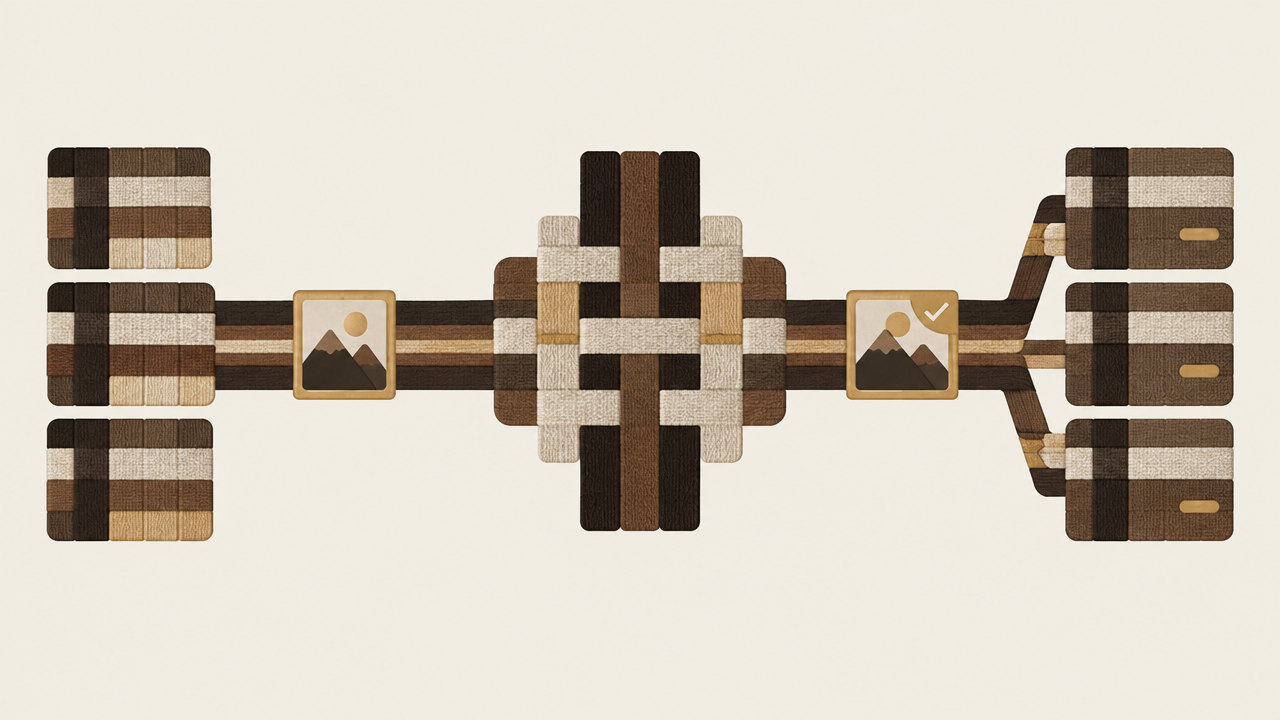
Background swaps that keep the product intact
The most common edit is also the most failure-prone: replacing a background while the model decides to "improve" the product too. The fix is prompt discipline plus explicit invariants.
Prompt structure that works
Write in three clauses: what changes, what must not change, and how it should look.
Replace the background with [target scene].
Keep the product's shape, color, texture, logos, and label text exactly as in the source.
Lighting: soft diffused key from the upper left, gentle contact shadow beneath the product.
The second clause matters most. Naming the specific attributes you want preserved — silhouette, material finish, printed text — measurably reduces drift on packaging and apparel.
Parameter strategy
- Match the source aspect ratio unless the storefront template demands otherwise; rescaling inside the model wastes fidelity.
- If the API exposes a strength or similarity control, keep edits conservative for hero images and looser for secondary thumbnails where fine detail reads less.
- Request one change per call. Background swap and color correction in the same prompt usually produces both done halfway.
Scenes that suit hard-edged products
Transparent glass, matte black plastics, and metallic finishes pick up reflections from whatever you put behind them. Prompt for controlled environments — seamless studio gradients, solid crushed-paper surfaces — before attempting complex interiors. For bottles and jars, explicitly ask for a contact shadow; floating products are the single most common giveaway in AI-edited catalog shots.
A quick sanity rule
If you cannot describe the ideal output in three sentences, the prompt is not ready. Iterate on wording first, spend calls second.
Generating lifestyle scenes with reference images
Lifestyle imagery sells context: the product on a kitchen counter, in a gym bag, on a desk. Here the product must stay recognizable while the world around it is invented, which is a harder ask than a background swap.
Two-input pattern
The reliable pattern uses two images: the product source (authoritative geometry) and a scene reference (composition, palette, light direction). Your prompt then describes how the product sits inside that scene.
- Use the product image as the subject anchor.
- Use the scene reference for mood and framing, not for objects it contains — otherwise the model may import props that clash with your brand.
- State the physical relationship explicitly: "on the counter, slightly right of center, seen at eye level."
Prompt skeleton
Place the product from image 1 into the scene from image 2.
Preserve the product's proportions, label, and color exactly.
Match the scene's lighting direction and color temperature.
Add a natural contact shadow where the product meets the surface.
What to watch for
Scale and perspective are the two failure points. A coffee mug that reads as waist-high on the counter, or a phone shot from a contradictory angle, breaks the illusion instantly. Specify camera height and a relative size cue ("about the height of the nearby mug") when the scene has known objects.
Also decide early whether reflections are acceptable. On polished surfaces the model may mirror label text, and mirrored text reads as broken branding to any attentive customer. If reflections are risky, prompt for matte or fabric surfaces instead.
Run two or three candidates per product and route them to review — lifestyle outputs vary more than studio swaps, and a human eye catches scale errors faster than any automated check you will write this quarter.
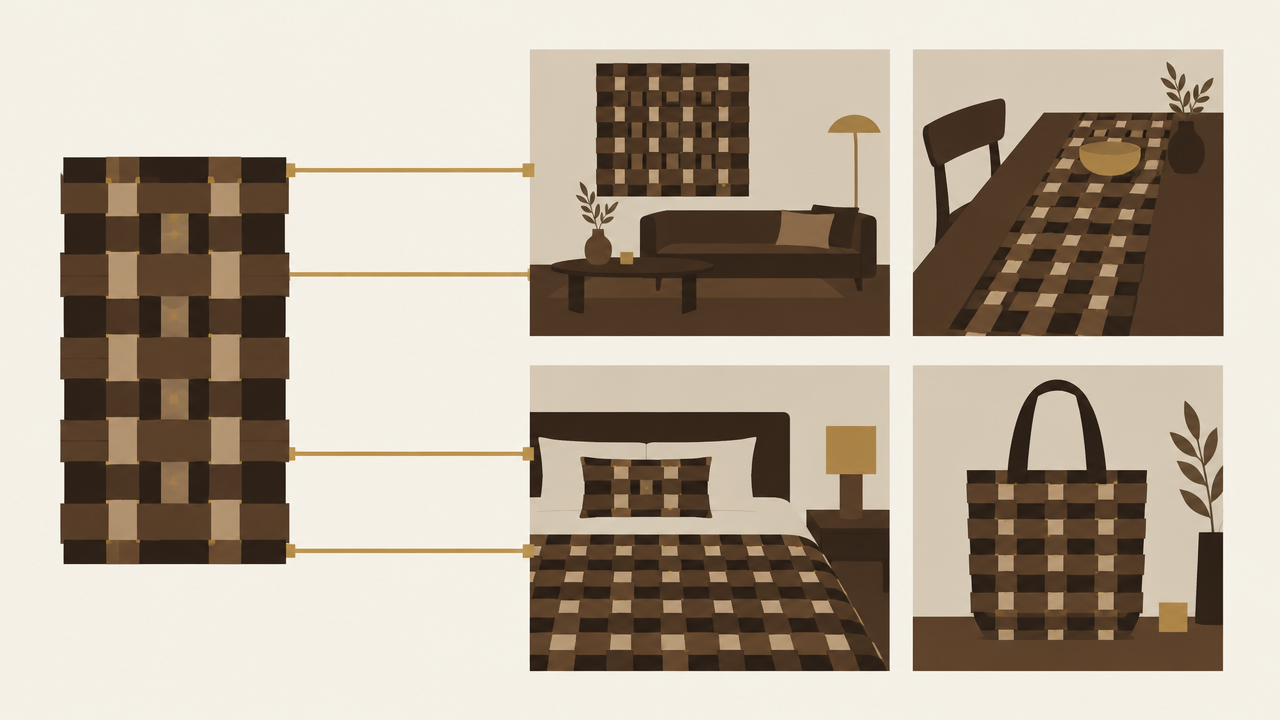
Multi-reference consistency across a catalog
A product line should look like one photographer shot it. Consistency is not a model feature; it is an asset-management discipline you build around the model.
Build a reference kit per collection
For each collection, freeze a small set of inputs:
- A product source per SKU, shot to the same spec (same angle, same crop ratio, same lighting).
- One or two scene references shared across the whole collection — the same kitchen, the same studio corner.
- A prompt template with slots for product name and placement, so wording does not drift between SKUs.
Store this kit in version control next to your generation config. When a campaign ends, bump the kit version rather than editing prompts in place, so last season's assets stay reproducible.
Template with slots
Background: {SCENE_REF}.
Subject: product from {PRODUCT_IMAGE}, unchanged in shape, color, and label.
Framing: product occupies {FILL}% of frame width, centered horizontally.
Lighting: match {SCENE_REF} direction and temperature.
Filling {FILL} identically across a collection does more for visual coherence than any prompt adjective. Catalog grids look unified when subject scale is unified.
Reference hygiene
- Keep references at a consistent resolution; mixing sources changes the model's apparent framing.
- Never reuse a reference that contains a competitor's product, even blurred.
- Refresh scene references seasonally, but as a batch — half a catalog on the new set looks worse than a full catalog on the old one.
Order of operations
Generate one hero SKU, review it against the reference kit, then batch the rest. If the hero drifts, the template is wrong, and batching first multiplies the defect across the catalog.
Validating outputs before they reach the storefront
Automated validation catches the boring failures cheaply; human review catches the embarrassing ones. Build both, in that order.
Automated gates
- Dimensions and aspect ratio must match the storefront template. Reject silently wrong crops at ingestion.
- Format and color profile should be normalized on write, so downstream CDNs never see a surprise.
- Source-to-output diff heuristics. For background-swap jobs, compare the product region between source and output (perceptual hash or SSIM on a masked crop). A large delta means the model altered the product — flag it.
- Text-region check. If your product carries printed labels, crop the label area and run OCR against the expected string. This catches the classic failure of plausible-but-wrong lettering.
- Blank and near-blank detection, plus a file-size floor, to catch empty responses from transient errors.
Human review routing
Route by risk, not uniformly. New SKUs, lifestyle scenes, and any asset whose automated diff crossed threshold go to a reviewer queue; repeat runs of an established template on a familiar product can auto-approve. Keep the review surface simple: source image, output image, prompt, and the failing check, side by side.
Store the decision
Record approval state and reviewer notes with each asset. When a customer complaint or a brand audit arrives, you need to answer "who approved this and against which prompt" without archaeology.
asset_id, sku, model, prompt_hash, source_hash,
checks_passed, checks_failed, review_status, reviewer
That row is worth more than any individual image. It is what makes the pipeline auditable when volume scales.
Cost, latency, and retry strategy
Image editing is priced per generated image, so every wasted call is a real cost. The discipline is straightforward: reduce call volume, bound retries, and never pay twice for the same mistake.
Batch thoughtfully
- Process a collection in one job with a shared prompt template, not as ad-hoc single calls from a UI.
- Concurrency is your lever for latency; keep it below the rate limit so you get throughput without throttling errors, which are the most expensive kind of retry.
- Generate to a staging bucket. Nothing reaches the storefront without passing validation, so a bad batch never touches live pages.
Retry rules
- Retry only transient failures: network errors, timeouts, rate limits.
- Cap retries at a small fixed number per item, with exponential backoff and jitter.
- Never retry a validation failure automatically. A wrong label is not going to fix itself on attempt three; it needs a prompt change and a human decision.
- Treat repeated identical failures across a batch as a template bug — stop the job, do not grind through every SKU.
Iterate on prompts cheaply
Prompt tuning is where budgets quietly leak. Keep one representative SKU as a canary: adjust the template, run the canary, inspect, then release the template to the full batch. Ten canary calls beat three hundred speculative ones.
Measure what you spend
Log per-asset call counts and outcomes, then watch the ratio of accepted assets to calls. A rising ratio means template drift; a falling one means a model or prompt regression. Either way, the dashboard tells you before the invoice does.
Latency expectations
Plan the pipeline around asynchronous jobs. A queue plus worker pool keeps request timeouts short and user-facing response times unaffected, and it lets you rerun failed subsets without reprocessing the whole collection.
Start with a single SKU, a fixed template, and the automated checks in place — then scale the batch once the acceptance ratio is stable.
Related articles
View all articles →-

Guide
Getting Started with seedream-5.0-pro/image-to-image: Capabilities, Pricing, and Integration Essentials
Capability boundaries, billing model, and engineering integration practices for ByteDance's image editing model
-

Guide
seedream-5.0-pro Text-to-Image Getting Started Guide: Capability Boundaries, API Integration, and Cost Control
A hands-on developer perspective: from key parameters to a cost estimate of $0.05 per image
-

Guide
Hailuo 2.3 Fast Image-to-Video Getting Started Guide: Capability Boundaries, Pricing, and Integration Practices
MiniMax image-to-video model selection and integration key points for developers