
Guide
wan3.0-video-prime Getting Started Guide: Capability Boundaries of Reference Video Generation, Pricing, and Integration Practices
A Developer Decision Checklist for Integrating Alibaba's Video Model
Why Pay Attention to wan3.0-video-prime
wan3.0-video-prime is released by Alibaba, its output type is video, and its core capability is reference-to-video. The reason to put it on the candidate list is straightforward: it targets needs like "give a piece of reference material, then generate a video," rather than generating video from scratch based only on a text prompt.
For developers, a model's value depends on whether it matches your business form. If your product already has stable visual assets—brand image, character settings, existing product images or sample clips—and you want the generated results to maintain recognizable consistency in these dimensions, then reference-driven video generation is a branch worth evaluating separately. Conversely, if the need is open-ended creation from pure text to video, this model's capability positioning is not the strongest match.
First remember two hard facts: the output is video, and billing is based on output seconds. These two points will run through all subsequent integration and budget discussions.
The First Question When Choosing
Before diving into parameters, ask yourself one question: does my business naturally come with a "reference object"? If the answer is no, the benefit of reading further is limited; if the answer is yes, then what you need to figure out next is how much this reference object can constrain, and how much duration cost you need to pay.
What reference-to-video Can and Cannot Do
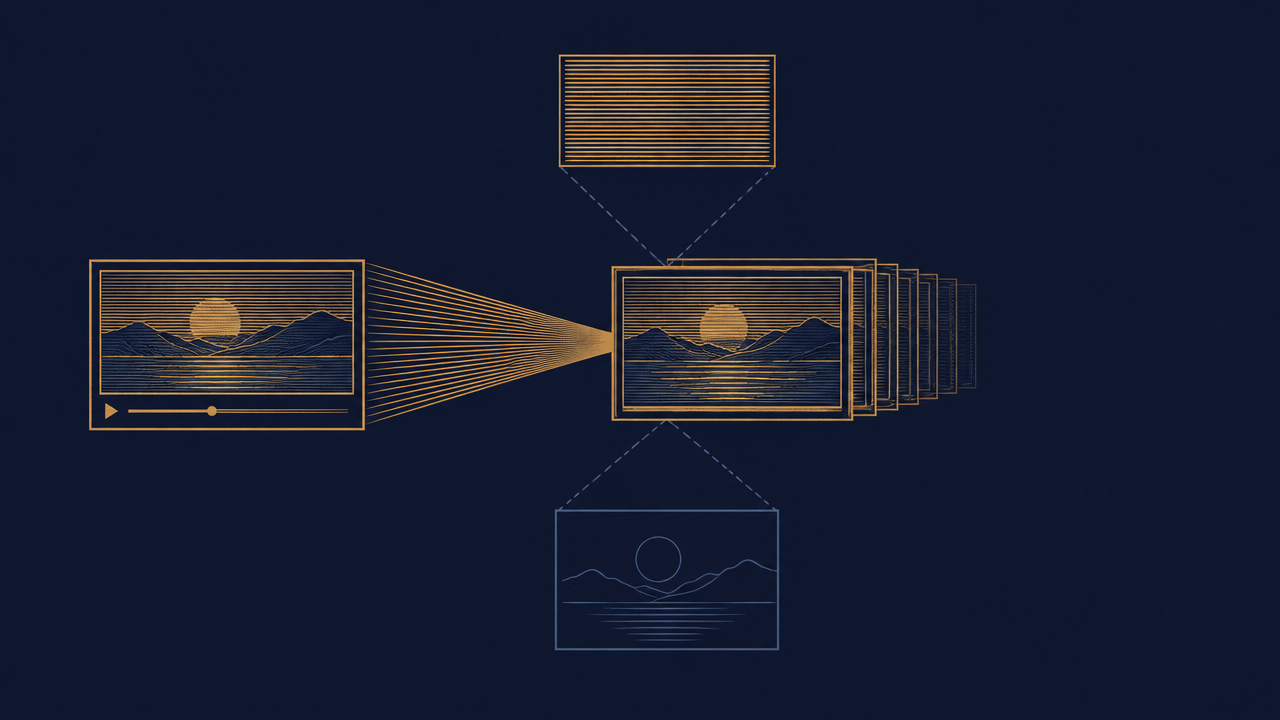
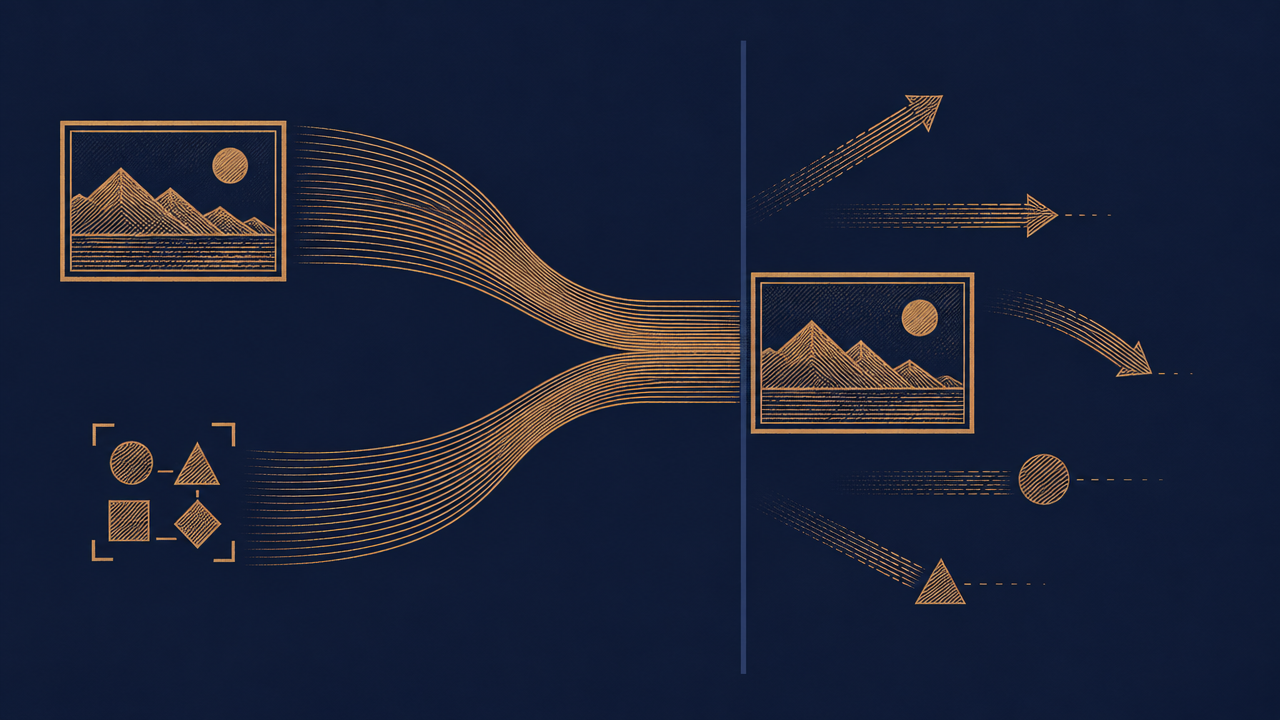
The basic form of reference-to-video is: a piece of reference material plus a text prompt together determine the direction of the generated video. The reference material carries the "what it looks like" part, and the text prompt carries the "how it moves and changes" part.
What It Can Do
- Short video generation with high reference consistency requirements: when you want the output to continue the visual characteristics of the reference material, this is the model's home turf.
- Iterative creation starting from existing material: you don't have to describe the entire scene from scratch every time; put stable information in the reference and variable information in the prompt.
- Single-video output with controllable duration: suitable for scenarios where attention is on result quality rather than quantity.
What It Cannot Do or Should Not Be Expected to Do
- Treating long-duration batch generation as a cheap solution. Billing by output seconds means cost grows linearly with duration, and the combination of long duration and large batches will quickly make budgets spiral out of control.
- Treating reference material as an all-purpose constraint. References provide guidance, not a pixel-by-pixel copy guarantee; requirements that expect "exactly identical" should be filtered out early in evaluation.
- Using it to replace open-ended text-to-video creation workflows. The capability positioning is different; forcing it will only yield half the result with twice the effort.
The way to judge is to draw a line: on one side is "has reference, needs consistency, short duration"; on the other side is "no reference, needs freedom, long duration." The former goes in; the latter goes around.
Parameters and Process Points to Confirm Before Integration
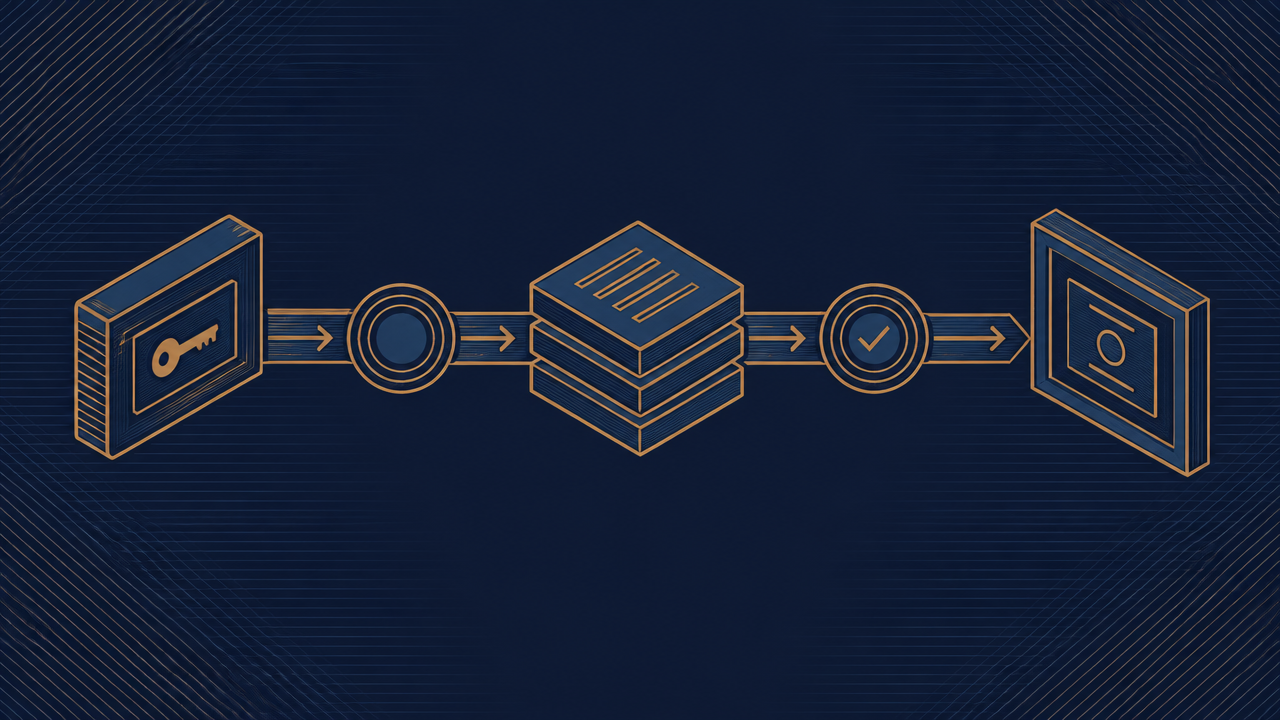
When integrating within the unified interface context of HiAPI.ai, the process itself is convergent; what is truly prone to problems is preparation work. It is recommended to proceed in the following order.
Preparation Checklist
- Credentials and permissions: First confirm that calling credentials are ready, and clarify the corresponding quota and permission scope, so as to avoid wasting time on authentication during the integration testing phase.
- Model identifier: Use the exact model name wan3.0-video-prime in requests; do not guess or copy from old examples.
- Input material specifications: Determine in advance the format, size, and content boundaries of reference material; material quality is the upper limit of result quality.
- Prompt structure: First write a structured prompt rather than a one-sentence draft; see below for how to organize it.
- Output handling method: Clarify how to store video results after receiving them, how to return them to the frontend, and how to handle timeouts.
Calling Order
First get the pipeline working with the minimal usable request—one piece of reference material, a short prompt, and the shortest possible output duration—confirm that video results can be obtained normally, then gradually lengthen duration and increase prompt complexity. Change only one variable at each step, so that when problems arise you can locate whether it is the material, the prompt, or the duration.
Points to Note
Public materials only cover model positioning, output type, and billing basis; specific parameter details should be based on the actual interface documentation. Do not fill in unconfirmed fields based on experience; for parameters not covered by the documentation, first verify their behavior with a minimal request, then write them into production code.
Billing by Second: How to Estimate and Control Costs
This model is billed by output seconds. This basis determines the basic formula for cost estimation:
Single-item cost ≈ output seconds × price per second
Total cost ≈ average seconds per item × number of items × price per second
For real-time pricing, please refer to the site's price panel; this article does not expand on specific numbers. What matters is understanding the structure: cost is linearly tied to duration, unrelated to how many times you call, and related only to how many seconds of video you produce.
Two Things Easily Overlooked in Estimation
- Retries also count: Every call that successfully produces video counts toward duration; the experimental cost of repeatedly tuning parameters is a real cost.
- Batch size amplifies duration: The number of items and the duration per item are multiplied; if either side doubles, the budget doubles.
Control Strategies
- Start with short duration: First use a very short single-item duration to verify whether the prompt and material are effective; once the direction is confirmed, then lengthen it.
- Treat duration as a product parameter: Clearly define "the maximum number of seconds" on the business side, rather than letting users freely max out duration.
- Set budget gates: Work backward from "how many seconds are planned for production this month" to the acceptable call scale, rather than planning by "how many calls can be made."
- Keep comparative tests small-sample: During parameter tuning, use the minimum sample size to reach directional conclusions, then scale up.
Converting cost into seconds rather than times is the most important mindset shift when using this model.
Typical Usage and Prompt Structure Recommendations
Scenarios suitable for this model share a common feature: the reference material itself is a business asset. Examples include short films centered on brand image, content with fixed characters as the subject, and showcase videos based on existing product material. In these scenarios, consistency is a hard requirement and duration is controllable.
Layered Organization of Prompts
Write prompts in three layers, not as a single paragraph:
- Reference layer: State what must be preserved in the reference material—subject, color scheme, stylistic tone.
- Motion layer: Describe how the image changes—how the camera moves, how the subject moves, and the pace.
- Constraint layer: Clearly state what should not appear, as well as duration and aspect ratio requirements.
The point of layering is debuggability. When the result is wrong, you can determine whether the reference description was unclear, the motion description conflicted, or constraints were missing, without having to rewrite the whole thing.
How to Write the First Version of the Request
First confirm the subject in one sentence, then add motion and constraints, and compress the single-item duration to the shortest. After it works, add details layer by layer, adding only one layer at a time. This way, even if the result is not ideal, you know which layer caused the deviation.
When comparing multiple models, keep the prompt structure unchanged and only switch the model identifier, so as to obtain comparable conclusions.
Horizontal Comparison Criteria with Other Video Models
The most common mistake in multi-model comparison is looking only at unit price. Unit price is meaningful only when all other dimensions are aligned. It is recommended to evaluate uniformly using the following dimensions:
- Billing basis: By second, by call, or by token. With different bases, unit price numbers are not directly comparable; they must first be converted to the same basis before comparison.
- Reference capability: Whether reference-driven generation is supported, and to what extent references can constrain. This directly determines whether it can enter your candidate set.
- Output duration range: How long a single item can produce, and whether there is a practical length limit.
- Output type and form: Whether basic attributes such as video resolution and aspect ratio meet business requirements.
- Debugging cost: How many rounds of calls are needed from one experiment to a usable conclusion—this is especially important when using models billed by second.
How to Use This Set of Criteria
First perform a hard filter based on "reference capability," directly excluding those that do not meet it; then sort the remaining candidates by converted cost per second; finally adjust using debugging cost—a model with a slightly lower unit price but requiring more rounds of experimentation may have a higher real cost.
The conclusion of comparison should not be "which is cheaper," but "among the models that meet my reference consistency requirements, which has the lowest total cost at an acceptable duration."
Common Questions and Pre-Launch Checklist
Common Questions
- The result does not look like the reference material: Most likely the reference layer description is too general, or the reference material itself lacks distinctive features. First make "what must be preserved" specific.
- Image motion does not match expectations: The motion layer description conflicts with the reference layer, for example requiring both maintaining a static composition and large camera movement.
- Cost exceeds expectations: This is almost always caused by duration and batch size increasing at the same time. Go back to the per-second estimation formula and recheck.
- Wanting more seconds and lengthening a single item: This is the most expensive optimization method; prioritize splitting into multiple short videos rather than lengthening a single item.
Pre-Launch Checklist
- Cost: Budget estimation has been completed based on output seconds, and duration caps and batch gates have been set.
- Quality: Comparative testing has been completed with a minimal sample, and the prompt structure of the reference layer, motion layer, and constraint layer is stable and reusable.
- Reliability: Credentials, model identifier, timeout and retry strategies have been confirmed, and failure paths have clear handling methods; the storage and return pipeline for output results has been tested end to end.
Scaling up after checking all three columns is the safest way to use wan3.0-video-prime. If your scenario has already been confirmed to be reference-driven short video generation, verifying with a request at the shortest duration will give you an answer faster than any paper evaluation.
Related articles
View all articles →-

Guide
Getting Started with seedream-5.0-pro/image-to-image: Capabilities, Pricing, and Integration Essentials
Capability boundaries, billing model, and engineering integration practices for ByteDance's image editing model
-

Guide
seedream-5.0-pro Text-to-Image Getting Started Guide: Capability Boundaries, API Integration, and Cost Control
A hands-on developer perspective: from key parameters to a cost estimate of $0.05 per image
-

Guide
Hailuo 2.3 Fast Image-to-Video Getting Started Guide: Capability Boundaries, Pricing, and Integration Practices
MiniMax image-to-video model selection and integration key points for developers