
Guide
Using gpt-6.1-terra for E-commerce Product Images via the HiAPI API
Prompt templates and a working HiAPI request for scalable product-image generation
Why gpt-6.1-terra for Product Image Workflows
Product imagery is one of the last parts of an e-commerce pipeline that still depends on manual production. A developer integrating a listing system eventually hits the same wall: every SKU needs a hero shot, a clean packshot, and often a lifestyle variant, but each of those assets used to mean a photographer, a retoucher, and a scheduling loop. gpt-6.1-terra via HiAPI changes where that work sits in your architecture — instead of treating images as static files uploaded once, you can treat them as generated artifacts produced by the same service layer that already handles catalog data.
The practical shift is that image generation becomes a function in your code, not a calendar event. Your product record (title, attributes, color, material, use case) becomes the input; the model call becomes the transformation; the output lands in a review queue before publish. That reframing affects several decisions developers care about:
- Where generation runs. It can sit behind an internal endpoint, a queue worker, or a build step for new SKUs. Because HiAPI exposes one unified interface, the call shape does not change as you move it between environments.
- What stays deterministic. Prompt templates, slot validation, and output checks are your code. The model handles rendering; you own consistency.
- How catalogs scale. Adding a SKU no longer requires a shoot — it requires a valid prompt payload and a passing validation gate.
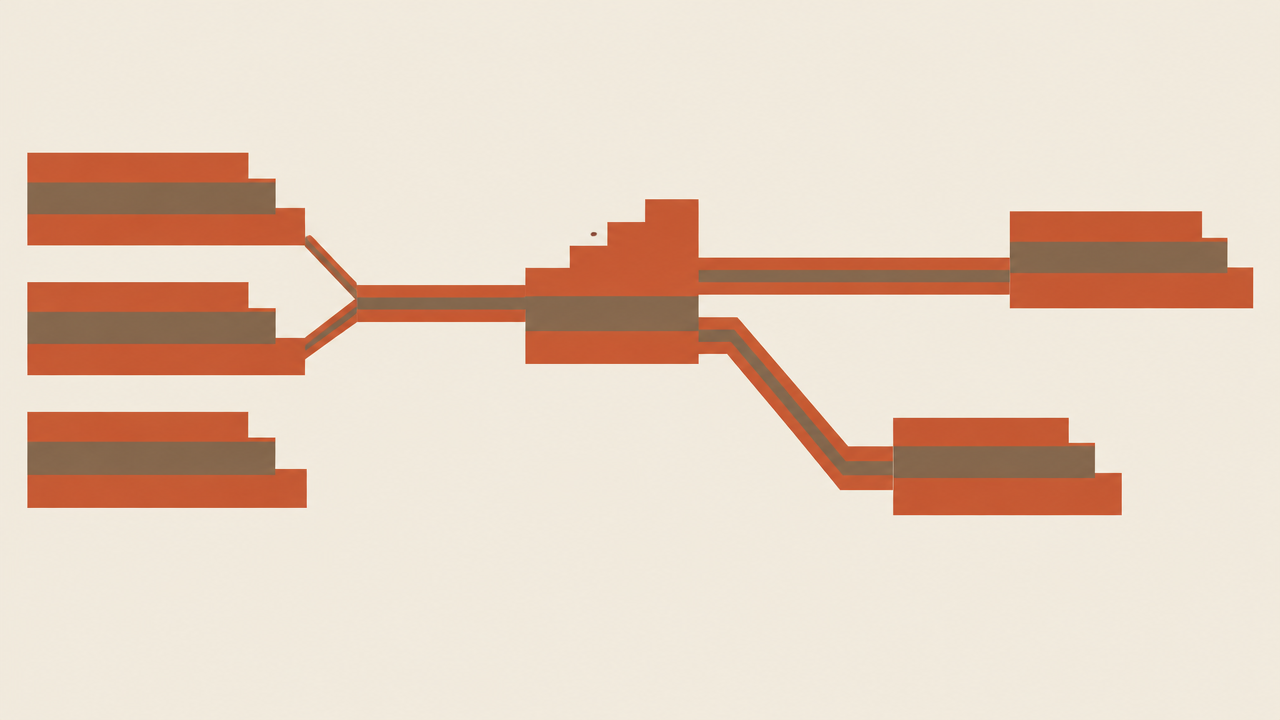
A useful mental model is a four-stage pipeline: structured product data flows into a model call through HiAPI, the result lands in a review queue, and approved assets are promoted to the storefront. Everything in this guide maps onto one of those four stages, and the sections that follow break down the prompt, the request, and the safeguards around it.
If you treat gpt-6.1-terra as a rendering dependency rather than a creative tool, the rest of the integration becomes ordinary engineering: schema validation, retries, batching, and review gates.
Anatomy of a Product-Image Prompt
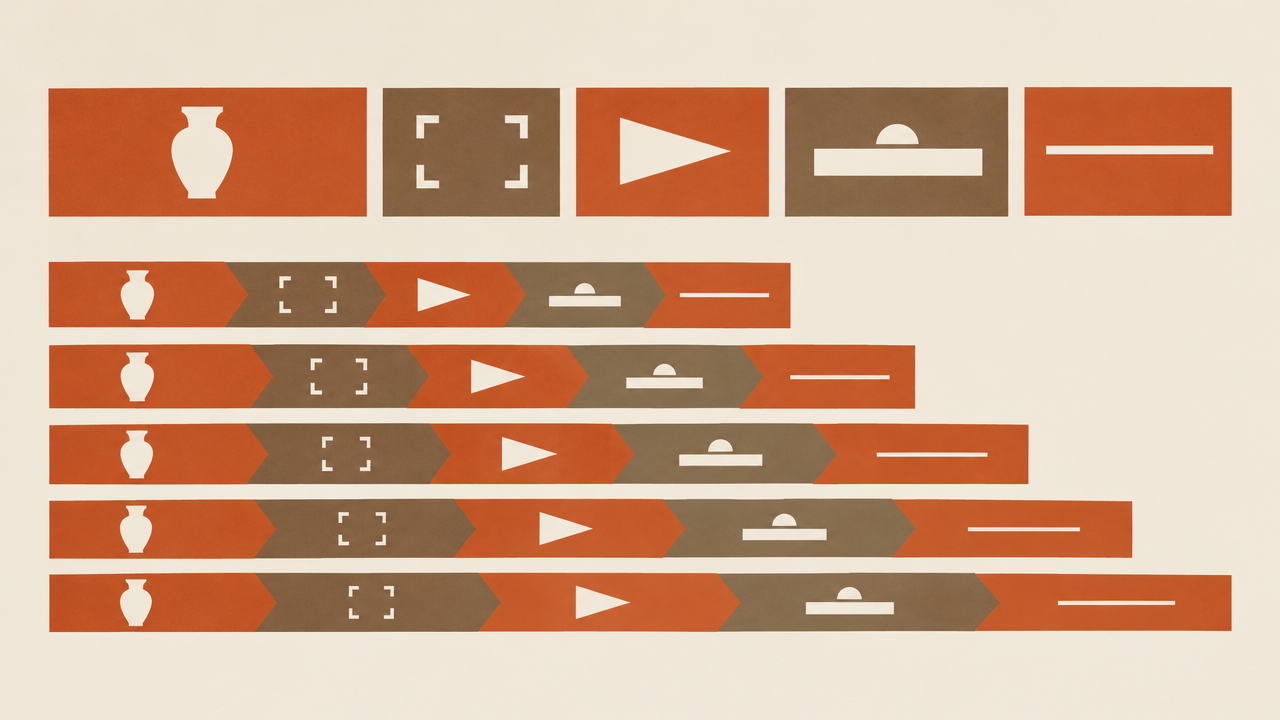
The difference between a prompt you can reuse across a thousand SKUs and one you can only run once is structure. A catalog-ready prompt is a set of named slots that your application fills from product data, not free-form prose typed by a human. Break it into five slots:
Subject
What the product is, described in plain, concrete nouns. Pull from catalog attributes: category, material, color, size, defining features. Keep it factual — the model renders what you describe, so omit anything not in the product record.
Composition
Where the product sits in frame and how much of the frame it occupies. Typical values: centered, top-down, three-quarter angle, full-bleed. This slot is where hero shots and packshots diverge.
Lighting
The lighting setup and mood. Soft studio lighting, hard directional light, daylight through a window. Lighting is the single highest-leverage slot for perceived quality, so define a small vocabulary and reuse it.
Background
What surrounds the product — seamless white, light gray gradient, a named scene context. For catalog work, keep backgrounds boringly consistent; save scene variety for lifestyle variants.
Constraints
The rules that keep output usable: no text overlays, no logos unless supplied, no extra props, product occupies the central frame, no reflections that hide the label. Constraints are what turn a nice image into a shippable asset.
Treat each slot as a typed field in your code. Subject and constraints come from the product record and a fixed policy; composition, lighting, and background come from a small enum keyed by image type. Compose them in a fixed order — subject, composition, lighting, background, constraints — so that diffs between two prompts reflect real changes rather than phrasing noise. When a prompt fails review, you can then adjust exactly one slot instead of rewriting everything.
Prompt Templates You Can Reuse
The templates below follow the five-slot anatomy. Each is a skeleton with {placeholders} your code fills from product data. Keep them in version control — a prompt template is a piece of production configuration, not a throwaway string.
Hero shot
Subject: {product_name}, {color}, {material}, {defining_feature}
Composition: centered, three-quarter angle, product occupies roughly 60% of frame
Lighting: soft studio lighting with a subtle key light from upper left
Background: light neutral gradient, no visible horizon
Constraints: no text, no logos, no extra props, label fully legible, no harsh shadows
Use for category landing pages and primary listing visuals. Consistency across SKUs matters more than novelty here.
Packshot
Subject: {product_name}, {color}, {material}
Composition: straight-on, product centered and fully visible, even margins on all sides
Lighting: flat even studio lighting, minimal shadow
Background: pure seamless white
Constraints: no text, no logos, no props, no reflection artifacts, product edges crisp against background
The packshot is your most constrained template. Resist adding atmosphere — marketplaces and comparison grids reward uniformity.
Lifestyle scene
Subject: {product_name}, {color}, {material}
Composition: {placement}, product in natural use context, shallow depth of field
Lighting: {lighting_mood}, consistent with {scene_time_of_day}
Background: {scene_description}, complementary tones to product color
Constraints: product remains the focal point, no readable text, no brand logos other than supplied, no people faces in sharp focus
Lifestyle templates vary most, so drive them from a small scene library rather than per-SKU prose. Reuse scenes across products in the same category to keep a coherent look.
In all three templates, the constraint block is non-negotiable. When you add a new template, copy the constraints verbatim and change only the slots above them.
A Working HiAPI Request for gpt-6.1-terra
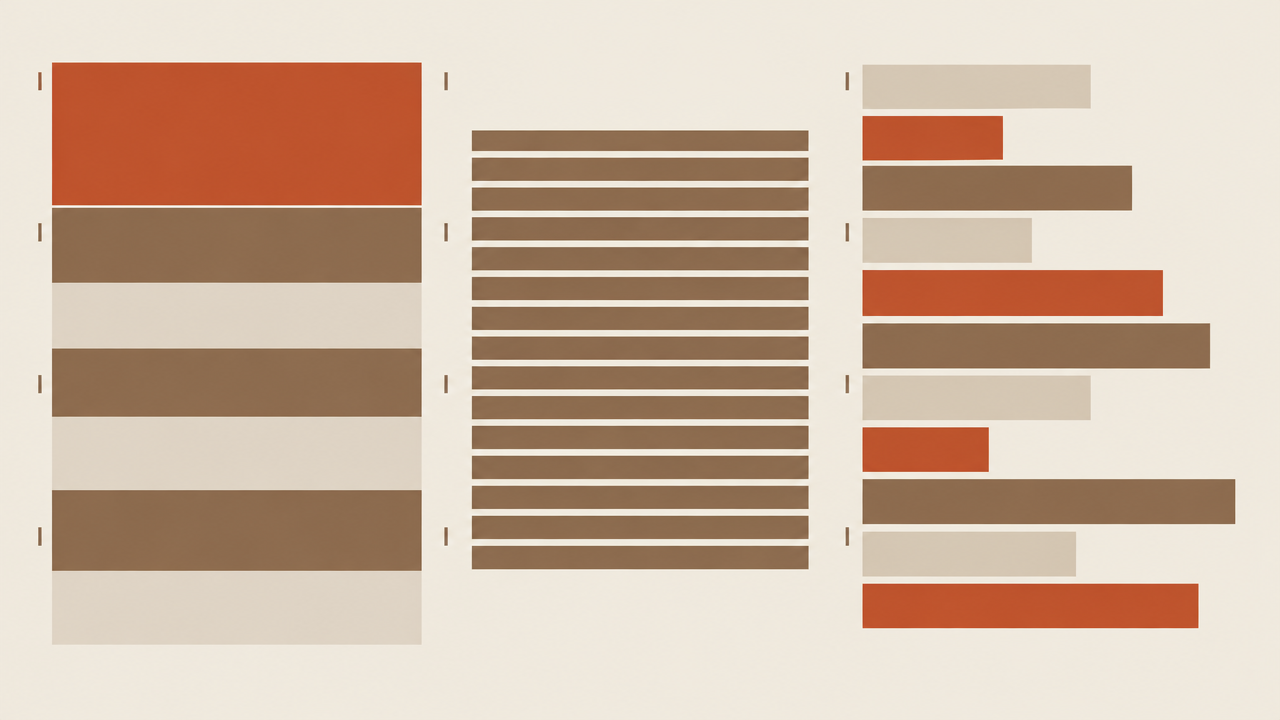
Calling gpt-6.1-terra through HiAPI follows the same pattern as any other model call on the platform: you send a request to a single endpoint, authenticate with your HiAPI key, and receive a normalized response. The sequence is client to HiAPI gateway to model, with the gateway handling routing and returning either a result or a structured error.
Configuration
Keep your key and base URL in environment variables, never in source:
export HIAPI_API_KEY="your-key-here"
export HIAPI_BASE_URL="https://api.hiapi.ai"
Request shape
The request carries the model identifier, the composed prompt from your template, and any generation parameters your image type needs. A minimal request in Node.js looks like this:
const res = await fetch(`${process.env.HIAPI_BASE_URL}/v1/generate`, {
  method: "POST",
  headers: {
    "Authorization": `Bearer ${process.env.HIAPI_API_KEY}`,
    "Content-Type": "application/json"
  },
  body: JSON.stringify({
    model: "gpt-6.1-terra",
    prompt: composedPrompt,
    params: { aspect_ratio: "1:1" },
    metadata: { sku: product.sku, template: "packshot-v3" }
  })
});

if (!res.ok) {
  const err = await res.json();
  throw new Error(`HiAPI ${res.status}: ${err.message}`);
}

const data = await res.json();
Integration notes
- Send metadata. Attaching the SKU and template version to each request makes downstream debugging and review far easier, and it lets you correlate outputs with catalog records.
- Validate before sending. Reject requests where any template slot is empty or where the constraint block is missing. This catches most bad generations before they cost you anything.
- Handle errors explicitly. Distinguish validation errors (your payload is wrong) from transient failures (retry makes sense). The next sections cover retry policy.
- Store the response, not just the asset. Persist the request payload alongside the generated image so a review decision can be traced back to exactly what was asked for.
The exact parameter names your templates need depend on your image type — pin them per template version so a template change is reproducible.
Batching, Validation, and Human Review
Generating one image is a demo; generating a catalog is an operations problem. The flow that works is a batch generator feeding automated validation, and a human review gate before anything reaches the storefront.
Batching
Drive batches from a queue keyed by SKU. For each SKU, render the prompt from the right template, submit the request to HiAPI, and write the result to a staging store with status pending_review. Concurrency should be bounded — a fixed worker pool with backoff is easier to reason about than unbounded parallelism, and it keeps failure blast radius small.
Automated validation
Run cheap checks before a human ever looks at the output:
- Request completeness. Every slot filled, constraints present, template version recorded.
- Asset sanity. Image decodes, dimensions match the target slot, aspect ratio is correct.
- Duplicate detection. Hash outputs so identical images across SKUs surface immediately — usually a sign of a broken template.
- Policy checks. Flag outputs that appear to violate your constraint block, such as unexpected text or props, for priority review.
Anything that fails validation goes to a failed_validation bucket with the reason attached. Do not auto-retry validation failures — they indicate a template or data problem, not a transient one.
Human review gate
A reviewer sees the generated image, the source product record, the rendered prompt, and the template version, and approves or rejects. Approvals promote the asset to the storefront; rejections capture a short reason. Those reasons are your feedback loop: a cluster of rejections against one template version is a signal to revise that template, not to retry more aggressively.
Start with a small sample of SKUs, review every output, and widen the sample only as rejection rates stabilize. The gate is what lets you scale without publishing mistakes.
Cost, Latency, and Failure Handling
Generation costs money and time, so the production system needs an explicit policy for both. Since pricing is metered per request and by generation parameters, treat cost as a budget you allocate per SKU rather than a number to compute by hand — check the price panel in your HiAPI account for current rates, and enforce limits in code.
Cost controls
- Budget per batch. Assign a maximum number of generations per batch run and stop when it is reached.
- One attempt per template version. A failed validation should not trigger a retry with the same prompt; it should return to the template owner.
- Cache aggressively. If a SKU's prompt slots and template version have not changed, reuse the approved asset instead of regenerating.
- Tier your templates. Use the cheapest sufficient configuration for packshots and reserve heavier settings for hero or lifestyle variants where quality matters most.
Latency
Generation is not instantaneous, so design for asynchronous results. Queue the request, return a job identifier to the caller, and let the worker write the result when it lands. Timeouts should be tied to your queue's lease, not to a user-facing HTTP request.
Failure handling decision tree
When a request fails, classify before acting:
- Validation error (4xx). Fix the payload. Do not retry.
- Rate limit or transient server error (429/5xx). Retry with exponential backoff and jitter, capped at a small number of attempts. If attempts exhaust, mark the SKU
deferredand move on. - Repeated failure for the same SKU. Fall back to the last approved asset if one exists; otherwise route to manual review with the error attached.
- Systemic failure across a batch. Stop the batch, surface the error, and do not drain the queue — continuing will only multiply the failure.
The pattern is the same as any external dependency: bound retries, prefer a known-good fallback, and make failures visible to the team that owns the template.
Rollout Checklist Before Going Catalog-Wide
Before you point gpt-6.1-terra at the whole catalog, run through this list. Each item maps to a failure mode that only shows up at scale.
- Templates are versioned and stored in code. Every prompt has an owner and a changelog; the version string is sent with each request.
- Slot validation is enforced server-side. Empty subjects and missing constraint blocks are rejected before the request leaves your service.
- Automated checks run before human review. Decode, dimension, duplicate, and policy checks are automated and their results are stored.
- The review gate is live and staffed. Rejections capture reasons, and reason clusters are reviewed weekly against template versions.
- Retry and fallback policy is defined. Validation errors never retry; transient errors retry with bounded backoff; repeated failures fall back to the last approved asset.
- Cost guardrails are in place. Per-batch generation caps, caching of approved outputs, and template tiers are configured and tested.
- Metadata is persisted. SKU, template version, and prompt payload are stored alongside each generated asset.
- Rollback is possible. The storefront still serves manual images if generation is disabled, and the switch is a config change.
- A pilot batch has passed review. Start with one category, expand to one brand or region, then go wide.
Run the pilot, watch rejection rates and batch failure rates for a couple of cycles, and only then remove the manual workflow. When you are ready to move from pilot to production, the request shape stays the same — only the volume changes.
Related articles
View all articles →-

Guide
Getting Started with seedream-5.0-pro/image-to-image: Capabilities, Pricing, and Integration Essentials
Capability boundaries, billing model, and engineering integration practices for ByteDance's image editing model
-

Guide
seedream-5.0-pro Text-to-Image Getting Started Guide: Capability Boundaries, API Integration, and Cost Control
A hands-on developer perspective: from key parameters to a cost estimate of $0.05 per image
-

Guide
Hailuo 2.3 Fast Image-to-Video Getting Started Guide: Capability Boundaries, Pricing, and Integration Practices
MiniMax image-to-video model selection and integration key points for developers