
Tutorial
How to Use gpt-6-luna via the hiapi API: curl, Python, and a Working Request
TL;DR
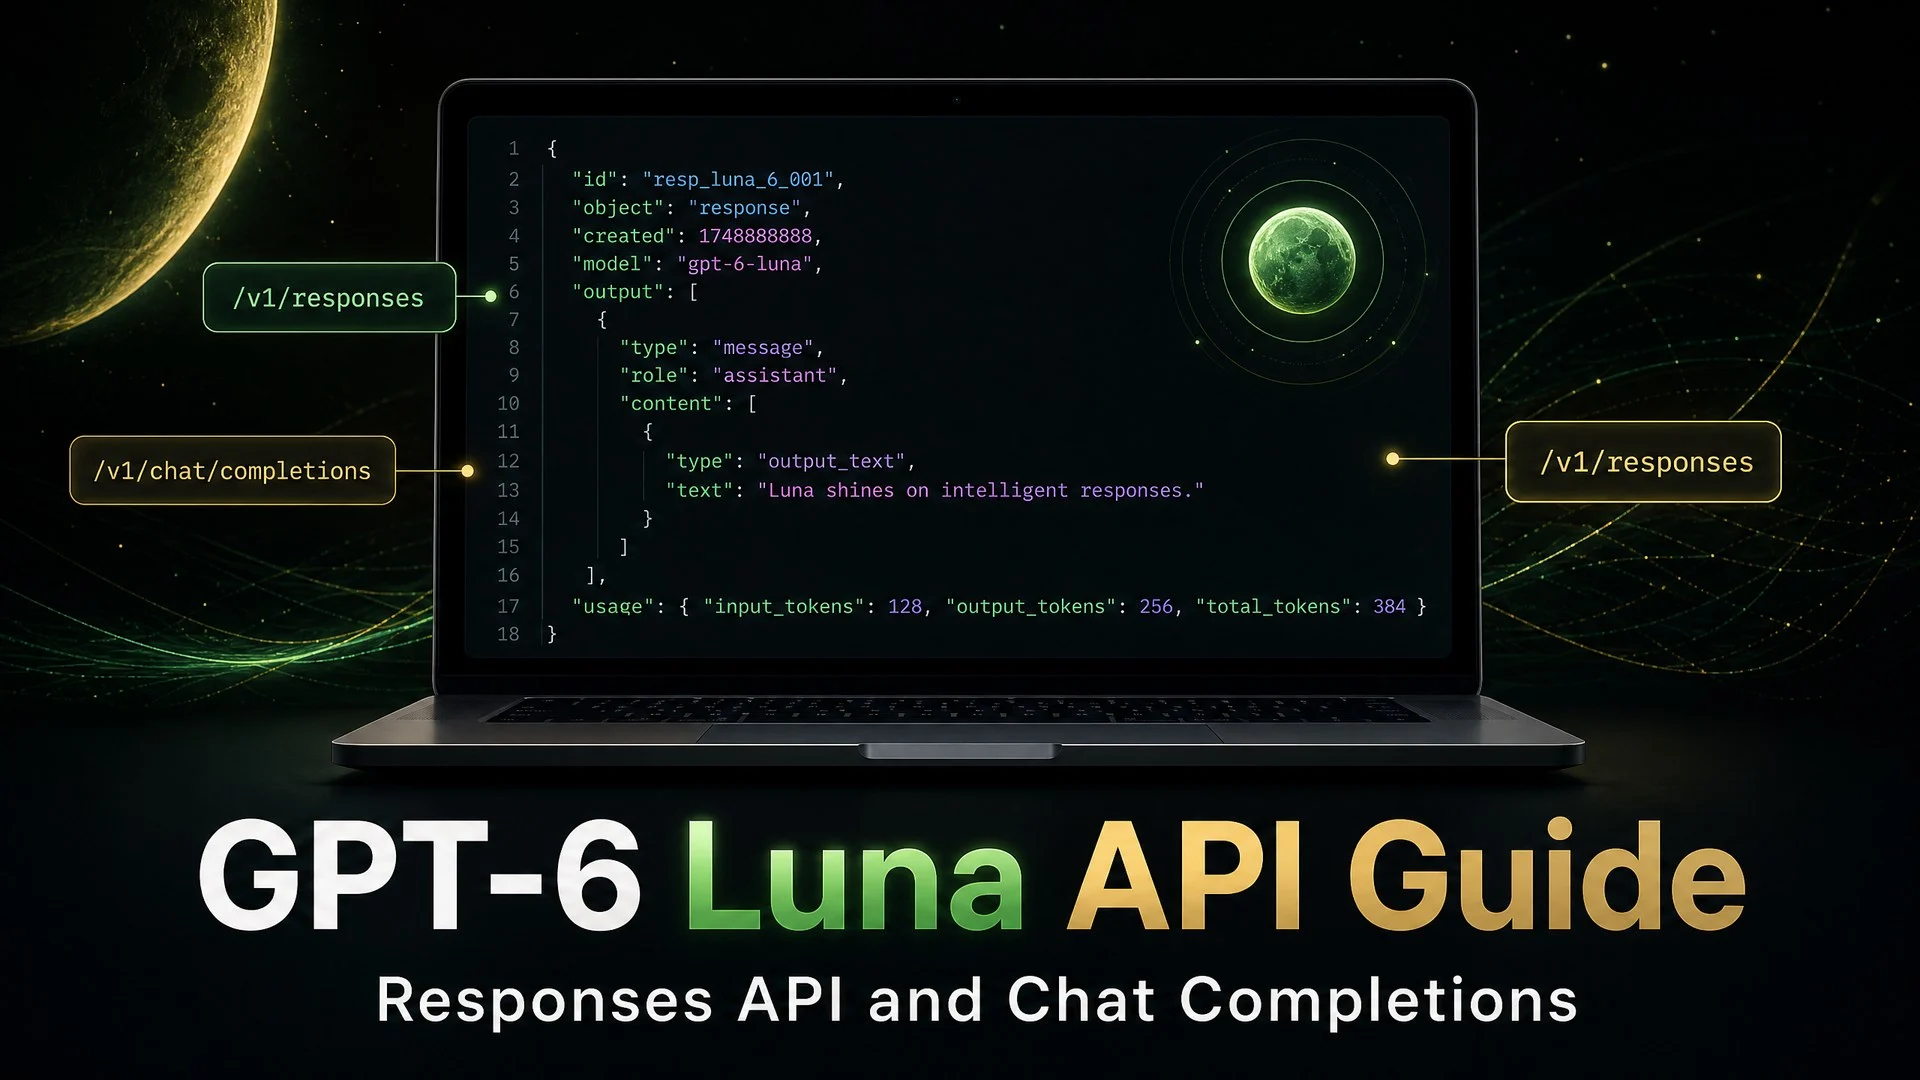
- What it is: OpenAI's newest economy text model, built for batch processing and high-throughput workloads. Live on HiAPI. Open the model page to chat directly, and new accounts get 200 free credits on sign-up.
- Pricing: Per-token billing at $0.025/M input, $0.125/M output, $0.0025/M cached read (standard tier up to 272K). The most affordable GPT text model on HiAPI, about a quarter of the list price.
- API: Default protocol is the Responses API (
POST /v1/responses), with Chat Completions (POST /v1/chat/completions) as a supported alternative. 1.05M context window, 128K max output. - Key parameters: Six reasoning effort levels (
reasoning.effort:none/low/medium/high/xhigh/max),temperature,top_p,text.format(json_schemawithstrict).
The first two questions people ask about GPT-6 Luna: how to call it, and how it differs from Chat Completions. Both answers are below.
What can GPT-6 Luna do?
- Batch text classification. Product review analysis, ticket sorting, content tagging. At $0.025/M input, classifying 100,000 items costs pocket change.
- Structured data extraction. Pull JSON from unstructured text with
text.formatandjson_schema. No post-processing or regex needed. - Content rewriting and formatting. Plagiarism rewrites, multilingual polishing, format unification. One prompt, thousands of outputs.
- Automated FAQ replies. Low-complexity customer support Q&A. Set
reasoning.effort=nonefor fast, cost-minimised responses. - Simple agent loops. Tool calls plus multi-turn conversation for automation that does not need deep reasoning.
Two ways to get started: web playground or API
Web playground (~1 minute)
- Open the GPT-6 Luna model page.
- Sign up or log in. New accounts get 200 free credits.
- Type your prompt and adjust parameters in the playground.
API integration (~5 minutes)
- Create an API key (
sk-...) in the HiAPI dashboard. POST /v1/responsesfor the Responses API (default) orPOST /v1/chat/completionsfor Chat Completions.- Read the output from the response body.
First call: curl (Responses API, recommended)
curl -s https://api.hiapi.ai/v1/responses \
  -H "Authorization: Bearer sk-YOUR_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-6-luna",
    "input": [
      {"role": "user", "content": "What is an API gateway in one sentence?"}
    ]
  }'
The response includes your answer in output[0].content[0].text:
{
  "id": "resp_...",
  "model": "gpt-6-luna",
  "output": [
    {
      "type": "message",
      "role": "assistant",
      "content": [
        {
          "type": "output_text",
          "text": "An API gateway is a server that acts as a single entry point..."
        }
      ]
    }
  ],
  "usage": {
    "input_tokens": 22,
    "output_tokens": 28,
    "total_tokens": 50
  }
}
This call consumed 50 tokens. At $0.025/$0.125, that is about $0.004. You can run thousands of test calls on the free sign-up credits.
First call: Python (Responses API)
import requests

API = "https://api.hiapi.ai/v1/responses"
HEADERS = {
    "Authorization": "Bearer sk-YOUR_KEY",
    "Content-Type": "application/json"
}

payload = {
    "model": "gpt-6-luna",
    "input": [
        {"role": "user", "content": "What is an API gateway in one sentence?"}
    ]
}

resp = requests.post(API, headers=HEADERS, json=payload, timeout=60)
data = resp.json()
text = data["output"][0]["content"][0]["text"]
usage = data["usage"]
print(f"Response: {text}")
print(f"Tokens: {usage['total_tokens']} (in {usage['input_tokens']} + out {usage['output_tokens']})")
Enforce structured output with json_schema
This is Luna's core feature for batch extraction. Set text.format to json_schema, define your name and schema, and the output is guaranteed to match:
curl -s https://api.hiapi.ai/v1/responses \
  -H "Authorization: Bearer sk-YOUR_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-6-luna",
    "input": [
      {
        "role": "user",
        "content": "Product review: The colour is great, but the sole came off after two weeks. Would not recommend."
      }
    ],
    "text": {
      "format": {
        "type": "json_schema",
        "name": "review_analysis",
        "schema": {
          "type": "object",
          "properties": {
            "sentiment": {"type": "string", "enum": ["positive", "neutral", "negative"]},
            "pros": {"type": "array", "items": {"type": "string"}},
            "cons": {"type": "array", "items": {"type": "string"}},
            "recommend": {"type": "boolean"}
          },
          "required": ["sentiment", "pros", "cons", "recommend"]
        }
      }
    }
  }'
The model returns JSON that fits the schema exactly. No markdown fences, no stray text, no parsing errors.
Chat Completions fallback
If you already have code using the Chat Completions protocol, just switch the model:
curl -s https://api.hiapi.ai/v1/chat/completions \
  -H "Authorization: Bearer sk-YOUR_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-6-luna",
    "messages": [
      {"role": "user", "content": "What is an API gateway in one sentence?"}
    ]
  }'
The Responses API is the recommended default: it uses an input array format, supports reasoning configuration and text.format structured output. Chat Completions does not support max_completion_tokens or max_tokens on Luna. Both protocols use the input format for message passing.
Key parameters
| Parameter | Required | Description |
|---|---|---|
model |
Yes | gpt-6-luna |
input |
Yes | Array of messages, each with role and content |
reasoning.effort |
No | Reasoning effort: none/low/medium(default)/high/xhigh/max |
temperature |
No | Controls randomness. Adjustable only when reasoning.effort=none |
top_p |
No | Nucleus sampling. Adjustable only when reasoning.effort=none |
text.format |
No | Output format control. Supports json_schema with strict |
max_output_tokens |
No | Maximum output token count |
tools |
No | Tool definitions for agent scenarios |
tool_choice |
No | Tool selection strategy |
About reasoning.effort levels:
none: Disables reasoning entirely. Use for classification, extraction and simple Q&A. You can freely adjusttemperatureandtop_pat this level.low/medium(default): Light to moderate reasoning for general Q&A and content generation.high/xhigh/max: Deep reasoning for complex analysis. Higher levels consume more reasoning tokens.
Set none for batch tasks, keep medium as the default for chat, and raise the level only when complexity demands it.
Common errors
- 400
model not found-- Check thatmodelis spelledgpt-6-luna. - 400
additional properties not allowed-- You passed an unsupported field such asmax_tokensin Chat Completions. Remove it. - 401
permission_denied-- Missing or invalid API key. CheckAuthorization: Bearer sk-.... - 400
json_schema validation failed-- Your schema definition is invalid. Verifyrequiredand thetypeof each property.
FAQ
Responses API or Chat Completions?
Use the Responses API for new integrations. It supports input array format, reasoning.effort, and text.format json_schema. If you have existing Chat Completions code, changing the model field is all you need.
What does reasoning.effort=none do?
It stops the model from generating reasoning tokens. The output contains only the final reply text. You can freely adjust temperature and top_p at this level. Use it for classification, extraction and formatting to save tokens and reduce latency.
How does caching work? Caching is automatic. Repeated system prompts and conversation history segments that match previous requests are billed at $0.0025/M. No configuration needed.
How do I use Batch for half-price processing?
Add "processing_mode": "batch" to your request. Tasks are queued asynchronously at 50% off. Best for workloads that do not require real-time responses.
How is 6-luna different from 5.6-luna? Half the input price ($0.025 vs $0.05), 2.4x cheaper output ($0.125 vs $0.30), Responses API as the default protocol, six effort levels (same six levels as 6-luna), ability to disable reasoning to tune temperature, and a 1.05M context window. See the comparison article.
What is the pricing compared to the list price? HiAPI charges about a quarter of the list price: $0.025/M input vs $0.10/M, $0.125/M output vs $0.50/M. Cached reads at $0.0025/M are a tenth of the list price.
More on GPT-6 Luna
- GPT-6 Luna model page: chat online, 200 free credits on sign-up
- GPT-6 Luna API pricing: $0.025/M input, the cheapest GPT on HiAPI
- GPT-6 Luna vs GPT-5.6 Luna: half the price, should you switch
- GPT-6 Luna prompts: 5 batch-scenario recipes to copy
Try it now: copy the curl command above, swap in your API key, and fire off your first call. Or open the model page to chat directly.
Related articles
View all articles →-

Tutorial
Recraft Creative Upscale: Landscape Examples
Inspect cabin, lake and watercolor examples, identify redrawn detail, and distinguish previews from full-size results.
8 -
Tutorial
OpenAI Invalid API Key: Authentication Checks
Separate OpenAI 401, 403, and 429 errors. Check runtime variables, account context, and credentials with a read-only request.
3 -

Tutorial
Kling 4.0 Prompts: 6 Ready-to-Use Templates with Real Outputs
Product, food, travel, everyday moments, ambient shots with sound and image-to-video, each with a real clip, the full prompt and a one-click prefill link.
6