
Guide
qwen-image-3.0-pro/text-to-image Getting Started Guide: Capabilities, Pricing, and Integration Practices
From capability boundaries to per-image billing—a quick integration guide for developers using text-to-image models
What problems is this model suited to solve
qwen-image-3.0-pro/text-to-image is a pure text-to-image model: it takes a text prompt as input and outputs an image. It only does text-to-image and does not include image-to-image, image editing (inpainting/outpainting), style transfer, or similar capabilities. If your product requirements involve interactions like "upload an image and modify it," that means the model selection is mismatched—you need to find a model with editing capabilities instead of trying to force this model with stacked prompts.
It suits three types of scenarios.
Marketing and operations visual assets
Needs like poster base images, event banner backgrounds, and social media graphics are characterized by batch production, consistent style, and relatively high tolerance for per-image precision. Structured prompts can reliably produce usable assets, which designers then refine with layout and typography.
Placeholder and prototype assets
Product prototypes, demos, and test environments need large numbers of placeholder images. Generating them on demand with pure text-to-image is more flexible than maintaining a static asset library, and it avoids unclear copyright provenance.
Concept drafts and inspiration exploration
Before formal design, use text-to-image to quickly explore multiple visual directions and help the team converge on a style early. The value here lies in "breadth," not "final quality."
Unsuitable scenarios
- Editing tasks that require preserving the original image structure or a person's identity;
- Layout-oriented images with hard requirements on text rendering precision;
- Interactive creation that requires multiple rounds of local modifications.
The criterion can be simplified to one sentence: does the requirement only need "text in, image out"? If yes, the model matches; as soon as "transform based on an existing image" appears, it does not match.
How to estimate costs under per-image billing
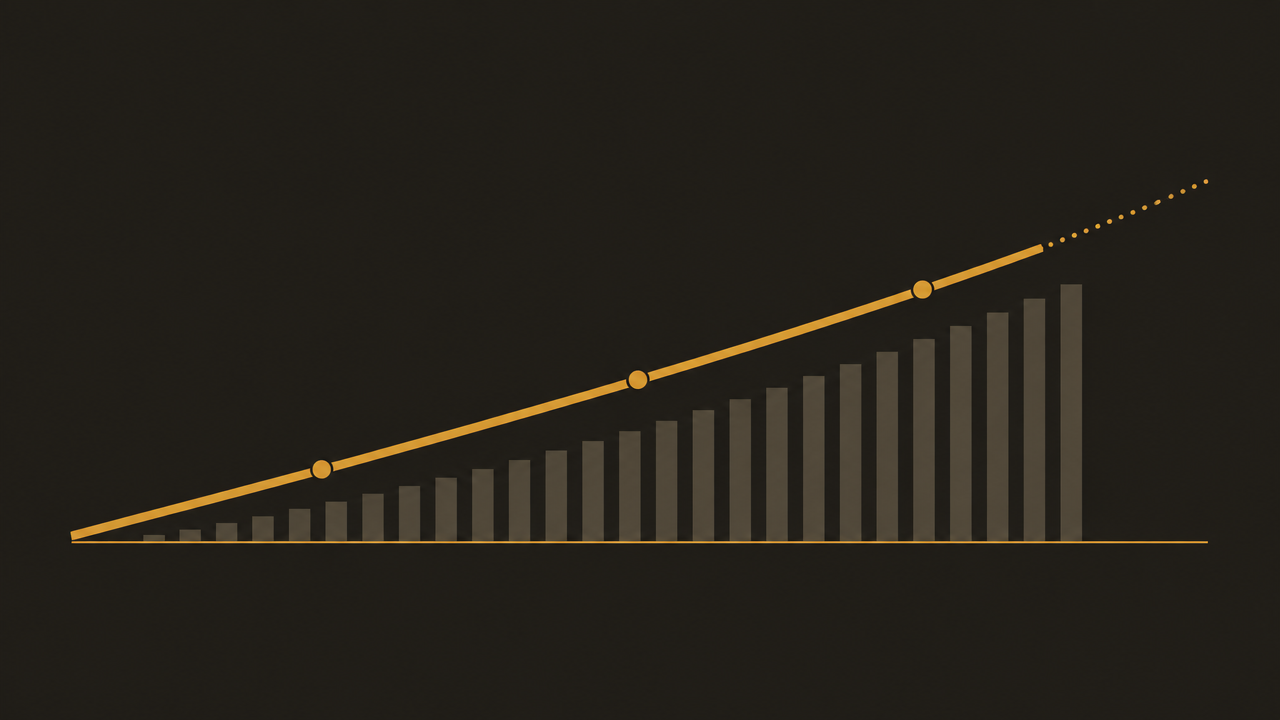
This model bills by number of generated images: each successfully generated image incurs one charge. This means total cost is linear with the number of calls, and the estimation model is very simple:
Total cost ≈ number of successfully generated images × price per image
For specific unit prices, refer to the site's pricing panel; this article does not hard-code numbers to avoid the documentation becoming outdated after price adjustments. When budgeting, simply plug the panel's current value into the formula above.
What linear growth means
The cost curve is a straight line through the origin: there are no tiered discounts to rely on and no "the more you use, the cheaper it gets" buffer. So the core of budget control is not squeezing the unit price, but reducing invalid calls.
Three factors that let costs spiral
- Retry amplification. If a failed request is automatically retried three times, and each retry actually triggers generation, that is three images on the bill. The retry policy must align with the billing basis.
- Unrestrained prompt experimentation during debugging. Repeated parameter tuning during development can easily produce far more images than expected in a single day. It is advisable to set a daily quota for the debugging environment.
- Repeated generation of identical content. The same prompt with the same parameters produces completely identical images; such calls should be intercepted by caching.
Estimation method
First determine the "daily effective image output volume" from the business side, then multiply by a "failure and retry coefficient" (initially a conservative 1.3–1.5) to get the billed image count range, and finally plug in the unit price. After launch, back-calculate the coefficient from actual bills and revise it monthly.
Control measures
- Normalize prompts so that semantically identical inputs hit the cache and directly return existing results;
- Store generated results in object storage, index them by content hash, and serve repeated requests from the read cache;
- Set concurrency limits and total image caps for batch tasks to prevent scripts from running wild.
The advantage of per-image billing is strong predictability; the disadvantage is no economies of scale. Therefore, cache and deduplication design on the engineering side directly determines unit business cost.
Integration process and parameter essentials
Integration goes through HiAPI.ai's unified interface, so there is no need to connect to each upstream provider separately. The minimal path has four steps.
Step 1: Get a key
Create an API Key in the console, issuing separate keys per environment (development/staging/production) to make subsequent quota and billing attribution by key easier. Keys should only be kept on the server side and never distributed to clients.
Step 2: Confirm the model identifier
Use the model identifier qwen-image-3.0-pro/text-to-image when calling. Note that the slash is part of the identifier; do not split or rewrite it.
Step 3: Send the first request
The minimal request body structure is the model identifier plus a prompt:
{
  "model": "qwen-image-3.0-pro/text-to-image",
  "prompt": "a minimal flat-design illustration of a mountain lake at dawn, soft gradient sky"
}
The response returns image data (URL or base64, depending on the interface's return format); immediately transfer it to your own storage after receiving it, and do not rely on temporary links long-term.
Step 4: Handle responses and errors
Distinguish three types of results: successful image generation, parameter errors (4xx, should not retry), and server or rate-limit errors (5xx/429, can retry with backoff). Only the third type enters the retry queue.
Key points to watch during calls
- Prompt length and language: structured, specific English or Chinese descriptions both work; avoid piling up meaningless adjectives;
- Output format: confirm in advance whether the interface returns binary data that can be persisted directly or a link that requires a second download;
- Idempotency: attach a unique business ID to each business request, and deduplicate retries based on it to avoid duplicate billing;
- Timeout settings: image generation takes longer than ordinary text interfaces, so client timeouts should leave sufficient margin; otherwise you get the waste of "the server has already generated the image, but the client has given up."
After the first successful run, it is recommended to establish a baseline with a few fixed smoke-test prompts, then compare any subsequent parameter or version changes against the baseline to determine whether the issue is at the integration layer.
Prompt design and output tuning
The usability rate of text-to-image depends heavily on prompt quality. In a per-image billing context, one invalid generation is a real cost, so prompt debugging should be treated as an engineering problem rather than mysticism.
From vague to structured
The problem with vague prompts is not that they are "not beautiful enough," but that they are not reproducible. Splitting the description into several stable dimensions makes results converge noticeably:
- Subject: what to draw; a single subject is better than multiple subjects;
- Style: illustration, photorealistic, flat, watercolor, etc.;
- Composition and perspective: close-up, panorama, top-down;
- Lighting and color tone: soft, high contrast, cool colors;
- Background and negative space: whether a clean background is needed for later layout work.
Iteration loop
The recommended debugging loop is: establish a baseline prompt → change one variable → record results → converge into a template. Change only one dimension at a time to determine which word had an effect. Consolidate validated templates into a prompt library, and have the business side call them by scenario instead of writing from scratch each time.
Ways to reduce invalid calls
- Small-batch probing: validate direction with a small number of images in new scenarios before scaling up;
- Negative descriptions: explicitly state what you do not want (e.g., no text, no watermark); this saves more calls than repeatedly describing the positive;
- Templating: solidify stable, effective prompts into parameterized templates to reduce randomness;
- Manual sampling: sample outputs at a certain ratio, calculate the usability rate, and use it as the basis for whether to continue tuning.
When to stop tuning
When the usability rate enters a plateau and the marginal benefit of further prompt changes is lower than the cost, shift to engineering approaches: switch composition templates, add post-processing, or narrow the applicable scope of that scenario. The goal of tuning is "good enough and stable," not perfection on every image.
Failure retries, timeouts, and result storage
Image generation is a typical slow operation, and embedding it synchronously into the main business flow is a common source of incidents. The engineering side should design the following items before integration.
Make tasks asynchronous
Client requests should only create a task and return a task ID; actual generation is completed by background workers consuming a queue. The main flow is not blocked, and generation failures do not affect other user operations. Clients obtain results via polling or callbacks.
Retry policy
- Retry only retryable errors (timeouts, 5xx, rate limits); fail immediately on parameter errors;
- Use exponential backoff with random jitter to avoid instant retries exhausting quota;
- Set a maximum retry count; after exceeding it, send to a dead-letter queue for manual investigation;
- Use business idempotency IDs for deduplication to prevent retries from producing duplicate billed image counts.
Timeouts and concurrency
Generation time varies considerably, so timeout thresholds should be set by percentiles rather than averages. Align concurrency limits with account quotas; when the queue backs up, prioritize degradation rather than infinite retries.
Result storage
Immediately transfer images to your own object storage after receiving them, and record metadata: prompt, parameters, generation time, business ID, and content hash. The content hash is used for deduplication and cache hits, and the business ID is used for reconciliation. Do not write temporary links into the database as long-term dependencies.
Reconciliation
Periodically compare the "number of requested images" recorded on the business side with the "number of billed images" on the billing side. A persistently large discrepancy indicates a problem with retry or deduplication logic. This check should be part of routine operations rather than waiting until the end of the month to notice anomalies on the bill.
The core idea of this design is: decouple generation capability from the business, keeping slow operations, failures, and retries within controllable boundaries.
Pre-launch checklist
Completing integration does not mean you can launch. It is recommended to check off each item below; do not scale up if any item is unconfirmed.
Capability and model selection
- Confirmed that the business only relies on text-to-image and no editing-type requirements are mixed in;
- Clearly identified unsuitable scenarios and added fallback prompts on the product side;
- Validated with baseline prompts that output quality meets the business minimum.
Cost
- Completed budget estimation based on the current unit price on the site's pricing panel;
- Set daily/monthly image quotas and alert thresholds;
- Implemented result caching and content deduplication so repeated requests are not billed repeatedly;
- The debugging environment has an independent quota and will not pollute the production bill.
Stability
- Generation goes through an asynchronous queue, with no synchronous blocking in the main flow;
- Retries cover only retryable errors and have backoff and caps;
- Idempotency IDs are implemented, so retries do not create duplicate tasks;
- Timeout thresholds are set by percentile and verified through load testing.
Data and operations
- Image results have been transferred to own storage with complete metadata;
- Keys are isolated by environment and held only on the server side;
- A periodic reconciliation mechanism exists between requested image counts and billed image counts;
- The dead-letter queue has an owner and a handling process.
Observability
- Key metrics (success rate, average latency, retry rate, cache hit rate) are connected to monitoring;
- Failure samples can be traced back to the specific prompt and parameters.
Going through the checklist usually exposes most pitfalls in advance. The model capabilities themselves are already encapsulated on HiAPI.ai; the remaining risks are basically in engineering and cost management—build these two areas solidly, and text-to-image capabilities can land stably in your product. Wishing you a smooth launch.
Related articles
View all articles →-

Guide
Getting Started with seedream-5.0-pro/image-to-image: Capabilities, Pricing, and Integration Essentials
Capability boundaries, billing model, and engineering integration practices for ByteDance's image editing model
-

Guide
seedream-5.0-pro Text-to-Image Getting Started Guide: Capability Boundaries, API Integration, and Cost Control
A hands-on developer perspective: from key parameters to a cost estimate of $0.05 per image
-

Guide
Hailuo 2.3 Fast Image-to-Video Getting Started Guide: Capability Boundaries, Pricing, and Integration Practices
MiniMax image-to-video model selection and integration key points for developers