
HeyGen
 HeyGen
 Avatar IV
heygen-avatar-iv
Upload a single photo plus a script to generate a talking avatar video with lip sync, facial expressions, and gestures, supporting 1280p+ output, ideal for digital presenters and voiceover content
Try heygen-avatar-iv
Input
Showcases
View all showcasesOutput
videoHeyGen Avatar IV Text-to-Video Capability Diagram
Style Spoken presentation · Explanation · Avatar Video
Reference inputs
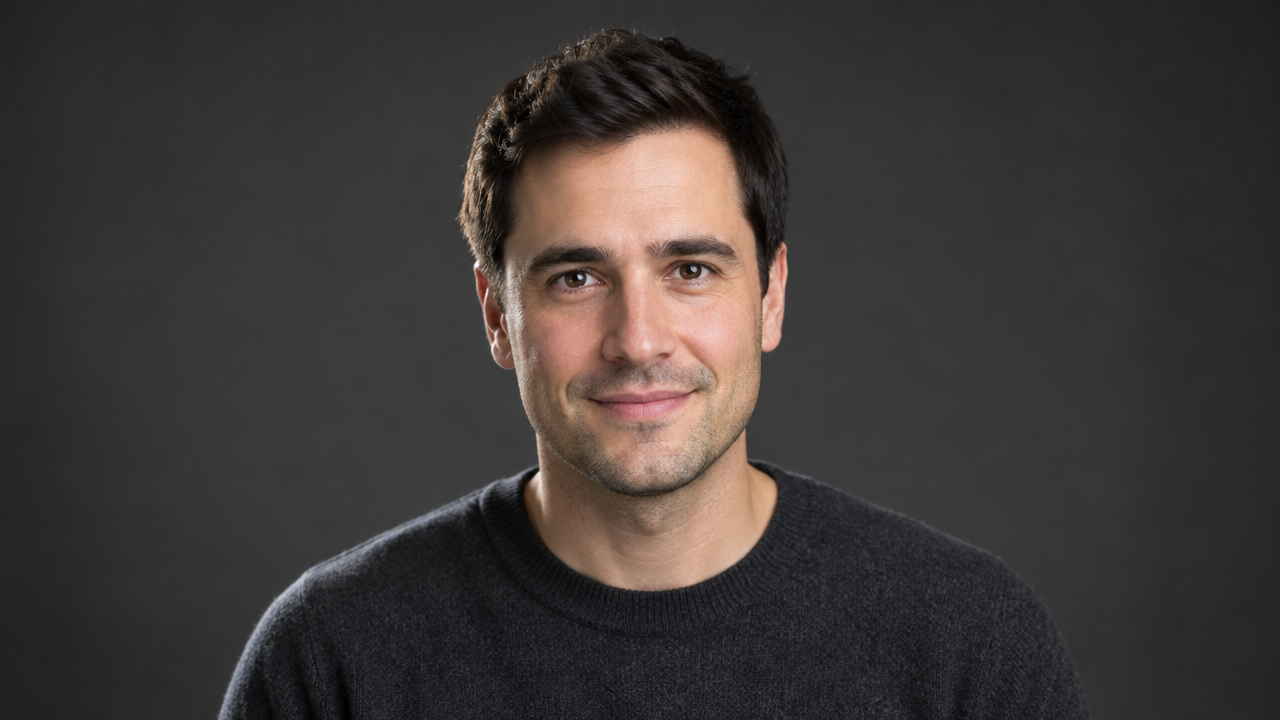
image_url
Prompt
A presenter speaks directly to the camera in a clean studio setting: head-and-shoulders framing, facing forward, steady eye contact with the lens, subtle head movement and natural gestures matching the speaking rhythm; soft key light from the front left with gentle fill light, a neutral dark gray seamless background, shallow depth of field, 1080p 16:9 widescreen composition, a realistic corporate explainer style, with a calm and confident pace.
Copy the full prompt and adapt it for your own generation.
Tags
HeyGen Avatar IV Prompt Formula Card: A Visual Guide to Structured Writing
Style Explanation · Prompt Engineering · talking avatar
Reference inputs
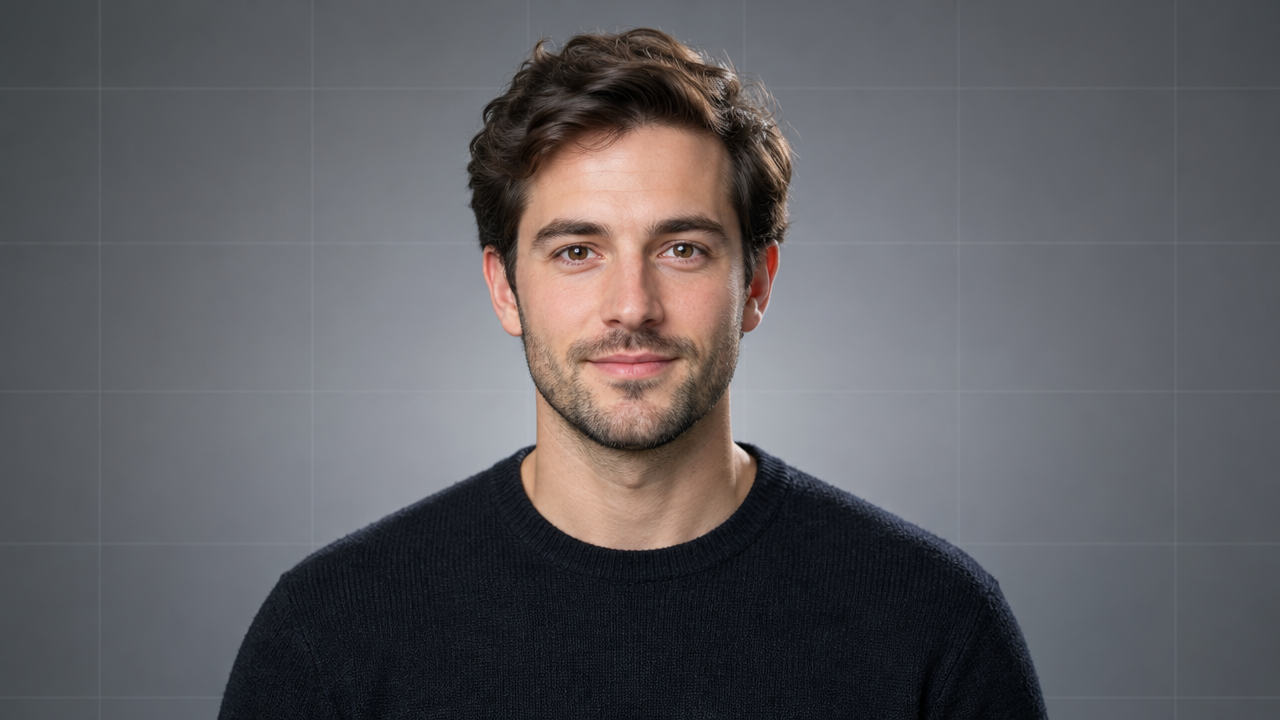
image_url
Prompt
A presenter facing the camera directly, speaking straight to the lens in a tidy studio setup, holding up a printed prompt formula index card; medium close-up, with a slow, subtle push-in and gentle handheld drift, soft key light paired with a rim separation light, shallow depth of field that keeps the card edges clear and legible while the face remains sharp; a steady, instructional pace, with small natural gestures pointing to the card in each section, a soft neutral gradient background with faint grid lines suggesting a document layout; crisp image, high detail, 1080p quality.
Copy the full prompt and adapt it for your own generation.
Tags
Visual Notes on Camera Movement Language: Avatar IV Talking-Head Demo
Style camera-language · talking avatar · Explanation
Reference inputs
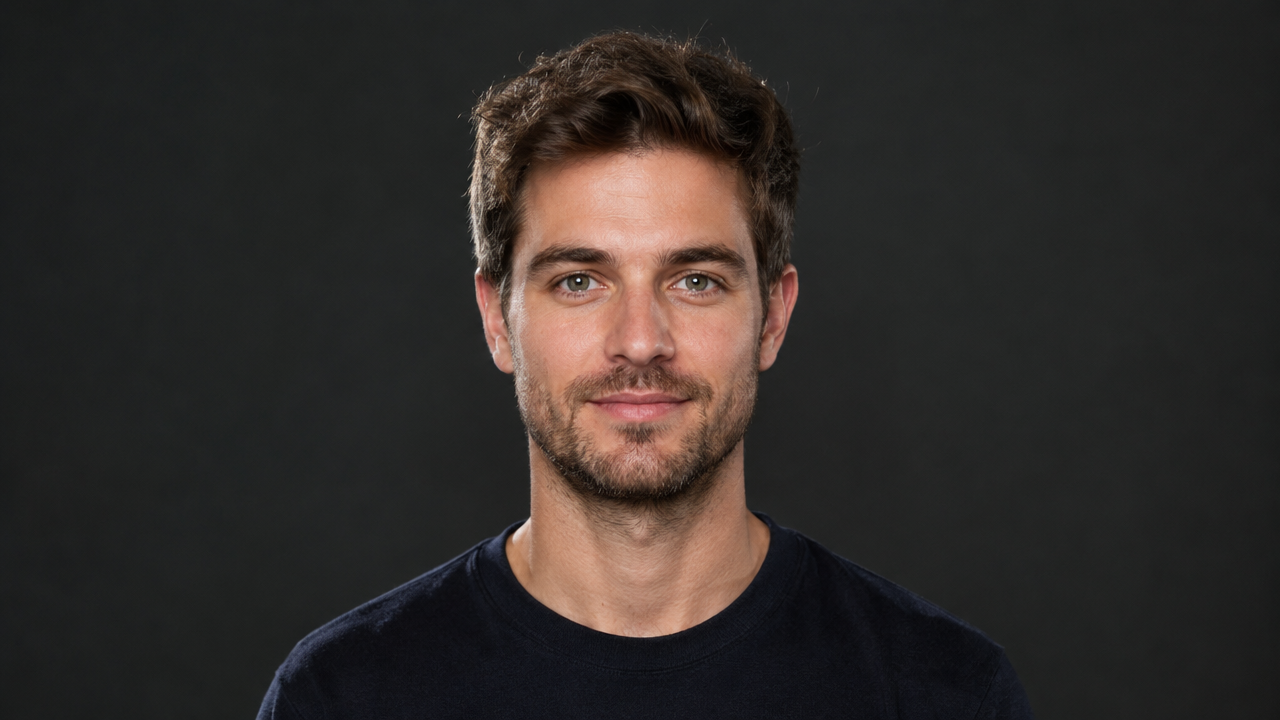
image_url
Prompt
A presenter facing the camera directly speaks straight to the lens in a calm, explanatory tone, as if annotating a visual notebook about camera movement on camera. Their gaze stays steadily on the lens, with slight natural head movement and occasional explanatory gestures indicating panning, push-ins, and tilts. Neutral, evenly lit studio composition with a dark, low-saturation background, carrying an overall screen-recording atmosphere, steady pacing, with brief pauses between each camera-movement term.
Copy the full prompt and adapt it for your own generation.
Tags
HeyGen Avatar IV Storyboard Concept: From Text to Talking Picture
Style talking avatar · Storyboard · Narrative
Reference inputs
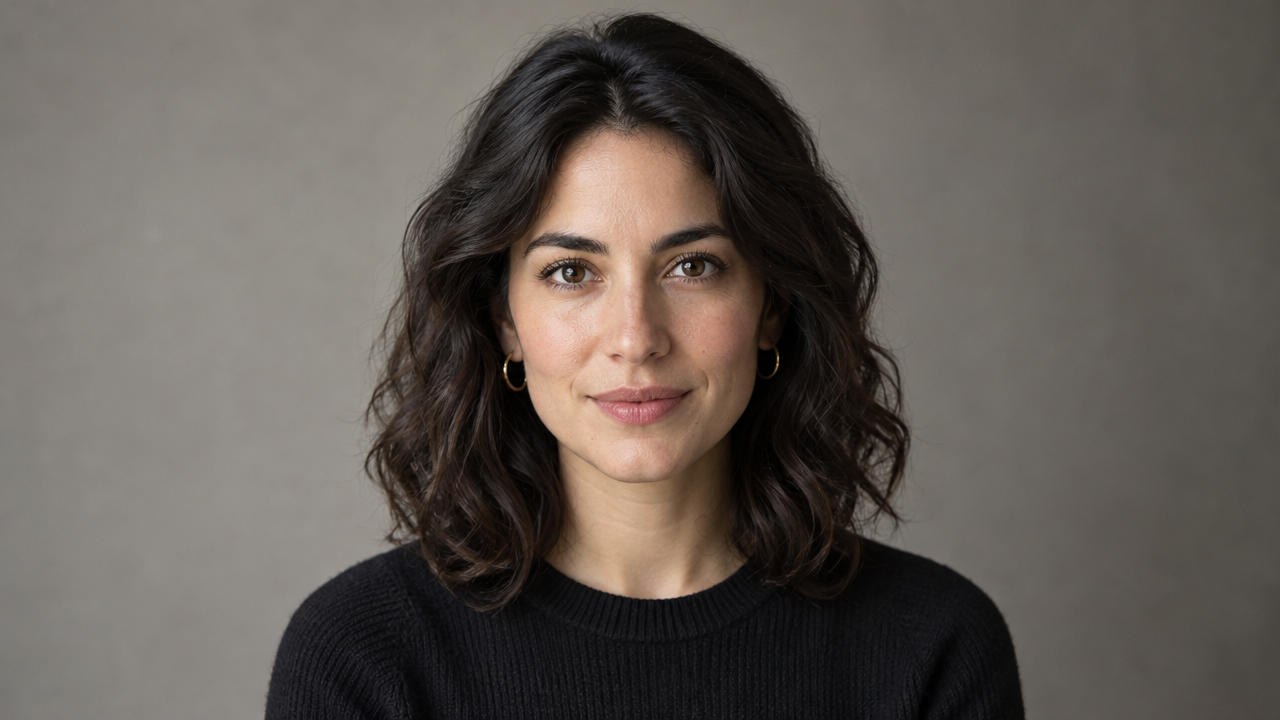
image_url
Prompt
A single frontal portrait is turned into a talking video: the person delivers a short storyboard voiceover with natural lip sync, accompanied by slight head movement and expressive gestures, framed in 16:9 with a clean neutral background, a steady medium close-up, soft key lighting, and a calm, confident pace.
Copy the full prompt and adapt it for your own generation.
Tags
Pricing
heygen-avatar-iv per second
| Unit Price | $0.150 |
|---|
Positioning Overview
heygen-avatar-iv is a talking-avatar video model offered by HeyGen and called through the unified HiAPI.ai interface. Developers upload a single frontal face photo and provide either a script text or an audio clip to generate a talking video with lip sync, facial expressions, and gestures. It supports 720p and 1080p output as well as multiple aspect ratios, making it suitable for developers and content teams that need to quickly produce digital spokespeople or character narration materials.
Key Highlights
- Drive a full talking video with a single photo—Just one frontal face photo plus a script or audio yields a finished clip without filming or building 3D assets.
- Expressions and gestures move with the voice—The output goes beyond lip alignment: facial expressions and head motions change naturally with the speech, approaching the look of real-person delivery.
- Dual input via script text and audio—You can either fill in a script and choose a voice, or pass in an HTTPS audio file for lip sync, fitting existing dubbing workflows.
- Configurable aspect ratio and background—Multiple ratios such as 16:9, 9:16, and 1:1 are available, and solid-color or image backgrounds can be specified to fill the frame.
Capabilities
Generate talking video from a photo: Pass in one frontal face photo to generate a talking video; the output is a video file that can be used directly as a finished clip or for further editing.
Script to speech driving lip movement: Fill in script text and specify a built-in voice; the model synthesizes speech and drives the avatar to talk, with each script up to 5000 characters.
Audio lip sync: Pass in an HTTPS audio link to make the photo speak according to the audio's lip movements; each audio clip can be up to 600 seconds, and in this case the script and voice parameters do not take effect.
Output specification control: Choose 720p or 1080p resolution and set a ratio of 16:9, 9:16, 4:5, 5:4, 1:1, or follow the original image, fitting landscape, portrait, and square publishing placements.
Frame background fill: When the output ratio differs from the photo ratio, solid-color or image backgrounds can fill the blank areas to avoid empty edges in the frame.
Use Cases
- Marketing teams producing digital spokesperson videos—Generate talking-head videos from product scripts and brand character photos for websites, ad placements, and social media, with no need to schedule real people on camera.
- Training departments generating course explanation materials—Turn course handouts into scripts and batch-generate explanation videos with a consistent persona for embedding into learning platforms or courseware.
- Short-video creators producing vertical talking-head clips—Choose a 9:16 ratio and a selected voice to generate vertical talking-head material for direct use in short-video platform content updates.
- Multilingual content adaptation for existing dubbing—Pass in existing dubbing audio for lip sync and pair it with a photo to generate talking-head footage in the corresponding language for content localization.
Limitations and Selection Advice
The input photo must be a clear, frontal human face; profile views, occlusions, or group photos will noticeably affect results, and generation quality depends heavily on the source image. The output is a video rather than a pure text finished product, so a script or audio must be prepared in advance. A single audio clip is capped at 600 seconds and a script at 5000 characters; overly long content must be generated in segments. If you only need preset avatar portraits or real-person digital doubles, you should choose the corresponding other model routes.
What's new
View changelog →- New model New model: heygen-avatar-iv turns one portrait photo into a…
Frequently asked questions
View all FAQs →-
What inputs does HeyGen Avatar IV need?
One portrait photo plus one driving method: a script with a chosen voice, or an audio file. With a script and no voice selected, the default voice Warm Pro Narrator is used.
-
What kind of photo works best?
A single, front-facing person with a clear, unobstructed face, even lighting and a relaxed closed mouth gives the steadiest result. Profiles, masks, group photos and tiny faces do not work well.
-
How long is the output video?
No duration parameter is needed. With a script the length follows the text and speaking pace; with audio it matches the uploaded file, which can be up to 600 seconds.
-
Which aspect ratios and resolutions are supported?
Aspect ratios 16:9, 9:16, 4:5, 5:4, 1:1 and auto (keeps the photo's ratio); resolutions 720p and 1080p.
Create a generation task
https://api.hiapi.ai/v1/tasks Headers
AuthorizationstringRequiredAccount API key. Required on every request. Example: Bearer YOUR_HIAPI_API_KEY. Get your API key
Content-TypestringOptionalThe request body is always parsed as JSON; when sent, only application/json (optionally with charset) is accepted — any other value returns 415. Example: application/json.
Idempotency-KeystringOptionalIdempotency key, up to 255 bytes. Retries with the same key from the same account create the task only once; replays return the original taskId.
On network timeouts or client retries, the same key creates the task only once — no double charges (scope: the API key's account). Use a business-unique identifier as the key (e.g. "order-42"); replays return the original taskId, and keys expire 24 hours after the first request. See the Unified Async API overview for the full scenario matrix.
Body
modelstringRequiredCurrent fixed value: heygen-avatar-iv
routestringOptionalCurrent fixed value: default
inputobjectRequired
Business parameters for heygen-avatar-iv and route default — see the parameter table below.
voicestringOptionalDefault: "Warm Pro Narrator"minLength 1Specifies the voice used for the digital human to read the script; defaults to Warm Pro Narrator. This parameter is ignored when audio_url is provided.
Warm Pro NarratorChill BrianIvyJohn DoeMonika SogamHope Archer BrittneyShow all (94)
PatrickDavid CastlemoreMichael CAdam Stone JuniperCassidy Jessica Anne BogartArabellaAndrewSpuds Oxley Grace ElderHelenCanyon RiversDerya - Lifelike - ExcitedMellow MarcusJack Sterling - BroadcasterBrenda - UGC - 1.mp4ReidReaganTerryJennyRadio RickDeniseTim in car - ExcitedIskanderThompsonDelicate Daisy - ExcitedKingstonGeorge UGC 1Bold BlakeJaneExpressive EvanMarianne - IAAaronModern Recipe Host - Voice 1WillowCute Chloe - FriendlyRafaelJune - LifelikeCrisp ChloeSlick SimonNassim - InformativeBaritone BenMaxwellEllie Faye - ExcitedMilaniFeisty Fiona - ExcitedProfessor DeanRose - UGC - 1.mp4ShonaHudson WilderAnn - IAAlastair KensingtonOxleyChristinaAndrew Rizz PeytonGerardo - OutdoorChloe - LifelikeStephanieAnthony - IASignal - Voice 1LucaLisa - Voice 1T.W.TuckerJack Sullivan - SeriousWinterMireia - LifelikeGeorgiaStellaMasha - LifelikeCharming Charles - FriendlySerenityAnnie - ExcitedRalphBethanyDominicMason FinnLeenaVeteran VictorTamaraNik PublicCalm ChloeSevikReillyRaulImposing IanRelaxed RayDexter - ProfessionalRelaxed RickEdwinRupert BlackwoodGinnyHopepromptstringOptionalminLength 1maxLength 5000The script text that the digital human will read aloud; required when audio_url is not provided.
audio_urlstringOptionalpattern ^https://An HTTPS audio URL used for lip sync, with a maximum duration of 600 seconds; once provided, both prompt and voice are ignored.
image_urlstringRequiredpattern ^https://An HTTPS URL of the photo to be animated, which must contain a single clear, front-facing face, supporting jpg, jpeg, png, webp, gif, avif, heic, and heif formats.
backgroundobjectOptional
The background setting used to fill the areas of the frame not covered by the portrait when the output aspect ratio differs from that of the original photo; it can be specified by color or image, and defaults to white.
typestringRequiredThe fill method for the background, determining whether the value field is interpreted as a color or an image URL.
colorimagevaluestringRequiredminLength 1The specific value of the background: when type is color, pass a #RRGGBB hexadecimal color value; when type is image, pass an HTTPS image URL.
resolutionstringOptionalDefault: "720p"The resolution of the output video; defaults to 720p.
720p1080paspect_ratiostringOptionalDefault: "16:9"The aspect ratio of the output video; defaults to 16:9. When set to auto, the source photo's ratio is preserved with priority, falling back to 16:9 if it cannot be read.
16:99:164:55:41:1autocallbackobjectOptional
Terminal-state notification config. When omitted, no callback is delivered — poll the task yourself. See the callback note below.
Provide callback.url when creating a task and HiAPI POSTs to your service once the task reaches a terminal state — no polling needed. The callback payload mirrors the task detail structure; signature verification, delivery retries and idempotency are documented on the Unified Async API overview page.
urlstringRequiredRequired when callback is present. A POST is sent to this URL once the task reaches a terminal state; must be a valid http(s) URL.
whenstringOptionalDefault: "final"Only final is supported today — notified on both success and fail.
finalstoragestringOptionalDefault: "temp"Artifact storage tier: temp (default, retained about 7 days) or persistent (long-term, billed by size). Insufficient balance or exceeding the storage cap silently downgrades to temp; the effective tier is shown in the task detail response.
temppersistentRequest examples
# Submit an async task; returns a taskId immediately (no waiting for generation)
curl -X POST "https://api.hiapi.ai/v1/tasks" \
  -H "Authorization: Bearer $HIAPI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "heygen-avatar-iv",
  "input": {
    "voice": "Warm Pro Narrator",
    "image_url": "…",
    "resolution": "720p",
    "aspect_ratio": "16:9"
  }
}'
const res = await fetch("https://api.hiapi.ai/v1/tasks", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.HIAPI_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
model: "heygen-avatar-iv",
input: {
"voice": "Warm Pro Narrator",
"image_url": "…",
"resolution": "720p",
"aspect_ratio": "16:9"
}
}),
});
const task = await res.json();
// { code: 200, message: "success", data: { taskId } }import os, requests
res = requests.post(
"https://api.hiapi.ai/v1/tasks",
headers={"Authorization": f"Bearer {os.environ['HIAPI_API_KEY']}"},
json={
"model": "heygen-avatar-iv",
"input": {
"voice": "Warm Pro Narrator",
"image_url": "…",
"resolution": "720p",
"aspect_ratio": "16:9"
}
},
)
print(res.json()) # { code, message, data: { taskId } }200 OK
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-01HZTQ8BX2N3GM3YFK4Z9D7VQR"
  }
}
400 Bad Request
{
  "code": 400,
  "message": "invalid request",
  "data": null,
  "error_code": "INVALID_REQUEST"
}
Get task detail
https://api.hiapi.ai/v1/tasks/:id Response fields
taskIdstringRequiredTask ID, always prefixed with tk-hiapi-.
modelstringRequiredResolved full model name. Tasks submitted with the route parameter return base@route (e.g. gpt-image-2/text-to-image@ext); otherwise identical to the name passed at creation.
routestringOptionalPresent only when the task was submitted with an explicit route parameter; echoes the submitted value.
statusstringRequiredTask status.
queued Queued, not started yet.
handling Being processed.
archiving Processing finished, artifacts being prepared.
success Terminal: completed, artifacts available (output returned).
fail Terminal: failed (error returned).
After submission, check status: success and fail are terminal, everything else is non-terminal. Poll every 1–3 seconds until terminal. On success, download artifacts from output[].url and transfer them before expireAt; pass storage: "persistent" at creation time when long-term retention is needed.
creatednumberRequiredTask creation time (Unix seconds).
completednumberRequiredUnix seconds when the task reached a terminal state; fixed to 0 while not terminal.
outputarrayOptional
Present only when status == success. Artifact list — always an array; a single task may return multiple types at once (e.g. video + first_frame).
Array [ object ]
Array items
urlstringRequiredArtifact URL, directly downloadable.
typestringRequiredCurrent possible values: video, image, audio, first_frame, last_frame, thumbnail; more may be added later.
expireAtnumberRequiredUnix seconds until which the artifact remains accessible; download or transfer before it expires.
errorobjectOptional
Present only when status == fail.
codestringRequiredBusiness error code.
messagestringRequiredError description.
Response examples
Success
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-01HZTQ8BX2N3GM3YFK4Z9D7VQR",
    "model": "happyhorse-1-0",
    "status": "success",
    "created": 1777282033,
    "completed": 1777282099,
    "output": [
      {
        "url": "https://cdn.hiapi.ai/tasks/.../video.mp4",
        "type": "video",
        "expireAt": 1777886899
      }
    ]
  }
}
Processing (non-terminal)
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-...",
    "model": "happyhorse-1-0",
    "status": "archiving",
    "created": 1777282033,
    "completed": 0
  }
}
Failed
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-...",
    "model": "happyhorse-1-0",
    "status": "fail",
    "created": 1777282033,
    "completed": 1777282099,
    "error": {
      "code": "TASK_FAILED",
      "message": "task failed"
    }
  }
}Articles
View all articles →Related Models
View all models →Same Type
-
 Wan 2.7 Video Alibaba $0.100 /second
-
 Ray 3.2 Luma $0.214 /video
-
 Veo 3.1 Fast Google $0.170 /second
-
 HappyHorse 1.1 Alibaba $0.160 /second
-
 HeyGen Avatar V HeyGen $0.150 /second
-
 Kandinsky 6.0 Pro $1.93 /video
-
 Runway Gen 4.5 Runway $0.172 /second
-
 Creatify Boreal Creatify $0.015 /second
-
 Kling 3.0 Turbo Kuaishou $0.130 /second
-
 Seedance 2.5 ByteDance $0.121 /second
-
 FLUX 3 Video Black Forest Labs $0.090 /second
-
 Wan 3.0 Video Alibaba $0.040 /second