
Guide
flux-3-video Getting Started Guide: Capability Boundaries, API Integration, and Cost Control
From text-to-video to video-to-video: capabilities, pricing, and integration essentials from a developer's perspective
What flux-3-video is and who it's for
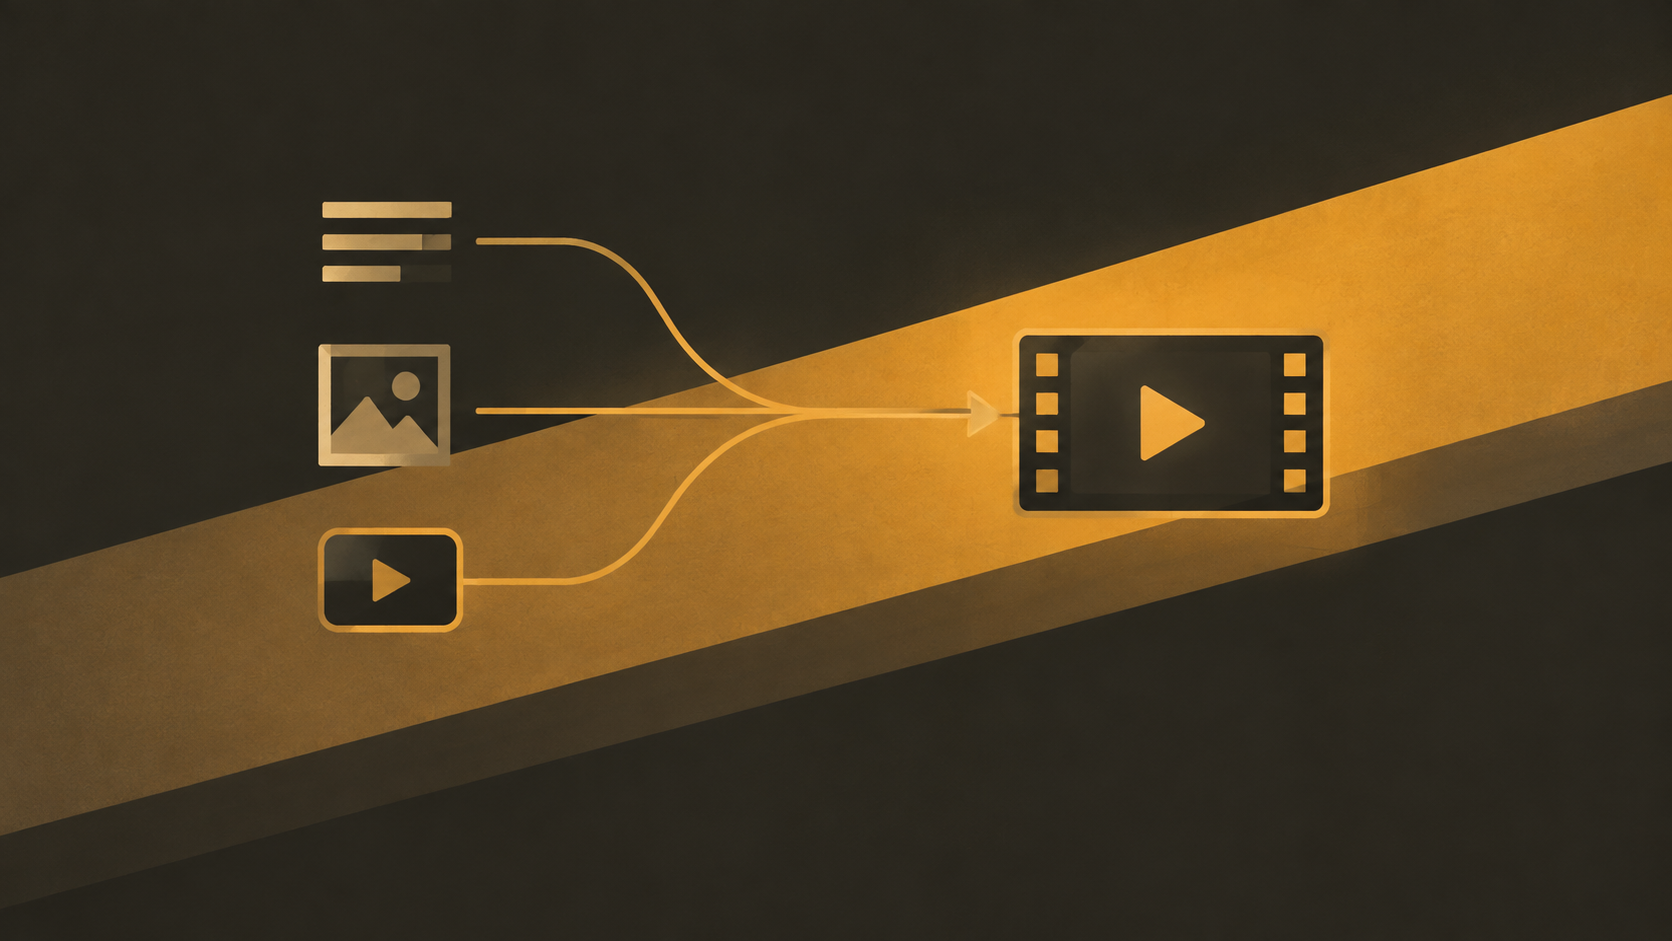
flux-3-video is a video generation model released by Black Forest Labs, with a pure video file as its output type. It covers three input modalities at once: text-to-video, image-to-video, and video-to-video. This means you don't have to find separate models for the "no source material" and "existing source material" situations—the same model can handle everything from generating from scratch to rewriting based on source material.
To judge whether it belongs to the model category you need, ask three questions:
- Does your product need video as its output, rather than images or text? If you only need static assets, image models are cheaper and faster.
- Does your source material fall into one of text, image, or video? As long as one of these is satisfied, there's a corresponding entry point.
- Can you accept a long-running asynchronous invocation pattern? Video generation isn't a millisecond-level request, so the pipeline must be designed as an async task.
For teams doing batch production of marketing assets, short-video draft generation, or stylized rewriting of source material, a model that supports all three modalities at once is usually more cost-effective to integrate than assembling multiple specialized models. For scenarios that are extremely latency-sensitive and require real-time responses, it is not suitable for direct integration.
Three generation paths: text-to-video, image-to-video, and video-to-video
The difference between the three entry points lies in what you already have on hand and what you want the model to fill in.
text-to-video
The input is a text prompt, and the output is an entirely new video. Use cases include concept demos, storyboard drafts, and creative exploration starting from no source material. The advantage is that it doesn't depend on any prior assets; the disadvantage is that it has the weakest controllability—visual details are entirely guided by the prompt, and multiple trial runs are needed to get close to expectations.
image-to-video
The input is a reference image plus a text prompt, and the output is a moving video extending from that image as the starting point. It's suitable for scenarios where you already have a finalized image (product shots, posters, character designs) that needs to "come to life." Compared with text-to-video, its visual consistency is better guaranteed, because the composition and subject are already locked in by the image, and the text is only responsible for describing motion and camera work.
video-to-video
The input is an existing video, and the output is a rewritten video. It's suitable for style transfer, asset remastering, and secondary processing of existing clips. It is the most sensitive to upstream material quality: the input video's resolution, frame rate, and content complexity all affect how predictable the result is.
The rule of thumb for choosing a path is: if you have a video, use video-to-video; if you have an image, use image-to-video; only if you have nothing at all should you use text-to-video. The more concrete the source material, the higher the controllability, the fewer trial runs, and the lower the cost.
How per-second billing works: the cost model at $0.25/second
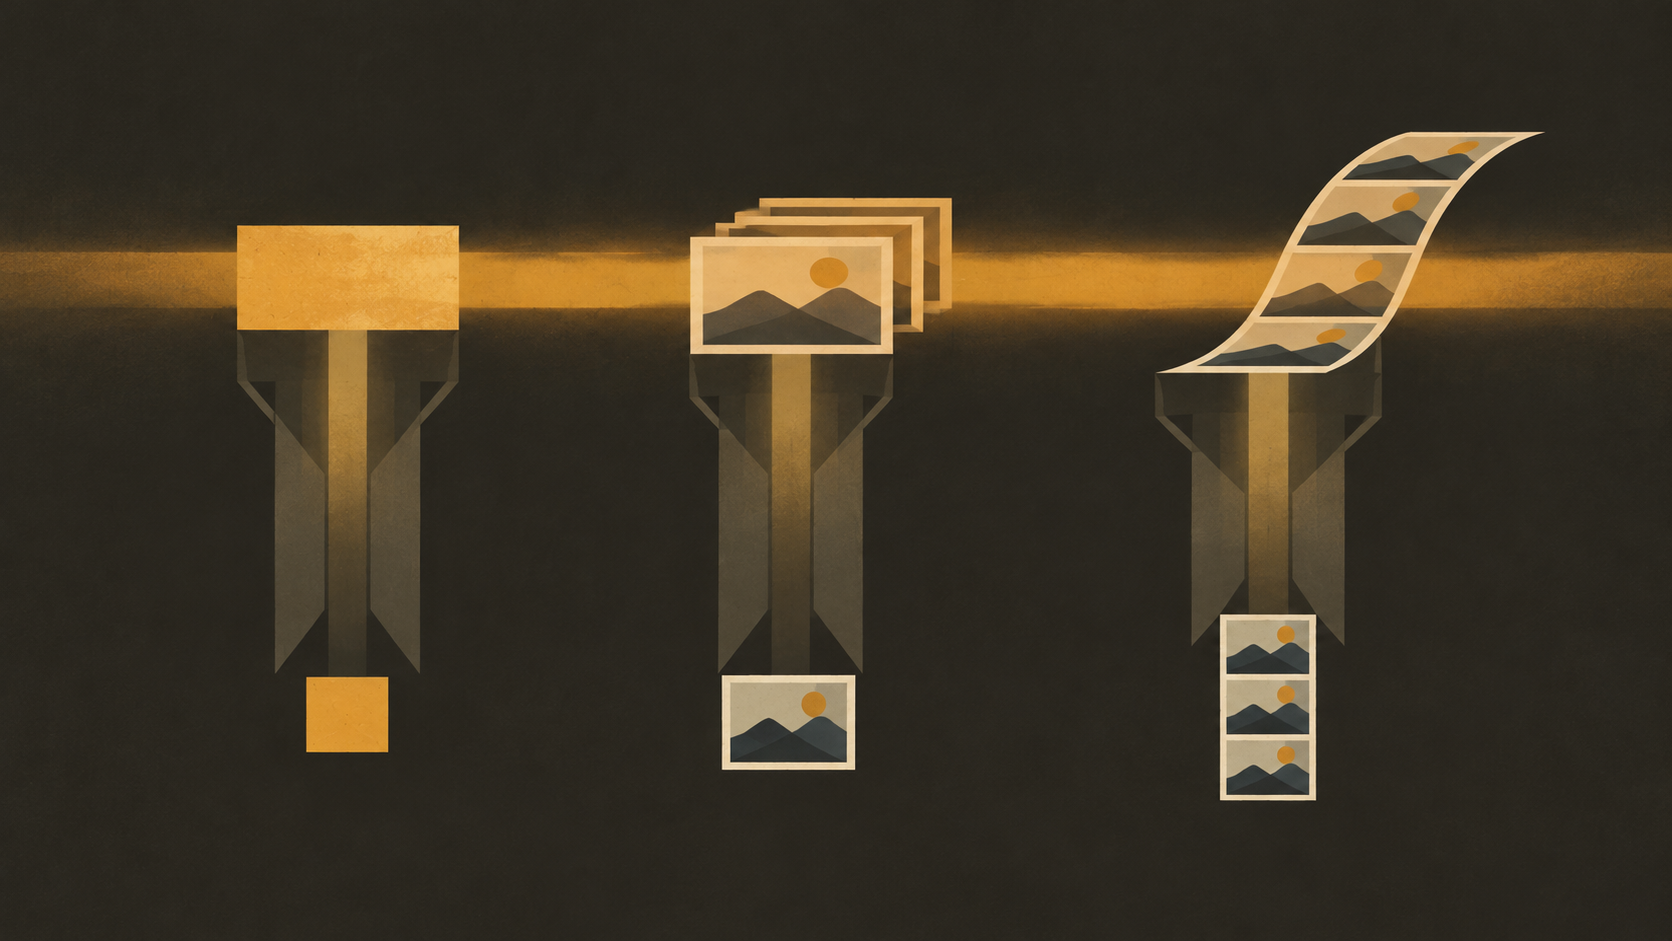
flux-3-video is billed by the seconds of output video, at a unit price of $0.25/second. The cost has a strictly linear relationship with duration:
total cost = output seconds × unit price
This straight line leads to two direct corollaries.
First, duration is the primary cost lever. Going from 5 seconds to 30 seconds scales the cost by six times, rather than being priced per "request." When budgeting, don't estimate by number of calls—estimate by total seconds: estimate daily output → convert to total seconds → multiply by the unit price.
Second, retries directly add up in cost. If a failed rerun has already produced output seconds, the cost has genuinely been incurred. Therefore, the cost model must include a failure budget rather than assuming every call succeeds on the first try.
A few cost-reduction directions, ranked by cost-effectiveness:
- Shorten the duration: first verify the prompt and parameters with the shortest usable duration, then extend once the effect is confirmed.
- Reduce wasted trial runs: version your prompts, reference images, and parameters to avoid repeatedly debugging the same configuration.
- Set a duration cap per scenario: limit the maximum seconds per request at the business layer to prevent abnormal inputs from triggering excessively long tasks.
- Distinguish previews from final cuts: use short durations in the draft stage, then generate the full version after finalizing.
For the specific unit price, refer to the site's pricing panel, and use the real-time figures on the panel when doing capacity planning.
Parameters and input conventions to settle before integration
Before writing the first line of code, confirm the contract clearly—this saves a lot of rework. Several categories of items need to be clarified:
Duration and output specifications
The supported duration range per request, the selectable resolutions and frame rates, and how to specify the aspect ratio all belong to the model's capability boundaries. You must confirm these against the official documentation—don't assume from experience. Video models often have constraints on input dimensions; going out of range may result in rejection or silent adjustment.
Form conventions for input materials
The three modalities have different input requirements: the length and language of text prompts, the format and dimensions of reference images, and the encoding and duration limits of input videos all need to be checked one by one. This is especially true for video-to-video—the input video itself may also have a seconds limit, which directly affects the range of processable materials.
How to retrieve output
Video is a large binary file, so it usually isn't inlined directly in the response body; instead, a downloadable result URL or task artifact reference is provided. At integration time, confirm: the validity period of the result URL, whether additional authentication is required, and how long files are retained. This determines your storage strategy—whether to immediately transfer to your own object storage or rely on temporary links.
The benefits of a unified interface
When integrating through HiAPI.ai's unified interface, the authentication method and the invocation pattern for task submission and result retrieval stay consistent with other models, so switching or adding models doesn't require rewriting the invocation layer. Parameter names and value ranges still follow the official documentation as the sole basis; this article makes no guesses about unconfirmed fields.
Invocation orchestration and failure handling for long-running tasks
Video generation is a typical asynchronous long-running task and cannot be designed as a synchronous request. The recommended pipeline is a three-stage process: "submit → poll → download":
1. Submit the task and get the task identifier
2. Poll the task status at a fixed interval
3. When the status is success, download the result and transfer it to storage
4. When the status is failure, decide whether to retry according to policy
Submission stage
Submission requests should carry an idempotency key (which can be derived from a business-side unique ID) to avoid duplicate tasks when the client resends due to network jitter. Immediately after a successful submission, record the task identifier and request parameters in the database—this is the basis for later reconciliation.
Polling stage
Polling should have a backoff strategy: a short initial interval, gradually lengthened as duration grows, with an overall timeout cap. Don't poll at a fixed high frequency—it both wastes quota and fails to handle long-tail tasks. Make the polling state machine recoverable—after a process restart, it can pull unfinished tasks from the database and continue tracking them.
Timeouts and retries
Distinguish two types of failures:
- Retryable failures: network errors, rate limiting, temporary server unavailability. These should be retried with exponential backoff and a maximum number of attempts.
- Non-retryable failures: invalid parameters, non-compliant input materials, rejected content. Retrying these is meaningless and only amplifies cost—the error should be surfaced directly to the caller for correction.
Result handling
After a success callback or polling to a success status, transfer the video to your own storage immediately; don't rely on temporary links for long. Transfer failures should also be retried separately, to avoid a task succeeding while its artifact is lost.
Hidden costs from retries and invalid calls
Per-second billing combined with asynchronous retries is a common recipe for runaway costs. Two types of hidden expenses deserve separate attention:
Tasks that produced seconds but were judged as failures. Some failures occur during generation, when the cost has already been incurred. If your retry policy doesn't distinguish failure types, these tasks get rerun repeatedly, and spending grows exponentially.
Invalid calls caused by insufficient parameter validation. Duration overruns, incompatible material formats, and empty prompts could have been stopped on the client side, yet they fail only after a full round on the server.
There are four control measures:
- Idempotency keys: allow only one valid task per business request, eliminating duplicate billing caused by client resends.
- Failure budget: set a total retry allowance per business line (measured in seconds or attempts); once exceeded, trip the circuit breaker and alert rather than retrying indefinitely.
- Pre-validation: validate duration ranges, material formats and sizes, and required fields on the client side before submission, keeping obviously invalid requests outside of billing.
- Call logs: record the request parameters, task identifiers, final status, and produced seconds of each submission, and aggregate them into a daily cost report. Without logs, you can't pinpoint which types of requests are burning money.
A practical approach is to treat "seconds of successful output ÷ total seconds consumed" as a health metric and track it continuously. When this ratio declines, it means retries or waste are increasing.
Typical deployment scenarios and best-practice checklist
Scenario comparison
- text-to-video: marketing concept draft videos, storyboard previews, exploration of short social media content. Suitable for teams starting from zero source material.
- image-to-video: animating e-commerce product images, turning posters into short videos, bringing character designs to life. Suitable for brands that already have visual assets.
- video-to-video: stylized remastering of existing material, refreshing old footage, batch rewriting of multiple versions. Suitable for content teams with video material libraries.
Pre-launch self-check checklist
- A cost model has been built based on output seconds, with the failure budget included
- The duration cap per request is enforced at the business layer
- The invocation pipeline is designed as an async task, including polling backoff and timeout caps
- Submission requests carry idempotency keys, so resends don't create duplicate tasks
- Failures are handled by classifying them as retryable and non-retryable
- Result videos are immediately transferred to your own storage, not reliant on temporary links
- Every call has logs, allowing daily aggregation of output seconds and cost
- Parameter names and value ranges have been confirmed against the official documentation, with no speculative fields
Deployment pace
First run the end-to-end pipeline with the shortest duration and a single path, confirming that prompts and parameters can reliably produce clips; then gradually open up duration and resolution; and only then integrate batch production. This order ensures that each expansion is built on already-validated results.
In terms of capability boundaries, the value of flux-3-video lies in covering three input modalities with one model; from an engineering perspective, the real barrier is asynchronous orchestration and cost discipline. To get the pipeline working first, you can start by running a short-duration task from the HiAPI.ai model page.
Related articles
View all articles →-

Guide
Getting Started with seedream-5.0-pro/image-to-image: Capabilities, Pricing, and Integration Essentials
Capability boundaries, billing model, and engineering integration practices for ByteDance's image editing model
-

Guide
seedream-5.0-pro Text-to-Image Getting Started Guide: Capability Boundaries, API Integration, and Cost Control
A hands-on developer perspective: from key parameters to a cost estimate of $0.05 per image
-

Guide
Hailuo 2.3 Fast Image-to-Video Getting Started Guide: Capability Boundaries, Pricing, and Integration Practices
MiniMax image-to-video model selection and integration key points for developers