
Tutorial
flux-3-video Applications in Practice: 5 High-Value Use Cases and Deployment Essentials
From three input modes to 5 real-world scenarios, with a cost and troubleshooting checklist
Why distinguish the three video generation modes at the selection stage
A video model may look like nothing more than "input a description, output a video," but flux-3-video offers three input modes at once: text-to-video, image-to-video, and video-to-video. These three paths differ greatly in product semantics, material requirements, failure modes, and cost structure. If you fail to distinguish them at the selection stage, the most common consequence is: the API is connected and the demo runs fine, but when you actually integrate it into the business, you discover the material pipeline doesn't match and have to start over.
The input and output contracts of the three modes
- text-to-video: The input is a pure text prompt, and the output is a video freely generated by the model. It requires no pre-existing material and has a high creative ceiling but the lowest controllability—calling it multiple times with the same prompt will naturally diverge in visual content. Suitable for scenarios where "no material is available" or "a large number of non-repeating visuals are needed."
- image-to-video: The input is one (or a set of) reference images plus a text prompt, and the output is a video anchored visually to that image. Its controllability comes from the image itself—the main subject, composition, and color tone are locked by the image, and the model is responsible for adding motion. Suitable for teams that already have a stock image library and need to maintain brand visual consistency.
- video-to-video: The input is a source video plus a transformation instruction, and the output preserves the temporal structure and motion rhythm of the source video while rewriting the style or specifications. It is the most "engineered" path because the duration structure of input and output is predictable, making batch processing and acceptance checks easier.
Use "does the material exist?" as the first branching decision
In practice, the fastest branching decision is not about technical capability but about asking one question: what material does the business currently have on hand?
If there is no material at all, only copy and creative direction, starting with text-to-video has the lowest cost; if there are static assets such as product images, posters, or illustrations, image-to-video can significantly increase the reuse rate of these assets; if there is already finished footage and you need multi-channel adaptation or style unification, that is where video-to-video shines. Conversely, if a team only has text but forces video-to-video, or only has finished footage but hopes to replicate existing content with text-to-video, they will end up reworking repeatedly during acceptance.
The trade-off between controllability and iteration cost
The iteration costs of the three are not the same. Every adjustment to text-to-video requires changing the prompt and regenerating, so trial-and-error cost is high but the per-call barrier is low; the adjustment lever for image-to-video is the image, and swapping the image is often more effective than changing the wording; video-to-video adjustments are the most localized and usually only require specifying what to change. When selecting, factoring in "how many rounds we expect to revise one piece of material" brings you closer to the real deployment cost than simply comparing output quality.
Once these three boundaries are clear, the following five scenarios can each fall into place.
Scenario 1: Batch production of product and marketing short videos
This is the scenario with the most direct return on investment for video models: batch-converting product materials and marketing copy into short videos for feed advertising, product detail pages, and social media distribution. The traditional process requires shooting, editing, and music scoring, whereas model generation compresses this pipeline into "material + prompt → finished video."
Which mode to use
Teams with product images should prioritize image-to-video: using the product hero image as an anchor, let the frame produce slow orbiting, flowing light and shadow, or scene changes, while the product subject does not deform and brand visuals remain consistent. For brand-new or concept products with no images at all, use text-to-video to first generate a conceptual mood video as a pre-shoot proposal presentation.
Engineering essentials for batching
The essence of batching is not "looping calls" but parameterizing the variable parts. It is recommended to split a product video into three layers:
- Immutable layer: brand color tone, aspect ratio, and prohibited elements, written into a unified prompt prefix.
- Variable layer: product name, selling points, and scene descriptions, injected row by row from the product data table.
- Post-processing layer: opening and closing segments, subtitles, and watermarks, which should be overlaid after generation to avoid repeatedly consuming duration on every generation.
Use a queue to drive batch tasks; a single task failure should not block the whole batch. Save the prompt, input material identifier, and output address for each record so you can trace which material version performed better.
Acceptance criteria
Acceptance for batch production must be quantifiable: whether the product subject is recognizable, whether there is obvious deformation, whether unwanted garbled text appears in the frame, and whether the duration meets the publishing platform's limits. It is recommended to run a small batch with manual spot checks first to confirm the prompt template is stable before scaling up volume.
Scenario 2: Animating static assets with image-to-video
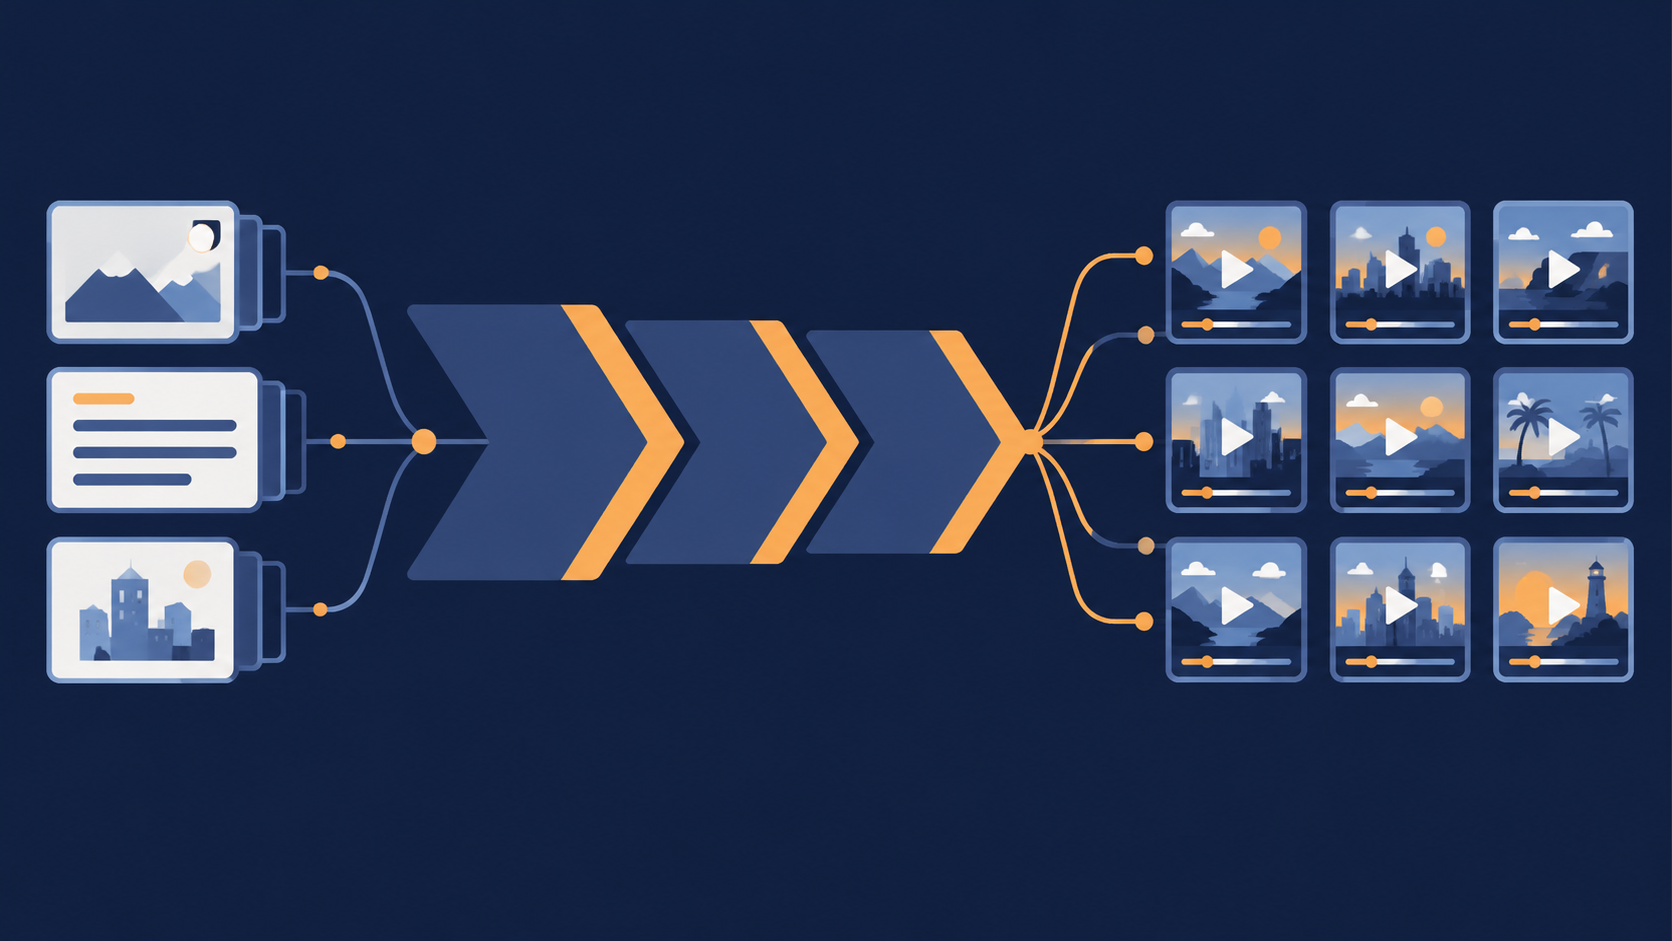
Many teams do not have video materials but have accumulated a large number of static assets: product images, illustrations, posters, course covers, and campaign key visuals. These assets are at a natural disadvantage in feeds—static images are often simply scrolled past in auto-playing feeds. Animating them is the type of use with the smallest investment and fastest results.
Where the value lies
The core benefit of animation is not "looking better" but increasing dwell time and clicks in feeds. Short videos derived from the same hero image can independently participate in A/B testing as an ad creative, thereby adding a new testing dimension to the same asset. For asset-heavy businesses (e-commerce, content, education), this amounts to releasing the residual value of historical assets.
Implementation notes
- Keep motion restrained. The most common failure in image-to-video is excessive motion causing subject distortion. Prompts should explicitly include qualifiers such as "slight" and "slow," and describe the source of motion (camera push, light and shadow changes, floating local elements) rather than vaguely asking it to "move."
- The first frame is the cover. What is seen first in a feed is the video's first frame, so when selecting images, screen by "does this image work as a cover on its own" rather than choosing an image that only looks good once animated.
- Leave whitespace in composition. If the original image is a full composition, motion may crop edge information; prioritize materials with a centered subject and margins around it.
How to evaluate returns
It is recommended to evaluate along two dimensions: "asset reuse rate" and "testing cost per asset." What proportion of a batch of stock images is suitable for animation, and how much lower is the generation cost per animated asset compared with reshooting? Once these two numbers hold up, asset-heavy teams usually turn this into a routine asset production workflow rather than a one-off experiment.
Scenario 3: Style and specification adaptation of video-to-video materials
When a team already has a strong video asset, the real problem often becomes: how to make it fit every channel. Changing landscape to portrait, cutting long videos into short ones, unifying visual style, and creating localized versions for different regions—these tasks traditionally require editors to process them one by one, and video-to-video turns this step into orchestrated batch processing.
Typical uses
- One master for multiple channels: Use one main video as the source and batch-produce versions suited to different ad placements, preserving the original's rhythm and narrative structure while changing only the aspect ratio and compositional focal point.
- Style unification: Bring historical materials with inconsistent tone into the current brand style, reducing visual fragmentation in the asset library.
- Specification adaptation: Uniformly rewrite to meet different platforms' requirements for duration, aspect ratio, and resolution.
Constraints must be confirmed in advance
video-to-video output is most constrained by the source video: the source's duration, motion complexity, and image quality all propagate to the output. Therefore, before launch you must first clarify the business requirements for the maximum output duration and aspect ratio, then decide how to cut the source. Especially when converting long videos to short ones, it is recommended to do a rough cut on the source side first rather than feeding the entire long video to the model and letting it decide—the model does not understand your narrative priorities.
Batch processing design
Abstract one conversion as a triple of "source video ID + target specification + style instruction" and record it in a task table. One row per target channel, with generated results named and archived by channel. In this way, adding a channel is just adding a configuration row rather than going through the editing process again. At the same time, keep the mapping between source and output so that when a channel's feedback is poor, you can identify which type of rewrite caused the problem.
Scenario 4: Rapid production of product demos and feature teasers
SaaS and tool teams have a long-standing pain point: every release requires a demo video, but screen recording material often has to wait for the product to stabilize, and the script has to wait for marketing confirmation, so the release is ultimately held up by the video. Video models can compress the first version of a "demo video" from days to hours.
Recommended workflow
- Split the script into shots: Break a product demo into several shots of around 5 seconds, each corresponding to one feature or one usage scenario. Shot-based structuring is key here because the model controls content in short shots noticeably better than in long narratives.
- Mix text and images for output: Use text-to-video for abstract features (such as data flows and collaboration processes) to generate conceptual visuals; use image-to-video for real interfaces and product forms, anchored to screenshots or design mockups, to ensure the externally presented product image is not distorted.
- Assemble and voice over: Splice the generated clips in post-production and add narration, subtitles, and transitions. Do not pursue "one continuous take" at the generation stage—that is both hard to control and expensive.
Manual review is indispensable
The top priority of a product demo video is to not mislead users. Model-generated visuals may contain nonexistent buttons, incorrect interface layouts, or fabricated features. Therefore, every generated clip must undergo manual review by the product side to confirm that the elements appearing in the frame exist in the real product or are clearly marked as illustrative. It is recommended to make "frame element verification" a fixed checklist item rather than something glanced at during editing.
Applicable boundaries
This path is suitable for feature teasers, concept demos, release countdown assets, and internal briefing videos; it is not suitable for tutorials that require precise reproduction of operation steps. Tutorial content should still be based primarily on real screen recordings, with model generation used only for packaging and transitions.
Scenario 5: Dynamic assets and creative experiments on content platforms
The needs of content and growth teams differ from the previous four categories: they do not lack one good asset; they lack a large number of testable directions. The per-second billing characteristic of video models fits exactly this rhythm of small-batch trial and error—short clips, multiple directions, rapid elimination.
Make experiments a closed loop
A sustainable creative experiment workflow usually goes like this: start from a topic or trending event, generate several short clips at once, each representing a different visual direction or narrative angle; after publishing, look at early data performance, keep directions with promise for further iteration, and abandon the rest. The key is that each round of experiments should have a small batch size and each clip should be short, so that the cost of a single round of trial and error is low enough to repeat at high frequency.
Three engineering suggestions
- Fix variables: Change only one dimension per experiment round (visual style, opening approach, or rhythm), otherwise the data cannot be attributed.
- Record prompts: Archive the prompt and parameters for every clip, so good results can be reproduced and poor results can be ruled out.
- Prioritize short clips: Use short durations during the experiment phase, and only lengthen and scale up the winning direction after it is validated.
Suitable and unsuitable uses
Suitable for opening hooks, mood clips, topic visuals, and cover animations; not suitable for long content that requires coherent narrative. Positioning the model as a "creative probe" rather than a "content production line" will make the team's expectations and acceptance criteria healthier.
Cost estimation and calling strategy under per-second billing
Video models are billed by output seconds, which means cost is directly tied to "duration × number of clips." For specific unit prices, refer to the site's pricing panel; here we only discuss conversion methods and control measures.
Convert billing into per-asset business cost
The conversion formula is simple: cost per clip = output seconds × price per second. On top of that, multiply by business-side multipliers—one ad creative usually needs multiple versions for A/B testing, so the actual cost is "cost per clip × number of versions × number of iteration rounds." What most teams underestimate is precisely the latter two multipliers: repeated generation before the effect is finalized is often much more expensive than the few final delivered clips.
Four levers for cost control
- Compress duration: First validate the direction with short clips, then generate the full duration after finalizing. This is the most effective way to save money because cost is linear with duration.
- Control iteration: Polish the prompt template on a small batch until it is stable before scaling up. Batch generation with an unstable template is almost pure waste.
- Phase the work: Allow divergence during exploration, and fix parameters during production. Use different batch sizes and acceptance criteria for the two phases.
- Calculate concurrency: The concurrency limit for batch tasks should be set together with a budget cap; set a cost threshold for each batch, pause and manually confirm when exceeded, to prevent scripts from running wild.
Formulate a calling strategy
It is recommended to make both "duration" and "number of clips" configurable in the business code rather than hard-coded. Then, when the advertising budget tightens, you can reduce the cost per batch by adjusting configuration without changing code. At the same time, log the duration and number of clips for each call to form an auditable cost ledger for allocation by project or channel.
Integration troubleshooting and pre-launch checklist
Failures in video APIs are often not "errors" but "slowness" and "instability." Going through the following points before launch can block most online issues.
Common failure modes
- Timeouts: Video generation takes significantly longer than text and images, and default client timeouts are easily insufficient. Set the request timeout to a magnitude that matches the video duration, and switch to an asynchronous task + polling model rather than synchronous waiting.
- Duplicate submissions: Automatic retries under network jitter can cause duplicate generation, directly amplifying costs. Generate an idempotency key for each task, and have the server deduplicate by idempotency key.
- Non-compliant or unusable content: Output may contain subject deformation, garbled text, or visuals that do not meet business requirements. Such issues do not throw exceptions and can only be caught in the acceptance stage.
- Input material issues: Low-resolution or overfull composition of reference images in image-to-video, and insufficient bitrate of source videos in video-to-video, will noticeably degrade output quality. The material side should validate before entering the queue.
Timeout, retry, and fallback design
Retries must have boundaries: retry only clear network errors and 5xx, with a maximum number and backoff interval; do not automatically retry content-type failures—escalate to manual handling. Fallback plans must be thought through in advance—when generation fails, do you fall back to static assets, fall back to the last usable version, or simply skip that task? The answer differs by business line, but all should be determined at the design stage.
Pre-launch checklist
- Is the asynchronous task chain complete: submission, polling, timeout, idempotency, result persistence.
- Are duration and number of clips configurable, and is a per-batch cost threshold set.
- Have input materials been validated for resolution and format.
- Is there a manual or automatic acceptance step for output, and are acceptance criteria quantified.
- Do logs record prompts, parameters, duration, and task status, and can they be traced back.
- Has the fallback path been rehearsed rather than just written in documentation.
Treat this checklist as a release gate, and the launch rhythm of video features will be much more stable than fixing while running. To further understand the capability boundaries of flux-3-video, you can first run a minimal pipeline on the model page, then expand layer by layer according to the scenarios above.
Related articles
View all articles →-

Tutorial
How to Call hailuo-2.3-fast/image-to-video via the HiAPI API: curl and Python
A first working request for the fast, low-cost image-to-video tier — from model ID to downloaded MP4
9 min read -

Tutorial
How to Use hailuo-2.3/text-to-video via the HiAPI API: curl, Python, and a Working Request
11 min read -

Tutorial
Kandinsky 6.0 Pro Text-to-Video on HiAPI: curl and Python Tutorial
A request-first walkthrough: build the prompt-to-clip call, submit it, poll for completion, and download the result
11 min read