
Tutorial
seedance-2.0-fast Practical Guide: 5 High-Value Application Scenarios and Integration Key Points
From text-to-video and image-to-video to reference-to-video, how developers can integrate this video model into real business operations
Why Use seedance-2.0-fast for Video Scenario Validation
The hardest step in deploying video capabilities is often not "can it generate" but "is it worth doing first." seedance-2.0-fast is provided by ByteDance, outputs video, and supports three input methods: text-to-video, image-to-video, and reference-to-video. This means teams can use the same model to cover three completely different starting points for assets: pure text ideas, existing key visuals, and established styles or characters.
For engineering teams, its value lies in "controllable validation costs." The model is billed by output seconds, with costs growing linearly with duration—short clips are cheap, long videos are expensive. This makes "shoot a small sample first, then scale up production" a natural engineering rhythm rather than a hard constraint. You can first use a few seconds of sample footage to confirm style direction and stability, then decide whether to enter batch production.
Another often-overlooked point is the capability boundary. It outputs video and does not handle post-production tasks like editing, scoring, or subtitle compositing; the three input methods also cannot be mixed into a composite request of "text + reference image + style anchor." Writing these boundaries into the plan before integration is much cheaper than troubleshooting afterward.
It is suitable as the first experimental model for business videoization: broad capability coverage, clear billing basis (by output seconds), and unified integration. After the business runs smoothly and requirements diverge, consider horizontally combining other models.
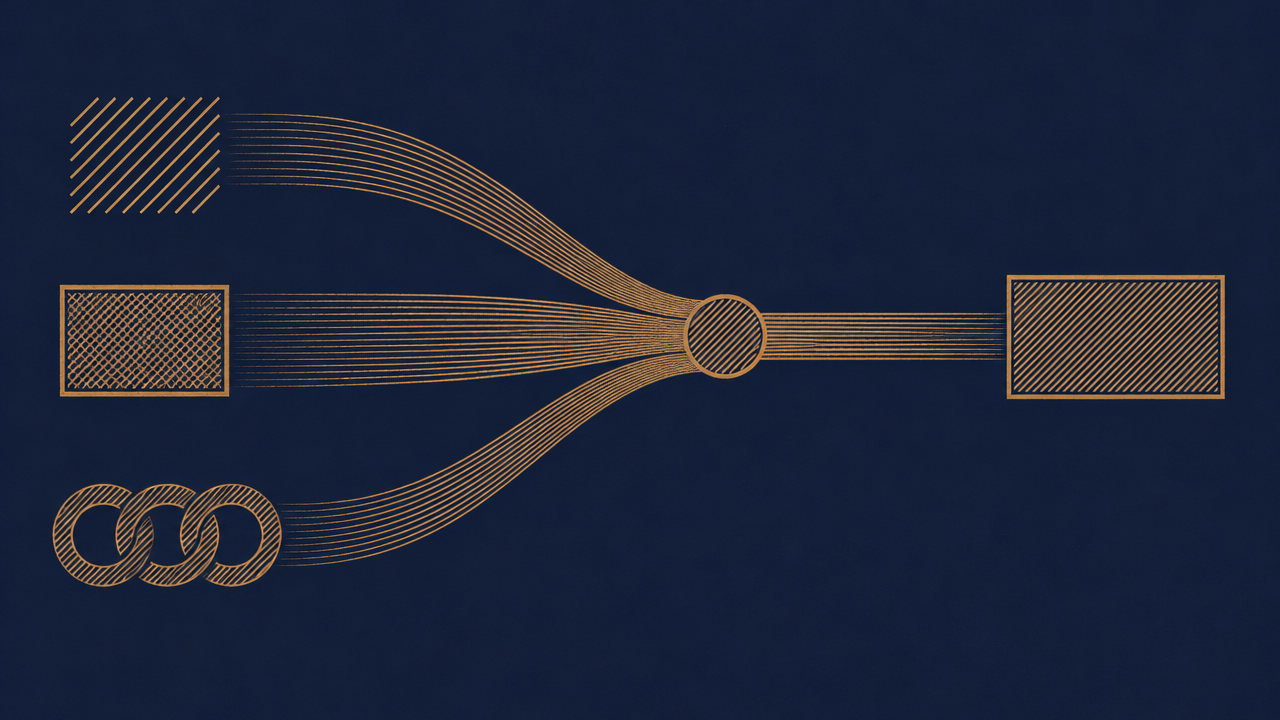
How to Choose Among the Three Invocation Methods: Text-to-Video, Image-to-Video, and Reference-to-Video
Choosing an invocation method only requires answering two questions: Do you have existing assets? How high is the consistency requirement?
No Assets, Starting from Scratch: text-to-video
Generation driven purely by text descriptions. Suitable for creative divergence, concept exploration, and batch production of multiple directional versions. The cost is the lowest controllability—calling the same prompt multiple times produces different results; don't expect frame-by-frame reproducibility.
Existing Key Visual, Needing Visual Continuity: image-to-video
Uses an existing image as the visual starting point and extends it into dynamic content. Suitable for materials with established visuals such as brand KVs, product images, and posters. The key constraint is: the input image essentially determines composition and color tone; the prompt's role is to describe "how it moves," not "what it looks like."
Needing Style or Character Consistency: reference-to-video
Uses reference assets to anchor style or character traits, then generates new content. Suitable for serialized production—the same character appearing in different scenes, the same visual language covering multiple videos. The higher the consistency requirement, the more critical the quality and representativeness of the reference assets.
Decision Order
First ask "do you have usable images": if not, use text-to-video; if yes and visual continuity is required, use image-to-video; if yes and cross-video style consistency is required, use reference-to-video. Then ask "is this piece for exploration or production": the exploration phase tolerates variation, the production phase prioritizes consistency, and the corresponding invocation methods often differ.
A practical fallback principle: when unsure, first use text-to-video to establish direction, then switch to image-to-video or reference-to-video for the official version. This way, the failure cost at each step stays at the short-sample level.
Scenario 1: Batch Short Video Generation for Marketing Assets
This is the most direct use case: using text-to-video to batch-produce multi-version advertising assets covering different selling points, different emotions, and different openings.
Process Design
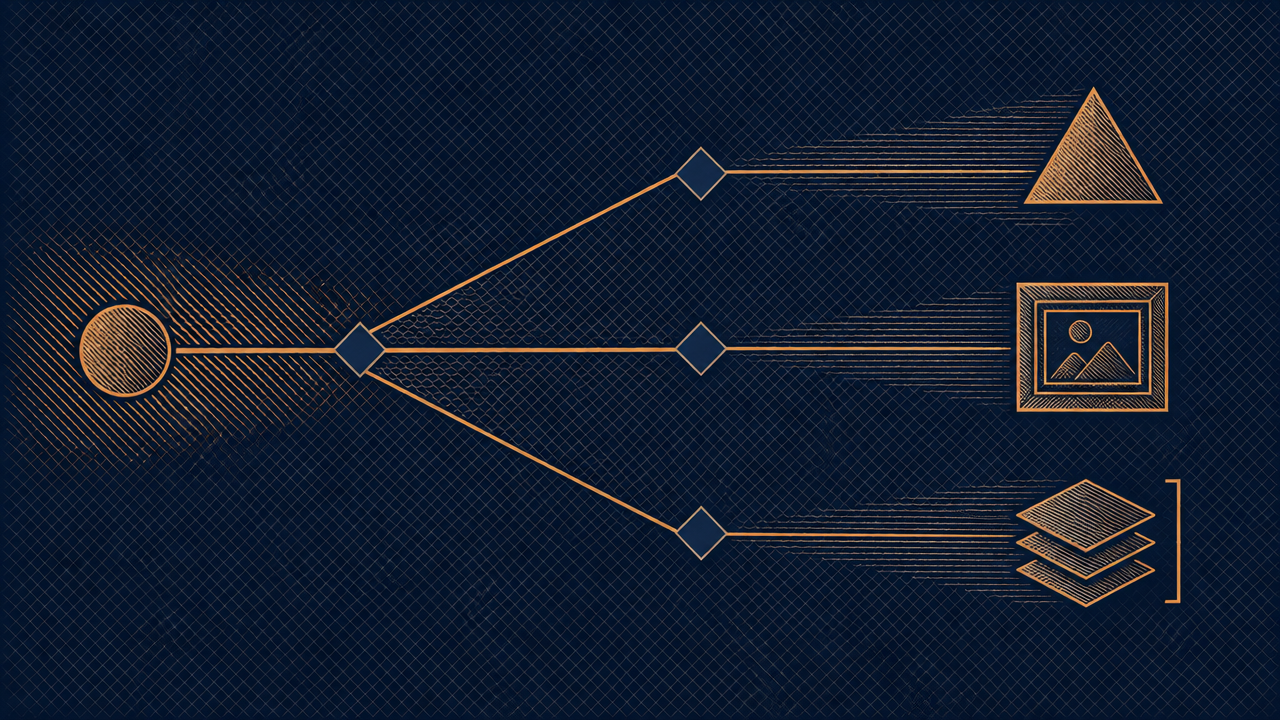
Break "one video" into a three-layer structure: selling-point script (manual) → prompt template (semi-automated) → batch invocation (programmatic). The prompt template fixes camera language, rhythm, and style descriptions, with variables reserved only for selling points and scenes. This makes batch-generated outputs comparable and allows the asset team to quickly pick usable versions.
Three Notes on Scaling
First, take small batch steps. Run a batch of short samples first to see whether the overall style holds, then scale up the batch. Launching a large number of long videos all at once multiplies failure costs with duration.
Second, keep metadata for every output. Prompt version, invocation method, duration, and generation time must all be recorded; otherwise, hundreds of assets piled together will make manual screening a disaster.
Third, accept randomness and turn it into an option. Running the same prompt multiple times is essentially "machine divergence, human convergence"—this is exactly the value of batch text-to-video; don't try to eliminate it.
Scenario 2: Extending Dynamic Content from Existing Key Visuals
When the brand already has established image assets, image-to-video is the most cost-effective step: turning static KVs, product images, and posters into deliverable dynamic assets, with the visual tone locked by the input image and no need to re-align styles.
Implementation Key Points
The quality of the input image directly determines the output ceiling. Prioritize images with complete composition, clear subjects, and reasonable negative space; for overly cropped or information-dense images, the model struggles to find reasonable motion space.
Write "motion" in the prompt, not "content." Describing camera push-pull, light and shadow changes, and subtle movements of local elements is more effective than repeatedly describing what is in the frame—the frame is already given by the input image.
Consistency Control
The core risk of this route is "moving incorrectly": subject deformation, frame tearing, and motion directions that violate physical common sense. It is recommended to establish acceptance checklists by asset type and solidify common issues into check items, rather than relying on ad-hoc human visual judgment each time.
Additionally, the same input image paired with different motion descriptions can produce a set of assets from the same source. This is very friendly for marketing scenarios requiring "the same key visual, multiple delivery versions," with costs only tied to duration.
Scenario 3: Serialized Content Production with Consistent Style
The difficulty of serialized content is never the quality of a single piece, but making the 10th piece look like it belongs to the same world as the 1st. reference-to-video is designed for this need: anchor style or character traits with reference assets, then generate new scenes.
Invocation Organization
Build a "reference asset library"—a small number of high-quality, highly representative reference assets covering key angles is more effective than a large number of generic assets. Each generation request points to the same reference set, and style drift will noticeably converge.
The prompt handles "what happens in this piece," while reference assets handle "what it looks like." The responsibilities must be clearly separated; otherwise, stuffing style descriptions into the prompt will pull against the reference assets.
Engineering Recommendations
Write the reference asset version number into the output metadata. Serial content often requires iterating the reference set; without version records, you cannot trace back "which style version was used to generate this video."
At the same time, accept a reality: consistency is a probability issue, not an on/off switch. Reserve a manual screening ratio during batch production, removing or re-running clearly drifted items—this is more realistic than pursuing one-shot perfection.
Scenario 4: Product Feature Demonstrations and Dynamic Explainer Videos
Feature demonstrations and concept explainer videos have high demand, short lifecycles, and frequent updates—exactly where generative models shine, but also the scenario where review costs are most easily underestimated.
Prompt Organization
The core of explainer videos is "information correctness," not "looking good." Prompts should be broken down by shot: first write clearly the one information point each shot must convey, then add camera movement and rhythm. One information point per shot is more likely to yield usable results than cramming three concepts into one long description.
Be especially cautious with content involving interfaces, text, and data: generated video is not good at precisely reproducing UIs and text; such assets are better suited for abstract dynamic illustrations rather than pursuing interface-level fidelity.
Manual Review Step
This is an indispensable step in this scenario. The review focus is not aesthetics but facts: whether concept statements are wrong, whether process order is correct, and whether misleading visual elements were generated. It is recommended to solidify review points into a checklist and have people who understand the business go through it, rather than only having the production side confirm.
Additionally, explainer content updates frequently; treat "regeneration" as a routine action rather than an exception, and manage prompts and assets as reusable assets.
Scenario 5: Rapid Creative Validation in the Prototype Phase
The most expensive thing in the early stage of a requirement is not production, but finishing something after the direction is wrong. The usage in this scenario is very clear: use short-duration samples to rapidly validate creative direction and move the "should we do it" decision to a low-cost stage.
Method
Break the creative into several independently verifiable hypotheses: is the style right, is the rhythm right, is the emotion right. Validate each hypothesis with one short sample rather than making a complete video to carry all hypotheses. Short sample costs decrease linearly with duration—this is exactly where per-second billing is most friendly to the prototype phase.
All three invocation methods can be used here: with no assets, use text-to-video to diverge; with existing visuals, use image-to-video to see dynamic effects; with brand assets, use reference-to-video to confirm style continuity.
Avoiding Post-Production Rework
The key is to capture sample conclusions. Which version was rejected, why it was rejected, and what was changed must all be recorded. Otherwise, after entering formal production, the same discussion will happen again and the validation will have been wasted.
Also clarify the role of samples: they are decision materials, not deliverables. Aligning this with stakeholders in advance can save a lot of back-and-forth about "can the sample be used directly."
Cost and Engineering Deployment: Integration Key Points Under Per-Second Billing
seedance-2.0-fast is billed by output seconds, with costs growing linearly with video duration. This is not just a billing statement—it is a constraint that directly changes solution design.
Duration Control Is Cost Control
Write duration into the budget model during solution design: per-video duration × number of videos × batches = predictable total consumption. Use short durations by default in the prototype phase, and lengthen according to delivery placement requirements in formal production. Don't use long videos for trial and error during validation—that spends the most expensive resources on the most uncertain step.
Treat the Asynchronous Pipeline as a Whole
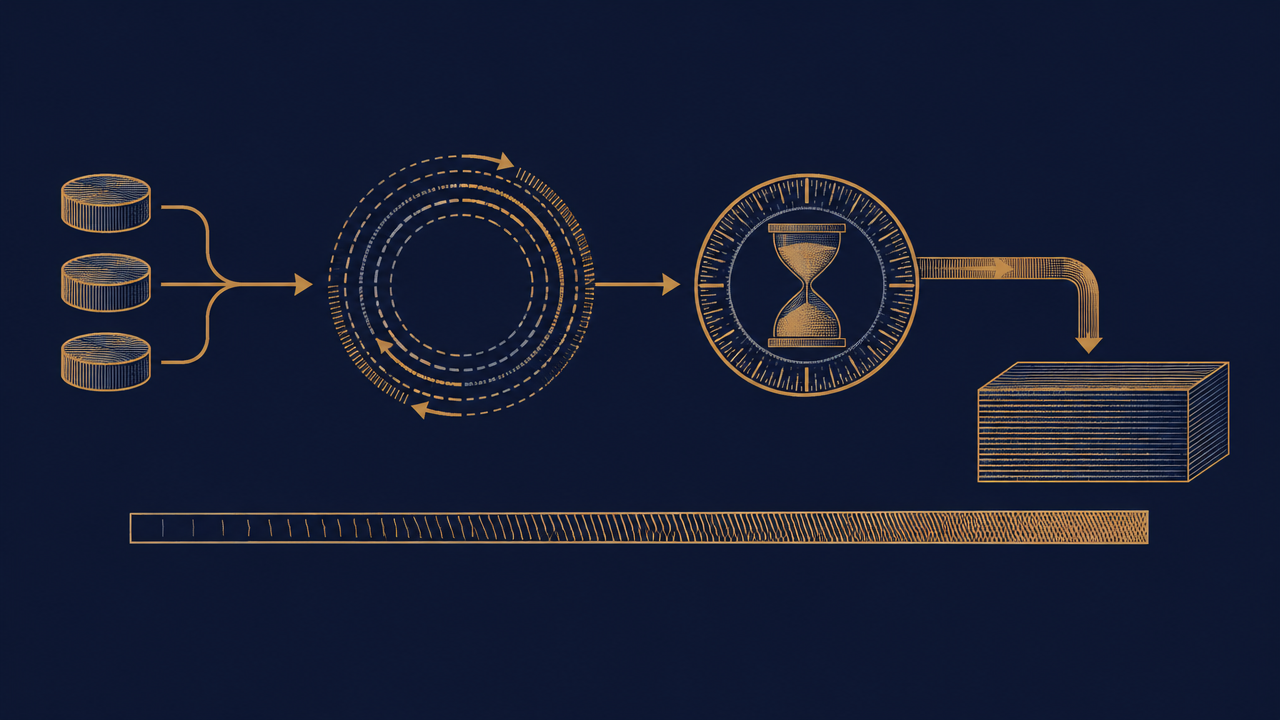
Video generation is a long-running task; integration must be designed as an asynchronous chain rather than a synchronous request. A complete pipeline includes at least four segments:
- Task submission: record request parameters and business identifiers, return a trackable task ID
- Status progression: polling or callback, choose one and implement idempotency to avoid duplicate consumption
- Failure retry: distinguish "retryable" (timeout, temporary errors) from "non-retryable" (invalid parameters, content rejected); retries must have limits and backoff
- Output storage: save videos to disk or transfer to object storage; if generated links are temporary, move them early—don't let the business depend on short-term URLs
Encapsulate as a Unified Internal Service Layer
Wrap video capabilities in an internal service: unified task model, unified callback format, unified output address. Upper-layer businesses depend only on this interface; when horizontally replacing or combining other video models later, changes are confined to the service layer. This is the easiest way to reduce single-model lock-in risk.
The same applies to troubleshooting: first check whether task status transitions are normal, then check parameters and input assets, and only then suspect model performance. The vast majority of "generation failures" actually get stuck in the first two segments.
Make sample validation solid, then let batch production run—only then will the value of this model truly emerge; when you need to check capabilities and billing details, refer directly to the real-time information on the model page within the site.
Related articles
View all articles →-

Tutorial
How to Call hailuo-2.3-fast/image-to-video via the HiAPI API: curl and Python
A first working request for the fast, low-cost image-to-video tier — from model ID to downloaded MP4
9 min read -

Tutorial
How to Use hailuo-2.3/text-to-video via the HiAPI API: curl, Python, and a Working Request
11 min read -

Tutorial
Kandinsky 6.0 Pro Text-to-Video on HiAPI: curl and Python Tutorial
A request-first walkthrough: build the prompt-to-clip call, submit it, poll for completion, and download the result
11 min read