
Alibaba
Wan 2.7 Image
wan2.7-image/text-to-image
An image generation and editing model launched by Alibaba that integrates text-to-image, multi-reference image composition, and instruction-based editing into a single workflow, with support for long-text rendering and brand color control
Try wan2.7-image/text-to-image
Input
Showcases
View all showcasesOutput
image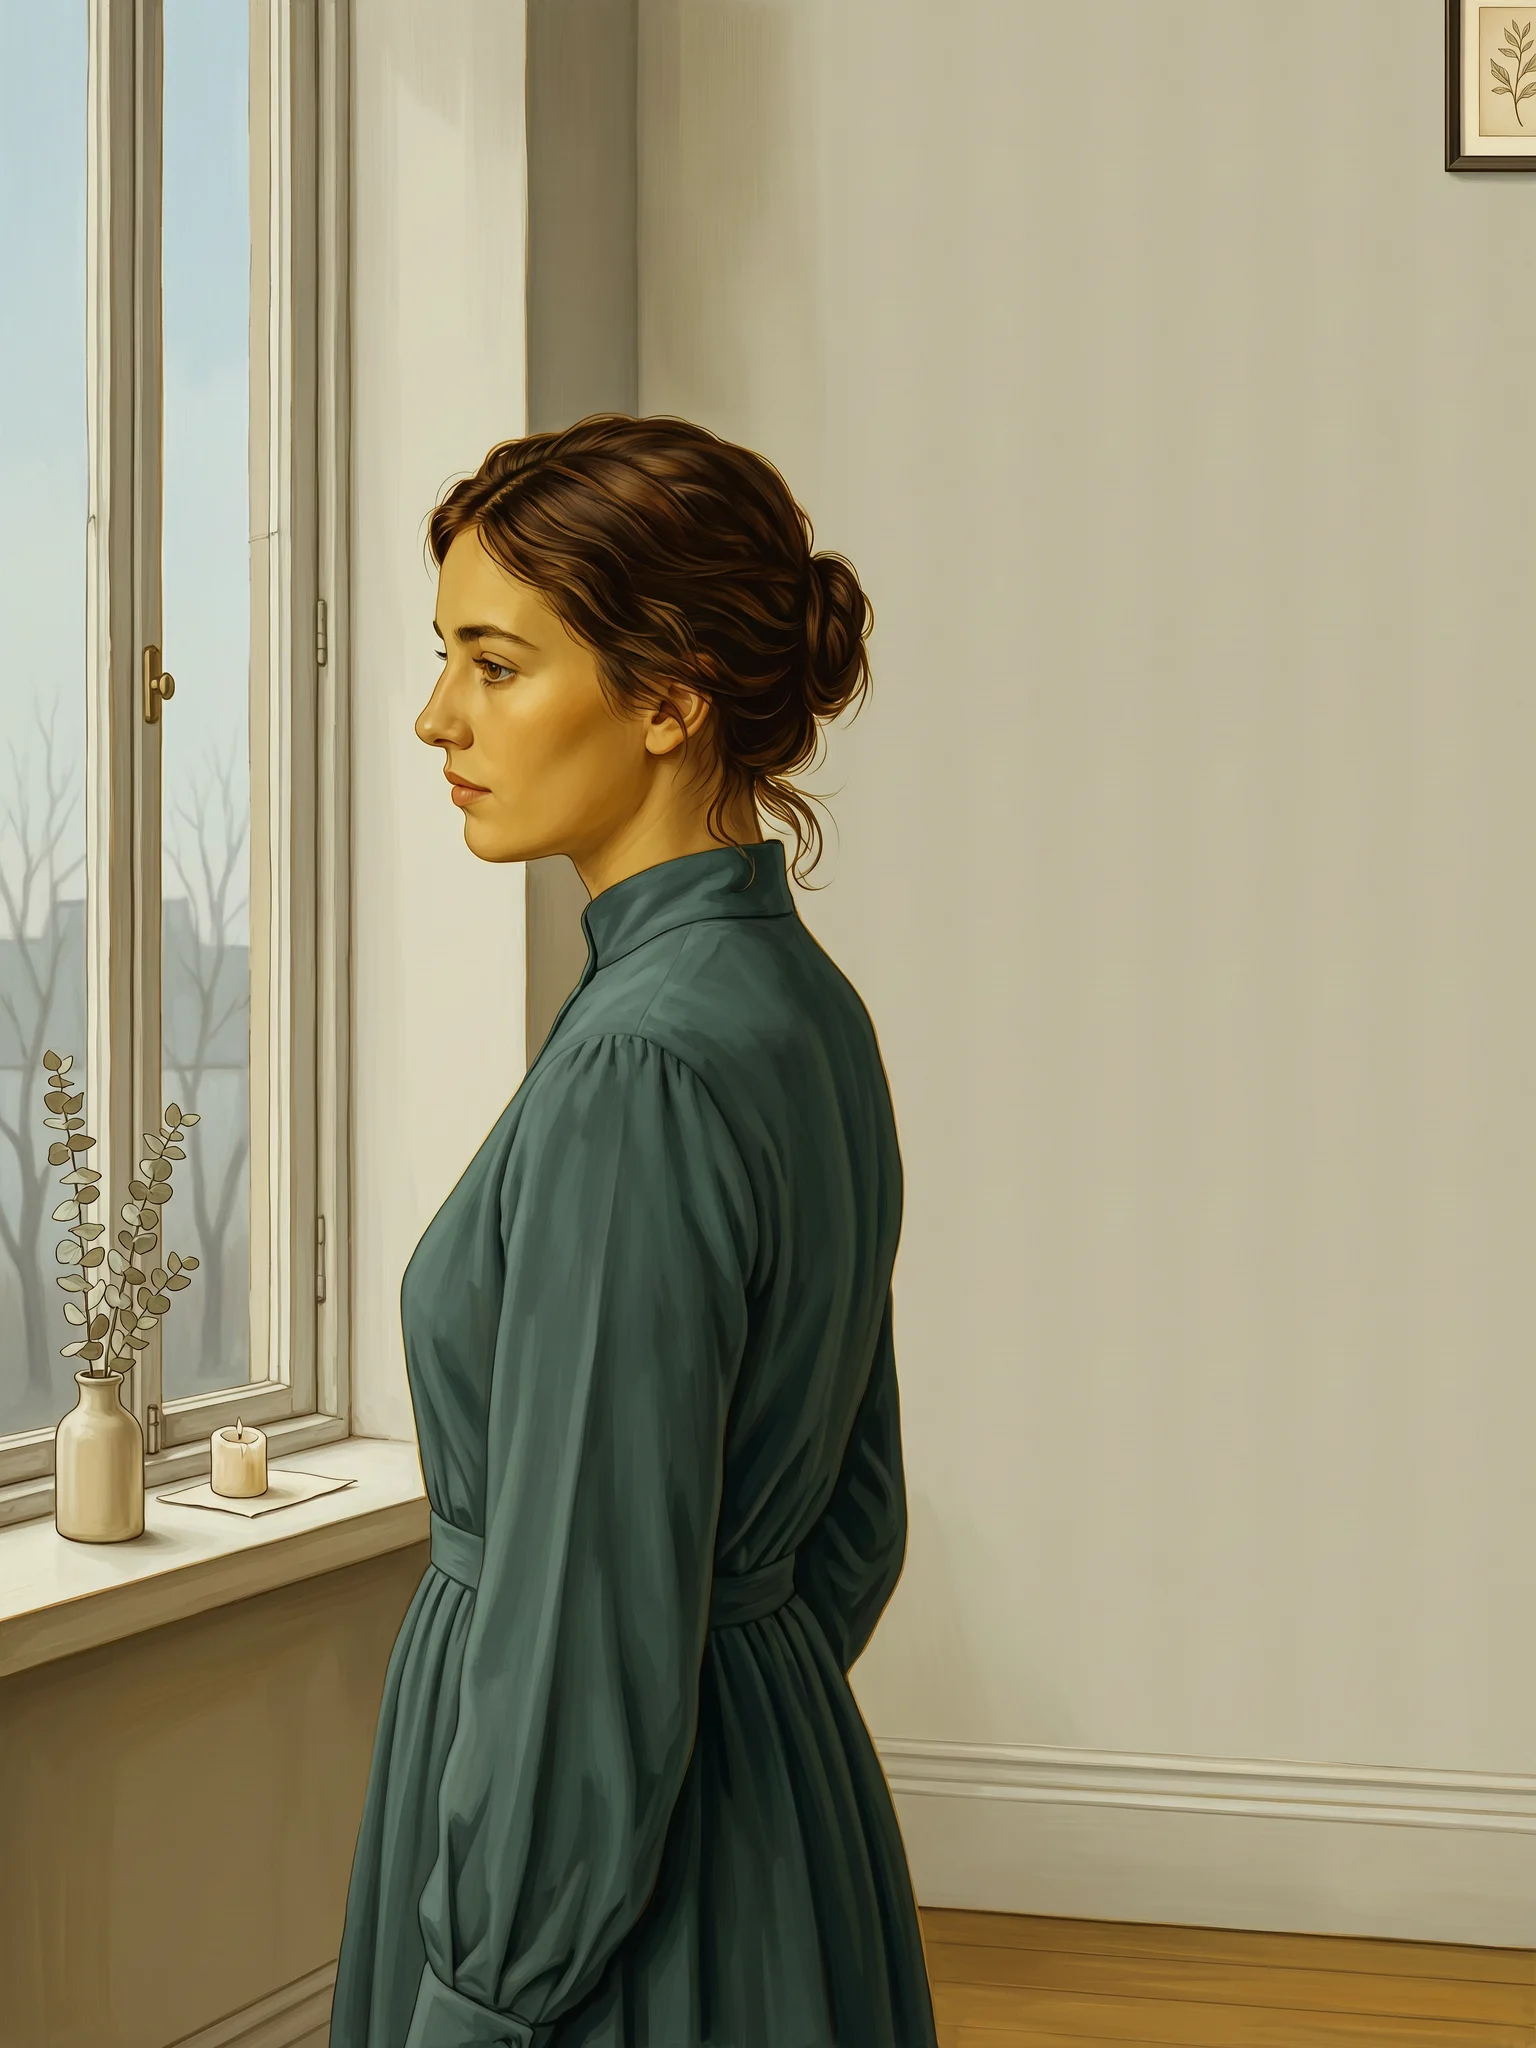
From Realism to Flat: One Prompt Across the Illustration Style Spectrum
Style Illustration · style-spectrum · Character Design
Prompt
A profile portrait of a young woman standing by a tall window, her head turned slightly back toward the viewer, soft daylight entering from the left, against a plain, neutral interior. Unified classical illustration composition, clear contours, medium shot framing, with balanced negative space on the right for placing text. Painterly rendering, visible brushstroke texture, warm ochre and desaturated teal-green tones, rigorous human proportions, soft rim light on the cheek and shoulder, subtle atmospheric depth in the room, 16:9 horizontal composition, rich detail in clothing folds and strands of hair.
Copy the full prompt and adapt it for your own generation.
Tags
Pricing
wan2.7-image/text-to-image per image
| Unit Price | $0.080 |
|---|
Overview
wan2.7-image/text-to-image is the text-to-image route in Alibaba's Wan series, callable on HiAPI.ai through a unified interface. It accepts Chinese and English prompts to generate images, offers optional 1K and 2K resolution tiers and eight aspect ratios, and supports a fixed random seed to reproduce the same result; with enhanced reasoning mode enabled, the model reasons first and then generates the image, trading longer generation time for image quality. It suits developers who need to produce visual assets in batches and have requirements on image specifications and result reproducibility, for production workflows such as poster illustrations, e-commerce scene images, and storyboard sketches.
Key Highlights
- Enhanced reasoning switch, choose quality or speed — thinking_mode is off by default; when enabled, the model reasons first and then generates the image, letting you switch flexibly based on your business requirements for image quality and wait time.
- Fixed seed, reproducible results — passing a seed reproduces the same image, making it easy to control variables and stabilize output when debugging prompts or generating images in batches.
- Aspect ratios from portrait to ultra-wide — besides common ratios such as 1:1, 16:9, and 9:16, it also offers 21:9, 8:1, and 1:8, directly fitting banners, vertical assets, and ultra-wide layouts.
Capabilities
Chinese and English text-to-image: prompts support Chinese and English, up to 5000 characters; developers can describe the image directly in Chinese or reuse English prompts, reducing the cost of cross-language rewriting.
Resolution and frame control: output offers 1K and 2K tiers paired with eight aspect ratios, so a single call yields a finished image matching the placement specifications, reducing post-hoc cropping and scaling.
Reasoning-enhanced generation: enabling thinking_mode improves image quality but increases time; choose by asset importance tier, for example off during drafting and on for final output.
Reproducible results: seed fixes randomness, so the same prompt and parameters repeatedly yield the same result, useful for regression comparison and result validation during batch production.
Use Cases
- Batch generation of campaign illustrations for marketing developers — enter the campaign theme and image description, generate at 16:9 or 1:1, and produce illustrations ready for landing pages and ad placements.
- Product scene images for e-commerce systems — use product selling-point copy as prompts to generate scene images as display assets for product detail pages and listing pages.
- Storyboard and shot sketches for content teams — write prompts shot by shot from the script and fix the seed to produce reproducible storyboard reference images for early creative review.
- Multi-placement asset adaptation — generate the same description at ratios such as 21:9, 3:4, and 1:8 to produce complete asset sets for banner, vertical, and ultra-wide placements.
Limitations and Selection Advice
This route is pure text-to-image: it does not accept reference image input and cannot provide image editing or inpainting. Output resolution is capped at 2K; for 4K images, use the Pro route in the same series. If the task depends on multi-image consistency, instruction-based editing, or click-to-edit, this route cannot cover it. Text rendering in prompts is not guaranteed, and finished images with precise layout and brand color requirements still need manual review. Generation results are heavily influenced by prompt wording, so it is recommended to test with a lower tier and a fixed seed first, then generate in batches.
What's new
View changelog →- New model wan2.7-image-standard image generation model now available
Frequently asked questions
View all FAQs →-
Which unusual ratios does Wan 2.7 Image support?
Alongside common ratios, it supports 21:9, 8:1, and 1:8 for extreme wide or tall output.
-
What does Thinking Mode do?
It adds latency to improve reasoning and composition for complex prompts. Leave it off for fast drafts.
-
How should I choose 1K, 2K, or 4K?
Validate direction at 1K or 2K, then move to 4K for larger final output. Current page pricing is flat per image.
-
Does it accept references?
No. This model ID is text-to-image only.
Create a generation task
https://api.hiapi.ai/v1/tasks Headers
AuthorizationstringRequiredAccount API key. Required on every request. Example: Bearer YOUR_HIAPI_API_KEY. Get your API key
Content-TypestringOptionalThe request body is always parsed as JSON; when sent, only application/json (optionally with charset) is accepted — any other value returns 415. Example: application/json.
Idempotency-KeystringOptionalIdempotency key, up to 255 bytes. Retries with the same key from the same account create the task only once; replays return the original taskId.
On network timeouts or client retries, the same key creates the task only once — no double charges (scope: the API key's account). Use a business-unique identifier as the key (e.g. "order-42"); replays return the original taskId, and keys expire 24 hours after the first request. See the Unified Async API overview for the full scenario matrix.
Body
modelstringRequiredCurrent fixed value: wan2.7-image/text-to-image
routestringOptionalCurrent fixed value: default
inputobjectRequired
Business parameters for wan2.7-image/text-to-image and route default — see the parameter table below.
seedintegerOptionalmin 0max 2147483647Random seed used to reproduce generation results; setting the same seed yields consistent output.
promptstringRequiredminLength 1maxLength 5000Text prompt for image generation, supports both Chinese and English input, determines the content of the generated image.
resolutionstringOptionalDefault: "2K"Output resolution tier; Pro supports up to 4K; default is 2K.
1K2K4Kaspect_ratiostringOptionalDefault: "1:1"Aspect ratio of the output image; default is 1:1.
1:116:94:321:93:49:168:11:8thinking_modebooleanOptionalDefault: falseWhether to enable enhanced reasoning to improve image quality; enabling it increases generation time; default is off (false).
callbackobjectOptional
Terminal-state notification config. When omitted, no callback is delivered — poll the task yourself. See the callback note below.
Provide callback.url when creating a task and HiAPI POSTs to your service once the task reaches a terminal state — no polling needed. The callback payload mirrors the task detail structure; signature verification, delivery retries and idempotency are documented on the Unified Async API overview page.
urlstringRequiredRequired when callback is present. A POST is sent to this URL once the task reaches a terminal state; must be a valid http(s) URL.
whenstringOptionalDefault: "final"Only final is supported today — notified on both success and fail.
finalstoragestringOptionalDefault: "temp"Artifact storage tier: temp (default, retained about 7 days) or persistent (long-term, billed by size). Insufficient balance or exceeding the storage cap silently downgrades to temp; the effective tier is shown in the task detail response.
temppersistentRequest examples
# Submit an async task; returns a taskId immediately (no waiting for generation)
curl -X POST "https://api.hiapi.ai/v1/tasks" \
  -H "Authorization: Bearer $HIAPI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "wan2.7-image/text-to-image",
  "input": {
    "prompt": "…",
    "resolution": "2K",
    "aspect_ratio": "1:1",
    "thinking_mode": false
  }
}'
const res = await fetch("https://api.hiapi.ai/v1/tasks", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.HIAPI_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
model: "wan2.7-image/text-to-image",
input: {
"prompt": "…",
"resolution": "2K",
"aspect_ratio": "1:1",
"thinking_mode": false
}
}),
});
const task = await res.json();
// { code: 200, message: "success", data: { taskId } }import os, requests
res = requests.post(
"https://api.hiapi.ai/v1/tasks",
headers={"Authorization": f"Bearer {os.environ['HIAPI_API_KEY']}"},
json={
"model": "wan2.7-image/text-to-image",
"input": {
"prompt": "…",
"resolution": "2K",
"aspect_ratio": "1:1",
"thinking_mode": False
}
},
)
print(res.json()) # { code, message, data: { taskId } }200 OK
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-01HZTQ8BX2N3GM3YFK4Z9D7VQR"
  }
}
400 Bad Request
{
  "code": 400,
  "message": "invalid request",
  "data": null,
  "error_code": "INVALID_REQUEST"
}
Get task detail
https://api.hiapi.ai/v1/tasks/:id Response fields
taskIdstringRequiredTask ID, always prefixed with tk-hiapi-.
modelstringRequiredResolved full model name. Tasks submitted with the route parameter return base@route (e.g. gpt-image-2/text-to-image@ext); otherwise identical to the name passed at creation.
routestringOptionalPresent only when the task was submitted with an explicit route parameter; echoes the submitted value.
statusstringRequiredTask status.
queued Queued, not started yet.
handling Being processed.
archiving Processing finished, artifacts being prepared.
success Terminal: completed, artifacts available (output returned).
fail Terminal: failed (error returned).
After submission, check status: success and fail are terminal, everything else is non-terminal. Poll every 1–3 seconds until terminal. On success, download artifacts from output[].url and transfer them before expireAt; pass storage: "persistent" at creation time when long-term retention is needed.
creatednumberRequiredTask creation time (Unix seconds).
completednumberRequiredUnix seconds when the task reached a terminal state; fixed to 0 while not terminal.
outputarrayOptional
Present only when status == success. Artifact list — always an array; a single task may return multiple types at once (e.g. video + first_frame).
Array [ object ]
Array items
urlstringRequiredArtifact URL, directly downloadable.
typestringRequiredCurrent possible values: video, image, audio, first_frame, last_frame, thumbnail; more may be added later.
expireAtnumberRequiredUnix seconds until which the artifact remains accessible; download or transfer before it expires.
errorobjectOptional
Present only when status == fail.
codestringRequiredBusiness error code.
messagestringRequiredError description.
Response examples
Success
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-01HZTQ8BX2N3GM3YFK4Z9D7VQR",
    "model": "happyhorse-1-0",
    "status": "success",
    "created": 1777282033,
    "completed": 1777282099,
    "output": [
      {
        "url": "https://cdn.hiapi.ai/tasks/.../video.mp4",
        "type": "video",
        "expireAt": 1777886899
      }
    ]
  }
}
Processing (non-terminal)
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-...",
    "model": "happyhorse-1-0",
    "status": "archiving",
    "created": 1777282033,
    "completed": 0
  }
}
Failed
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-...",
    "model": "happyhorse-1-0",
    "status": "fail",
    "created": 1777282033,
    "completed": 1777282099,
    "error": {
      "code": "TASK_FAILED",
      "message": "task failed"
    }
  }
}Articles
View all articles →Related Models
View all models →Same Type
-
 Grok Imagine Image 2.0 xAI $0.052 /image
-
 Imagen 4 Google $0.030 /image
-
 Nano Banana Google $0.021 /image
-
 Z-Image Alibaba $0.008 /image
-
 Recraft V4.1 Recraft $0.010 /image
-
 Krea 2 Medium Turbo Krea $0.021 /image
-
 FIBO 1.5 Bria $0.058 /image
-
 FLUX.2 Black Forest Labs $0.035 /image
-
 GPT Image 2.5 OpenAI $0.017 /image
-
 Nano Banana Pro Google $0.057 /image
-
 Google Virtual Try-On Google $0.107 /image
-
 Ideogram V4.5 Ideogram $0.011 /image
Same Provider
-
 Wan 2.7 Video Alibaba $0.100 /second
- Z-Image Alibaba $0.008 /image
-
 HappyHorse 1.1 Alibaba $0.160 /second
-
 Wan 3.0 Video Alibaba $0.040 /second
-
 Qwen Image 2.0 Alibaba $0.042 /image
-
 HappyHorse 1.0 Alibaba $0.168 /second
-
 Qwen Image 3.0 Alibaba $0.036 /image
-
 Wan 2.6 Flash Alibaba $0.043 /second
-
 Qwen Image 2.1 Alibaba $0.020 /image
-
 Qwen Audio 3.0 TTS Alibaba $0.030 /1,000 characters