
Tutorial
gpt-5.6-terra Practical Guide: 5 High-Value Text Application Scenarios and Implementation Essentials
From scenario selection to integration essentials, use text models to solve real business problems
Why text models deserve separate selection
In selection discussions, many people treat 'can it understand images' and 'can it generate images' as the default yardsticks for model capability, but for the vast majority of business systems, what actually runs in the production pipeline is still text-in, text-out calls. gpt-5.6-terra is a newly launched OpenAI text model with text output, priced by token. Evaluating it separately, rather than lumping it together with multimodal models, leads to clearer conclusions.
A simpler input-output chain
The call contract for a pure text model is very clean: you give it a piece of text (or a set of messages), and it returns text. There are no extra variables such as image encoding, resolution negotiation, or audio/video duration truncation. This means during debugging you only need to care about two things—the prompt and the context. A short chain means faster problem localization and lower online troubleshooting costs.
Easier to estimate cost structure
The benefit of token-based pricing is that it is calculable. Input length, output length, and retry count are basically enough to bound the cost of a single call. Multimodal calls often also stack media-processing billing dimensions, so there are more branches to consider when estimating. If 90% of the tasks in your business are text work such as classification, extraction, rewriting, and explanation, a text model is the more direct choice.
When to use a pure text model
The criterion can be very simple: if the success criteria of a task can be clearly stated in a piece of text or a JSON, then prioritize a text model. Typical signals include—requirements mention 'extract fields', 'determine intent', 'rewrite tone', 'explain this data'; during acceptance you can write clear reference answers; errors can be fixed by changing the prompt or adding context, rather than by switching modalities.
Conversely, if the task itself depends on visual layout (for example, determining table attribution from the layout of a scanned document) or depends on audio prosody, then a text model is not the primary choice. Hybrid scenarios can also be split: first convert non-text content into text by other means, then hand it to gpt-5.6-terra for processing, so both cost and quality are easier to control.
The second principle of selection is not to bet everything at once. Encapsulate model calls into a replaceable layer, so later, whether rolling out a new model gradually or falling back to an old model, it is only a matter of changing configuration.
Scenario 1: Structured extraction from long documents
Contracts, financial reports, bidding documents, medical examination reports—such long documents have high business value, but manual field entry is extremely time-consuming. Converting unstructured long text into structured JSON is one of the most mature application scenarios for text models.
Implementation approach
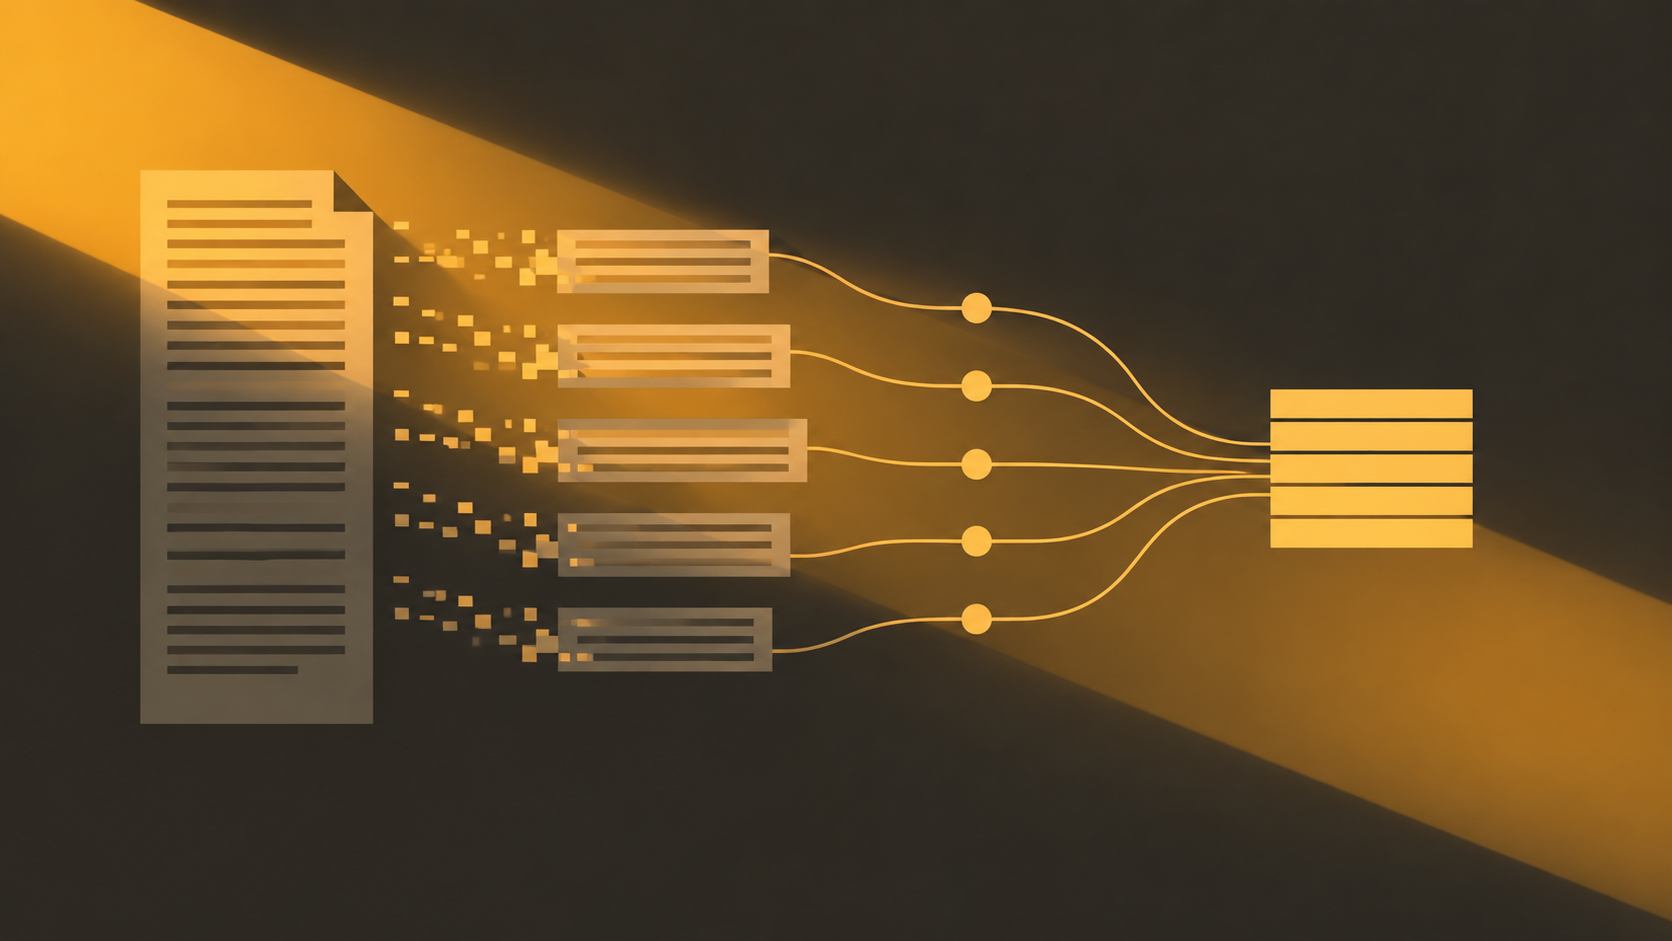
The overall process is a three-stage pattern of 'split—extract—merge'. First, split the long document into chunks by heading hierarchy or fixed length, with each chunk tagged with position information (page number, section path); then have the model output fields according to a predefined schema; finally, perform merging and conflict resolution at the application layer.
The schema must be fixed in advance, and the prompt must specify field types, value ranges, and how missing values are represented. Having the model output 'unknown' rather than inventing a value is much easier than fishing errors out of dirty data afterward.
{
  "party_a": "string | null",
  "effective_date": "YYYY-MM-DD | null",
  "payment_terms": "string | null",
  "termination_clause": "string | null"
}
Evaluation and fault-tolerance essentials
Do not judge extraction quality by 'does it look right'. Prepare an annotated set covering various layouts and edge cases, calculate accuracy field by field, and track key fields (amounts, dates, entity names) separately. For numeric fields, it is recommended to perform another format validation and range validation at the application layer; if a value extracted by the model fails validation, send it back to manual review.
Long documents also have two high-frequency pitfalls: first, cross-chunk fields (for example, the total amount is written in the summary at the end while the clauses are scattered across multiple chunks); second, noise from tables, headers, and footers. The former can be handled with a second merge pass during the merge stage, while the latter is more cost-effective to clean before splitting.
The key to cost control is not to stuff the entire document into the context at once. Processing by chunk and only calling the model on matching chunks can significantly reduce input token consumption.
Scenario 2: Intelligent dispatch of customer service and tickets
The core of ticket dispatch is two judgments: what kind of problem this is (intent), and how urgent it is (priority). Both are text classification tasks, very suitable for text models.
From free classification to controlled classification
The biggest taboo is to let the model freely generate category names, which causes the label system to expand rapidly and become impossible to count. The correct approach is to provide a closed set of intents, let the model choose from them, and require it to also give confidence and the basis for the judgment.
Please classify the following ticket into one of the following intents:
[billing dispute / feature failure / usage inquiry / account security / other]
And give a priority [P0 / P1 / P2] with a reason of no more than 30 characters.
Ticket content: {{ticket_text}}
Having the model output reasons is not for display, but for troubleshooting. When misjudgments in a certain category occur in clusters, reading the reasons can quickly determine whether the label definition is ambiguous or the prompt lacks information.
Confidence fallback strategy
When the model gives low confidence, do not force a dispatch. A more stable approach is to use a fallback path: low-confidence cases enter a manual queue, or only 'major category' dispatch is done without 'subgroup' dispatch, leaving fine-grained judgment to humans. In this way, even if the model's judgment is unstable, tickets will not be dispatched to the wrong team and delay response time.
Online maintenance
The intent system evolves with the business, and classification boundaries also drift. It is recommended to record the results of each manual reassignment, periodically feed them back into the evaluation set, and use them to check whether the prompt and label definitions still hold. Priority judgment requires particular care; for security-related tickets, it is better to set the rule that 'the model only performs initial screening, and humans must review'.
Scenario 3: Batch rewriting and localization in content production
Marketing copy, product descriptions, announcements and notices—such content has high volume, high homogeneity, and yet must maintain stylistic consistency, making it a natural scenario for batch rewriting. Here the text model plays the role of 'one input, multiple outputs'.
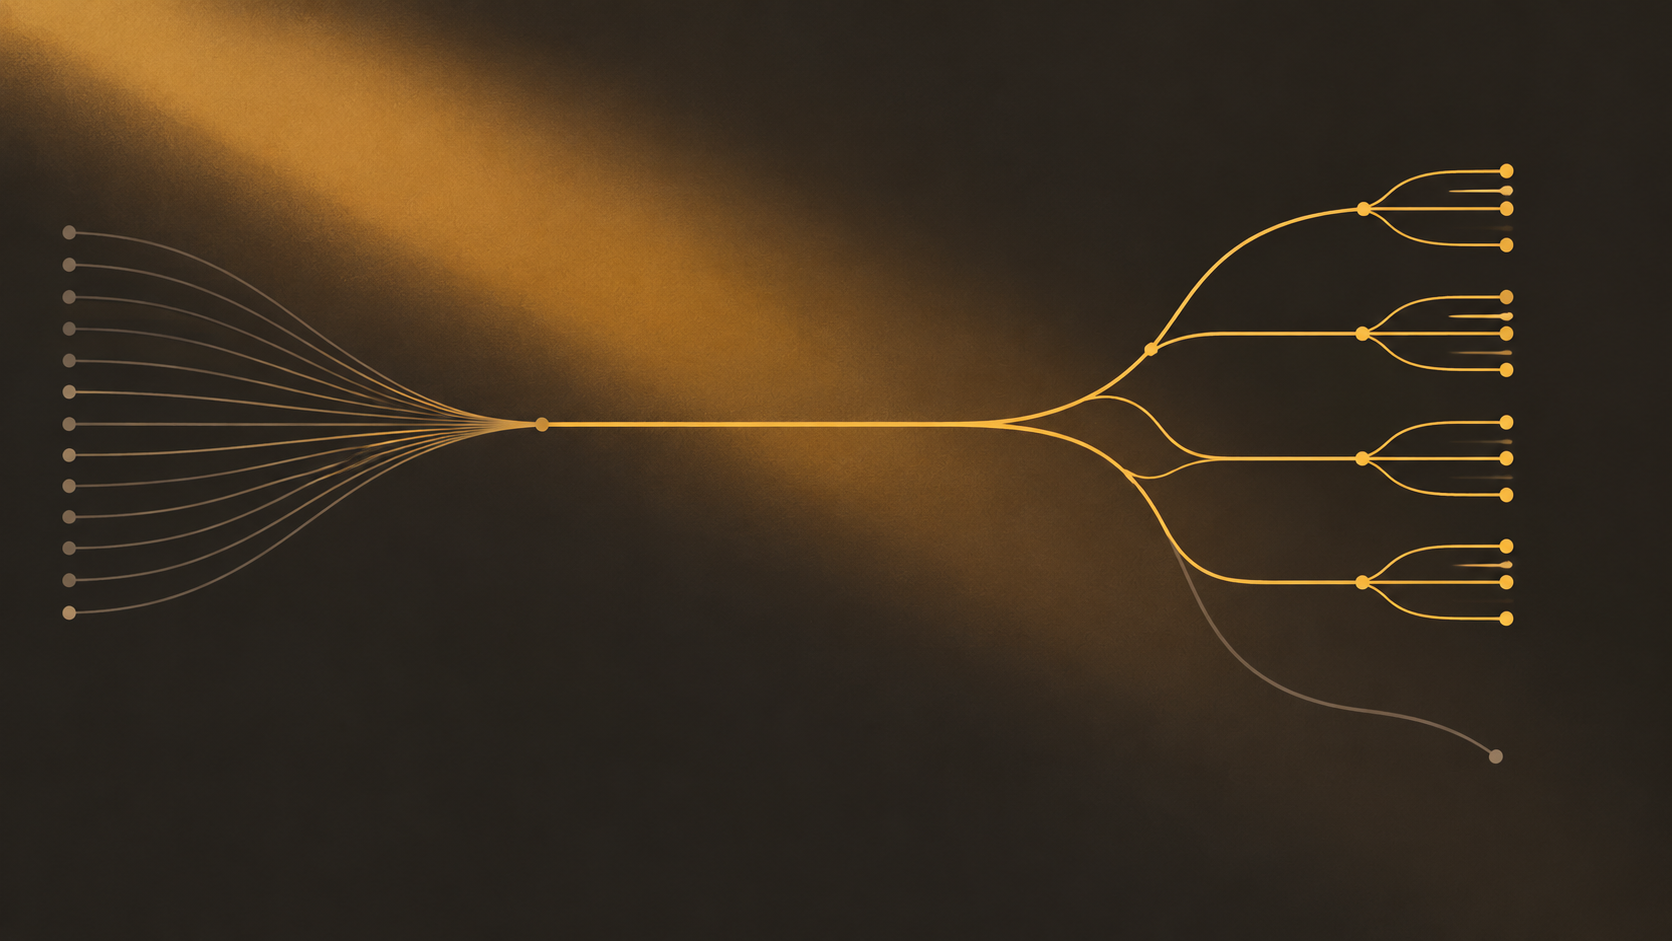
One input, multiple outputs
Pass the source text and style constraints separately. The source text is the content, and the style constraints are parameters: tone (formal/casual), length (compress to within how many characters), audience (new users/existing customers), regional expression habits. In this way, one set of source text can produce multiple versions in parallel, and the differences among versions come from parameters rather than randomness.
Please rewrite a version of the copy based on the following original text:
- Tone: {{tone}}
- Target readers: {{audience}}
- Maximum character count: {{max_chars}}
- Information points that must be retained: {{must_keep}}
Original text: {{source_text}}
The 'information points that must be retained' field is critical. The most common failure in batch rewriting is missing key information (price range, event time, applicable conditions); listing it explicitly gives the model a clear obligation to retain it.
Quality sampling mechanism
Do not expect full manual review. A more realistic approach is tiered sampling: for high-risk content (promotions, compliance statements, external announcements), manually review everything; for low-risk content, sample by proportion. On top of sampling, add another layer of automated checks—whether key information is retained, whether the character count exceeds the limit, whether prohibited words appear—these can all be done with rules at almost zero cost.
Details to handle in localization
Multi-region adaptation is not just about changing wording. Units of measurement, date formats, forms of address, and prohibited metaphors must all be clearly written in the constraints. It is recommended to maintain a style guide for each target region and fix it as part of the prompt, avoiding relying on ad hoc descriptions for every call.
Batch tasks also need to consider idempotency for failure retries: give each rewriting task a stable identifier so that reruns overwrite rather than duplicate writes.
Scenario 4: Assisted troubleshooting of code and logs
When online errors occur, engineers spend a lot of time reading logs and guessing root causes. The value of text models in such tasks is not to replace humans, but to compress a pile of noise into a few ranked hypotheses.
Practical input organization
Throwing tens of megabytes of logs directly at the model is wasteful. First filter by rules, extract a segment of context around the error, then add necessary environment information (service name, version, call chain), and then have the model output a ranking of root-cause hypotheses.
The following is a segment of error logs and environment information for a service:
{{log_snippet}}
Environment: {{env_info}}
Please provide 3 root-cause hypotheses ranked by likelihood, each with verification methods and information that needs to be supplemented.
Requiring the model to give verification methods is far more useful than giving conclusions only. It pushes the output toward executable troubleshooting actions and also helps you judge whether the suggestions are reliable.
Security boundaries
Logs often contain user information, internal paths, and key fragments. Desensitization must be performed before sending, replacing content such as phone numbers, ID numbers, tokens, and intranet addresses. This layer should be completed before the call and cannot rely on the model to ignore it on its own.
In addition, clarify the positioning of model output: it is troubleshooting advice, not a diagnostic conclusion. Any operation involving online changes must be confirmed by an engineer before execution. Separating 'advice' and 'execution' at the system level can avoid many risks.
How to measure effectiveness
The benefits of this type of scenario are hard to measure with accuracy, but process metrics can be used: average localization time, how many manual follow-up questions are needed, and the proportion of suggestions adopted. Comparing these metrics after running for a period is more convincing than subjective feelings.
Scenario 5: Natural language Q&A over structured data
Reports and database results are often hard for business users to read. Converting query results into a natural language explanation can significantly lower the usage threshold. Here the text model is doing 'translation', not 'calculation'.
Key principle: query the data first, then explain
Letting the model calculate numbers itself is a high-incidence area for hallucinations. The correct division of labor is: querying, aggregation, and statistics are all completed in the database or application layer; the model only receives already-computed results and is responsible for organizing language and supplementing contextual explanation.
The following is a set of already-computed statistical data (JSON):
{{query_result}}
Please explain the meaning of this set of data to business users in 3 sentences, and clearly point out the data's time range and statistical scope.
Three means to control hallucinations
First, constrain the input. The model may only answer based on the given results, and the prompt explicitly requires that 'numbers not present in the input must not be introduced'.
Second, require source annotation. Have the answer include the time range, sample size, and statistical dimensions; when business users see this information, they can judge credibility for themselves.
Third, anomaly detection. At the application layer, perform a number extraction pass on the model output; any number that appears in the answer but does not exist in the input should be directly blocked or downgraded to pure template output.
Design for explainability
For the same set of data, different roles care about different points. Tell management about trends, tell operations about anomalies, and tell finance about differences in statistical scope. Fixing these perspectives into several answer templates is more stable than letting the model improvise, and it is also easier to run consistency tests.
Integration and cost control: spend tokens where they matter most
gpt-5.6-terra is priced by token, meaning cost is directly tied to input and output length. Engineering decisions during integration largely determine how much the bill differs for the same business volume.
Context management is the biggest lever
Input tokens are usually the main cost. Several immediately effective practices:
- Pass only necessary fields; do not throw the entire database record in—first project out the columns actually used by the prompt.
- Summarize and compress long conversations, retaining conclusions and constraints while discarding greetings and repetitive content.
- Place fixed instructions and examples in stable positions to facilitate subsequent prefix caching.
- On the output side, use structural constraints and maximum character limits to control length and prevent the model from over-expanding.
Caching and reuse
Many business requests are highly repetitive (the same type of ticket, the same template copy). Caching results at the application layer for requests with 'completely identical input' can directly reduce cost. Note that the cache key must include the prompt version and model identifier; otherwise, once the prompt changes, the cache becomes wrong answers.
Usage monitoring should be split by scenario
Do not look only at total consumption. Record call count, input tokens, output tokens, and failed retry count by scenario and by interface dimension. With these four numbers, you can determine where the cost increase comes from: is traffic up, or has the prompt for a certain scenario quietly become longer?
Retries are also a hidden cost. Set reasonable timeouts and retry limits, and do not retry clear input errors, to avoid a batch of unnecessary consumption.
Unified integration layer
Encapsulate model calls into an internal interface whose parameters are the prompt template, variables, and output constraints, and which returns structured results and usage information. Upper-layer business only depends on this interface, not directly on any model name. In this way, switching models, rolling out new versions, and routing by scenario all require changing only one configuration.
Validation and iteration: use evaluation sets to decide whether to scale up
Whether a model can be used is most error-prone when judged by feel. Preparing a small but refined evaluation set before launch is the only way to pull decisions from subjectivity back to data.
How to build an evaluation set
You do not need thousands of entries. One hundred to three hundred samples per scenario covering typical situations are enough to start; the key is that the distribution must be right: common cases, edge cases, and historical pitfalls all three types must be present. Each sample must have a clear expected output or a judgeable acceptance criterion.
Evaluation metrics depend on the scenario. For extraction, look at field-level accuracy and recall; for dispatch, look at classification accuracy and the proportion of low-confidence cases; for rewriting, look at key-information retention rate and human ratings; for Q&A, look at numerical consistency and human readability scores. The metrics differ, but the principle is the same: repeatable and comparable.
Gradual rollout and A/B testing
Passing evaluation does not mean there are no online problems. First run a small-traffic gradual rollout, compare the new model with the existing solution via A/B testing, and observe both business metrics and cost metrics. Keep other variables unchanged during comparison—same batch of traffic, same prompt structure, with the model as the only difference.
The observation period must be long enough, covering weekdays and peak hours. If key metrics show no significant advantage, do not rush to full rollout; if there is an advantage only in cost but quality is on par, that is also a reasonable reason to switch, but it must be documented clearly.
A closed loop for continuous iteration
After launch, continuously feed manual corrections, user feedback, and online failure cases back into the evaluation set. Every time you change a prompt, switch model versions, or adjust the context strategy, run the evaluation set first, and then decide whether to release.
Models iterate, and businesses drift. The significance of this closed loop is that at any time you can answer 'how is the effect in this scenario right now', rather than waiting for problems to occur before looking back for causes. The true value of new models like gpt-5.6-terra can only be confirmed within a measurable system. Make the integration layer thin and the evaluation thick, and switching costs will naturally be lower.
Related articles
View all articles →-

Tutorial
How to Call hailuo-2.3-fast/image-to-video via the HiAPI API: curl and Python
A first working request for the fast, low-cost image-to-video tier — from model ID to downloaded MP4
9 min read -

Tutorial
How to Use hailuo-2.3/text-to-video via the HiAPI API: curl, Python, and a Working Request
11 min read -

Tutorial
Kandinsky 6.0 Pro Text-to-Video on HiAPI: curl and Python Tutorial
A request-first walkthrough: build the prompt-to-clip call, submit it, poll for completion, and download the result
11 min read