
Tutorial
gpt-6-luna Real-World Use Cases: 5 High-Value Applications and Integration Essentials
A Developer's Guide to Deploying Text Models: From Use Case Selection to Invocation and Cost Control
Why Use gpt-6-luna for Use Case Validation
Before choosing a model, choose the type of problem. gpt-6-luna is a text-output model offered by OpenAI, priced by token, with both input and output counted toward consumption. This means it is naturally suited to "text in, text out" tasks: understanding, summarizing, rewriting, generating, and discriminating—without taking on multimodal responsibilities like images or audio. Stuffing unsuitable tasks into a text model usually isn't a sign that the model isn't powerful enough; it's that the problem itself shouldn't be solved by it.
As a starting point for use case validation, it has three practical advantages. First, a unified interface: a single request consists of a message list, so the engineering side only needs to focus on input organization and output parsing, without introducing different SDKs for each use case. Second, predictable billing: token pricing ties cost directly to text length, so during the validation phase you can roughly estimate budget based on call volume and average length, rather than only discovering overspend when the bill arrives. Third, clear task boundaries: pure text capability makes evaluation metrics easy to define—accuracy, format compliance rate, and manual revision rate are all quantifiable.
The correct order for the validation phase is: first use a small number of real samples to run through one pipeline and confirm output quality and format stability; then gradually scale up, observing the token consumption curve; only then discuss whether to expand to more business lines. Doing it in reverse—integrating at scale first and then going back to add quality evaluation—often incurs higher costs in rework.
Also be clear about what it is not suitable for. Tasks requiring real-time deterministic computation, strongly consistent rule validation, or verbatim comparison of very long documents are more cost-effective with a rule engine or traditional retrieval solution; the model's value lies in handling ambiguous, open-ended inputs that require semantic understanding. The criterion is simple: if you give the same input to two different people, would their reasonable outputs differ? If they differ, the task needs semantic capability; if not, writing rules is more economical.
Use Case 1: Content Generation and Batch Copywriting
Batch copywriting is the most direct scenario and also the easiest to stumble in. Its core is not "making the model write well" but "making a hundred outputs all conform to the same set of specifications."
Fix inputs with templates
Organize each call into a fixed structure: task description, target audience, tone and length constraints, required elements, prohibited expressions, and one reference example. Templating makes behavior reproducible—running the same batch of data again won't cause output style to drift. Field-based inputs also make subsequent A/B comparisons easier, for example changing only the tone description and observing output differences.
Programmatic validation of outputs
Don't assume the model will always follow the format. Validate immediately after generation: is the length within range, does it contain prohibited words, are all required elements present, are structured fields parseable. Failed items should go to retry or fall back to template-based defaults, rather than being written directly to the database. Counting validation results as quality metrics is more reliable than manual spot checks.
Design summarization and rewriting separately
For summarization tasks, clarify "for whom, how long, which information to retain." State clearly in the instructions to preserve original meaning and not add facts absent from the source, and perform a simple factual comparison during validation. For rewriting tasks, clarify the boundaries of permissible changes: terminology, brand names, and numbers are usually not allowed to change; these should be provided as a list in the input and checked item by item after output.
Keep batch processes manageable
For batch writing, process in shards and record success and failure counts for each shard. Keep failed items' original text and error reasons separately for centralized retry. After the entire batch completes, calculate average token consumption and manual revision rate once—these two numbers determine whether this pipeline is worth keeping long term.
Use Case 2: Customer Service and Q&A Assistants
The difficulty in customer service scenarios has never been model capability, but boundary management. An assistant that answers beautifully but oversteps its authority is riskier than one that answers conservatively.
Context organization
Put conversation history, user identity-related background, and business knowledge snippets together into the input, but be selective. The longer the history, the higher the token consumption, and early irrelevant content dilutes the focus of the current question. In practice, keep the most recent several turns of dialogue and compress earlier content into a one-sentence summary; inject only a small amount of retrieved knowledge snippets rather than stuffing in the entire database.
Answer boundaries
In system instructions, clarify three types of behavior: what can be answered, what must be escalated to a human, and what must never be promised. Highly sensitive topics such as refunds, compensation, legal and medical advice should be set to escalate to a human directly, not left to the model to improvise. Also require the model to clearly say it doesn't know when information is insufficient, rather than completing a plausible-sounding answer.
Human fallback and traceability
Each model-generated answer should record the input summary, output version, and matched knowledge snippets for later review. Set clear fallback trigger conditions: low model confidence, sensitive keywords involved, or unresolved consecutive user follow-ups. Fallback is not failure; it is part of the design.
Effectiveness evaluation
In the early launch phase, use manual spot checks to evaluate answer accuracy and human escalation rate; introduce automated metrics once stable. The two types of errors that truly need watching are: fabricating nonexistent information, and failing to escalate when escalation was needed. The former damages trust; the latter amplifies risk.
Use Case 3: Structured Information Extraction
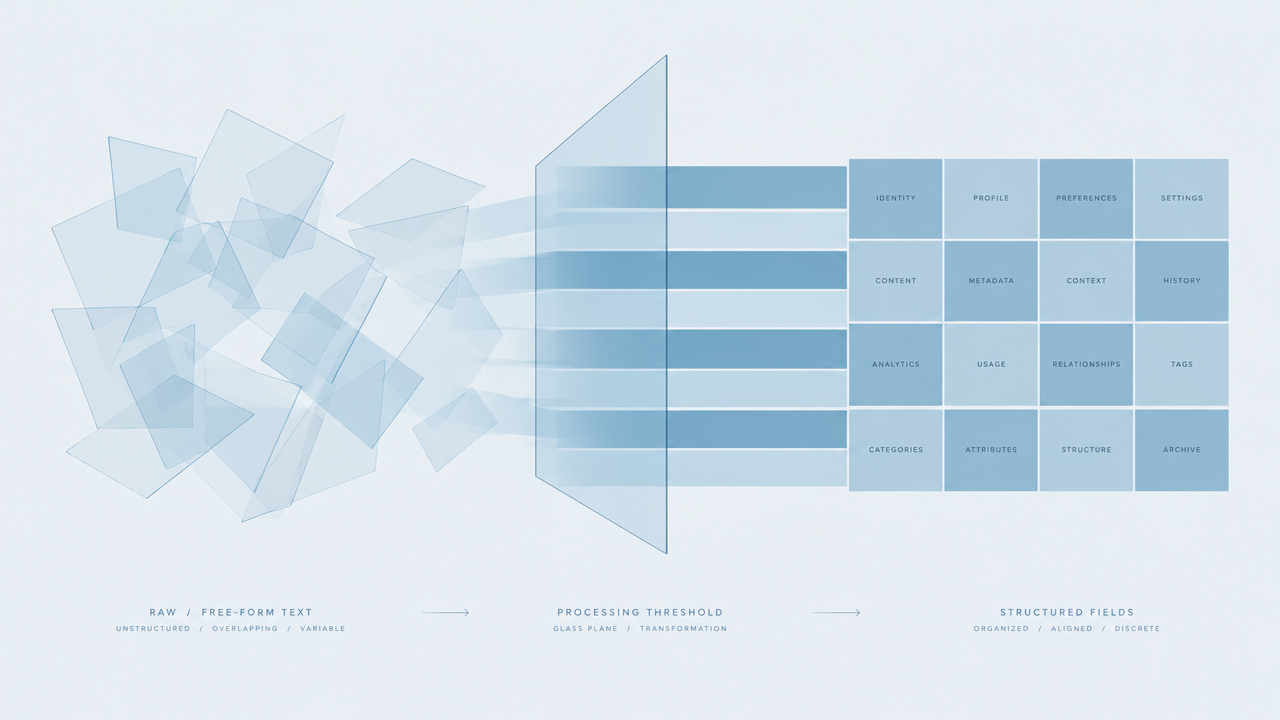
Converting free text into structured fields is a high-ROI use case: the input is messy natural language, and the output is key-value pairs that can be written directly to a database.
Define the target schema first
Before writing instructions, settle the target structure: field names, types, whether required, value ranges, enum items. The clearer the schema, the more stable the output. In field design, prefer splitting finely rather than cramming multiple semantics into one free-text field, otherwise subsequent validation has no starting point.
Output format constraints
Require the model to output only structured results, without explanatory text. Also provide a complete output example—examples are more effective than rule descriptions. For enum fields, list all legal values in the instructions and specify what placeholder to use when a judgment cannot be made.
Validation and fault tolerance
Immediately perform programmatic validation after receiving output: can it be parsed, are required fields missing, are enum values legal, are numeric values within reasonable ranges. Don't silently discard failed-to-parse samples; record the original input and model output for instruction iteration. For key fields, design a second validation: pass the extraction result together with the original text snippet to the model for consistency confirmation.
Handling long text
For documents exceeding single-pass length, split by semantic boundaries before extraction, then merge results. When splitting, be careful not to split one field's information across two snippets. In the merge phase, mark conflicting fields for human adjudication.
Use Case 4: Code and Documentation Assistance
Development assistance is a natural scenario for text models, but it must be used in the right places.
Code explanation and onboarding reading
When facing an unfamiliar codebase, give the model the context of a single file or function and ask it to explain responsibilities, inputs and outputs, and potential side effects. This use case is low-cost and directly beneficial, suitable for onboarding new team members and untangling legacy systems. The key point is to control the context scope: give only one independently understandable unit at a time, not the entire repository.
Documentation generation
Generate API documentation from function signatures, comments, and usage examples, then have a human proofread it. In the instructions, clarify the target audience and format of the documentation, and emphasize not fabricating parameter behavior. Generated documentation must be reviewed together with the code, not published directly.
Review comments and test drafts
Having the model list potential issues in a change snippet is a great supplementary tool, but it cannot replace human review. In practice, position it as "a first pass," with humans deciding which comments are worth following up. The same applies to test cases: model-generated cases usually cover common paths, while boundary conditions still require engineering judgment.
Precautions
Do not paste real keys, internal addresses, or user privacy data into prompts. For API usage, version numbers, and configuration items given by the model, always verify against official documentation—these details are the most prone to plausible but nonexistent fabrications.
Use Case 5: Analysis and Decision Support
Lightweight analysis tasks are suitable for text models: organizing a large amount of scattered text into readable conclusions saves human reading time, rather than replacing human judgment.
Comment categorization and key point extraction
User feedback, interview records, and ticket content are all typical inputs. The approach is to first define a classification system, have the model assign each piece of text to an existing category with a one-sentence reason, then extract key points for each category. The classification system must be defined in advance; open-ended "categorize as you like" will yield results that cannot be aggregated.
Comparative analysis
Present descriptions of multiple solutions or products side by side, require the model to compare item by item along unified dimensions, and annotate information sources. The output should be a dimension-based comparison, not a vague overall judgment of pros and cons. For judgments where the model finds no basis in the input, require it to explicitly mark them as speculation.
Limitations that must be acknowledged
Text models are not good at precise statistics and numerical reasoning, nor do they know facts beyond the input. Any judgment involving quantities, ratios, or trends should be calculated separately based on structured data; the model is only responsible for explanation and expression. For high-risk decisions, output can only serve as reference material, not as a conclusion.
Evaluation approach
Evaluation of analysis tasks is mainly manual: sample a portion of outputs and check whether categorization is reasonable, whether key points miss critical information, and whether there is over-inference. Writing discovered issues back into the instructions is the most effective optimization method.
Cost Control Strategies under Token Pricing
Pricing by token means cost is directly related to text length; controlling cost is essentially controlling the scale of input and output.
Estimate call volume first
Cost estimation starts with three numbers: average daily call count, average input tokens, average output tokens. Run a round with real samples to get the actual distribution, rather than filling in by feel. Distribution is often more meaningful than the average—if a few very long requests account for most consumption, optimization efforts should focus on them.
Compress input
Input is usually the bulk of the cost. Feasible measures include: removing redundant explanations from templates, trimming examples to the necessary minimum, replacing long history with summaries, and injecting only relevant snippets after retrieval. Each measure should be judged by "does output quality decline after removal," rather than blindly trimming.
Constrain output
Output length is also controllable. Specify word count or item count limits in the instructions, require conclusions first, no repeating input content, and no pleasantries. For structured tasks, requiring only field values can significantly reduce wasted tokens.
Caching and degradation
Cache results for highly repetitive requests, such as identical product description rewriting needs, returning directly on cache hit. Design degradation paths for non-core pipelines: fall back to templates or rule-based solutions when the model is unavailable, ensuring the main flow doesn't break. Also set limits on single-request and daily call volume to prevent abnormal traffic from amplifying consumption.
Continuous observation
After launch, track average token consumption, failure retry rate, and manual revision rate. Retries themselves are a cost; unstable output often means the instructions need fixing, not trying a few more times. For current real-time prices and billing details, refer to the site's pricing panel.
Integration Launch Checklist
Confirm the following items one by one before launch to avoid most common problems.
Input and output boundaries
- Are the task, target audience, format, and length constraints clearly specified in the instructions
- Are output examples and a list of prohibited behaviors provided
- Are clear escalation-to-human or refusal rules set for sensitive topics and overstepping requests
- Is the input free of keys, internal addresses, and user privacy data
Error handling and retry
- Are retryable errors (timeout, rate limiting) distinguished from non-retryable errors (invalid input, content violation)
- Do retries have a maximum count and backoff strategy to avoid amplifying costs
- Do requests that still fail after retry have a fallback path, rather than interrupting the main flow
Logging and observability
- Are the input summary, output result, elapsed time, and token consumption recorded for each call
- Are failed samples retained separately for reproduction and instruction iteration
- Are key metrics such as average token consumption, failure rate, and manual revision rate tracked
Effectiveness evaluation and iteration
- Was small-scale validation done with real samples before launch
- Are there clear quality metrics and a manual spot-check cadence
- Are instruction changes versioned for rollback and comparison
Alignment with business processes
- Is the model output's position in the business process clear: is it a suggestion, a draft, or a result that can be adopted directly
- Which steps must be confirmed by a human, and is this solidified in the process
- Has it been confirmed whether rules or traditional solutions are more cost-effective for this scenario
Treat this checklist as a launch gate, not a one-time document. Every time you expand to a new scenario or adjust instructions, it's worth going through the relevant items again.
Related articles
View all articles →-

Tutorial
How to Call hailuo-2.3-fast/image-to-video via the HiAPI API: curl and Python
A first working request for the fast, low-cost image-to-video tier — from model ID to downloaded MP4
9 min read -

Tutorial
How to Use hailuo-2.3/text-to-video via the HiAPI API: curl, Python, and a Working Request
11 min read -

Tutorial
Kandinsky 6.0 Pro Text-to-Video on HiAPI: curl and Python Tutorial
A request-first walkthrough: build the prompt-to-clip call, submit it, poll for completion, and download the result
11 min read