
Guide
GLM 5.3 Structured Extraction in Practice: Give Every JSON Field Textual Grounding
Use JSON object mode for field extraction, and use missing values, quotations, and business validation to stop errors before they enter the database

On this page
Why structured output still needs "textual grounding"
JSON object mode (response_format: {"type": "json_object"}) solves the problem of "is the output form a JSON object", not "will this request definitely succeed, will the content definitely be complete, will parsing definitely not throw". Requests can fail, the model can refuse to answer, output can be truncated due to length limits, streaming can be interrupted, and the returned content can be incomplete or malformed; the client must handle these cases as well as parse exceptions from json.loads. You must first confirm that the response completed normally and the content is complete before parsing. Being parseable does not mean being usable: correct format does not mean correct facts. Whether a field value was extracted from the source text, whether the model casually filled it in, and whether a field is "not written in the source" or "written as empty in the source" are all outside the scope of format constraints.
Writing a field template into the prompt is essentially giving the model a "form to fill in", not an "evidence list". When a field lacks textual support, the model tends to give a seemingly reasonable value — this is the most dangerous failure mode in extraction tasks, because it does not report an error; it only quietly pollutes downstream data.
Therefore, the extraction contract in this article consists of three parts: field and type definitions, a source quotation accompanying each value, and explicit modeling of missing values. Together, these make "where did this sentence come from" part of the output rather than an after-the-fact guess.
Designing the extraction contract: fields, types, and nullability conventions
The contract starts with the field list. Suppose the task is to extract structured information from a job/cooperation description; first fix the target fields:
title: string, requiredbudget: number, nullabledeadline: string (ISO date), nullablecontact: string, nullableskills: string array, may be an empty array
The key point is that "nullable" does not mean "may be omitted". Agree that every field must appear in the output, and when unknown, explicitly give null or an empty array; omitting keys is not allowed. Omitting keys prevents downstream from distinguishing "the model judged it empty" from "the model did not process this field at all".
Types should also be tightened to a granularity that machines can determine: budget only accepts numbers, not strings like "negotiable"; deadline follows the YYYY-MM-DD format; skills must be a string array, and a single comma-joined string is not allowed as a workaround. The more specific the types, the more the validation layer described later can stop problems.
The following is the field description written into the prompt, not a request parameter; the request parameter is only responsible for enabling JSON object mode.
Output a JSON object containing exactly the following keys:
- title: string
- budget: number | null
- deadline: string (YYYY-MM-DD) | null
- contact: string | null
- skills: string[]
All keys must be present. When a value cannot be determined from the source text, fill in null (empty array for arrays); do not guess.
Give every field a quotation fragment
Giving only values without sources means giving up traceability. The approach is to turn each extractable field into a paired structure: value and quotation come out together.
{
  "title": {"value": "Data Analysis Intern", "evidence": "Hiring 2 Data Analysis Interns"},
  "budget": {"value": 300, "evidence": "Daily pay 300 yuan"},
  "deadline": {"value": null, "evidence": null},
  "contact": {"value": "hr@example.com", "evidence": "Send your resume to hr@example.com"},
  "skills": [
    {"value": "SQL", "evidence": "Familiarity with SQL required"},
    {"value": "Python", "evidence": "Python skills preferred"}
  ]
}
Several points. First, evidence must be a contiguous fragment of the source text, not the model's paraphrase or summary — paraphrasing makes the quotation lose its value for comparison. Second, when the value is null, evidence must also be null; this constraint alone can suppress some fabrication: if the model invents a value, it usually cannot invent the corresponding source fragment, so the format becomes self-contradictory. Third, array fields provide quotations per element rather than one quotation for the whole array; otherwise one bad element contaminates the credibility of the entire group. Fourth, quotation fragments should be as short as possible, covering only the minimal text that supports the value, to facilitate subsequent string-containment comparison.
This increases output size, but in exchange: any record entering the database can answer "which sentence in the source is this field based on".
Explicitly handle missing values and uncertainty
The most common mistake models make in extraction tasks is not wrong extraction but "completion". We need to model three situations separately at the contract level.
Missing. The source text has no relevant information at all; the field is null. This semantics must be distinguished from "the value is an empty string": an empty string is a value that was extracted, while null means it could not be extracted. Only when the upstream convention is clear can downstream decide whether to skip or alert.
Ambiguous. The source text has a relevant statement but it is insufficient for determination. For example, it only says "salary negotiable"; in this case budget should be null, and the prompt should clearly state: do not convert qualitative descriptions into numbers, and do not map "negotiable" to 0.
Multiple candidates. The source text contains two contact methods or two dates, but the contract accepts only a single value. Possible approaches are to let the field structure support a candidate list, or to specify a priority in the prompt (such as taking the first occurrence). Whichever you choose, it must be written into the contract; otherwise the model's selection strategy may differ each time, making results hard to reproduce stably.
Add one more fallback: allow the model to output an unresolved array listing key information it cannot assign to any field. This is much safer than forcing it into some field, and it also gives you an entry point for observing the model's failure modes.
Three layers of business validation before entering the database
JSON object mode only constrains the output form; parsing can still fail. Validation is performed in order: first confirm response completeness, then perform client-side structural and business validation, and finally perform evidence checking; if the previous layer fails, do not proceed to the next.
Before parsing, check: whether the request returned successfully, whether a refusal appeared, whether the finish reason shows truncation due to length, whether the streaming response ended normally, and whether the content is empty. After confirming that the response completed normally and the content is complete, run json.loads; parse exceptions go directly to failure handling, and partial content is not sent into subsequent validation. Only after successful parsing do we enter the following three layers of validation.
Layer 1: Types and structure
Whether keys are complete, whether types match, whether deadline satisfies the date format, and whether budget is a finite number. This layer can be done with ordinary code; it is low-cost and has the highest interception rate.
Layer 2: Enums and value domains
Block values that are impossible in the business: negative amounts, dates earlier than today, empty strings or duplicates in skills, and string lengths exceeding field limits. If the field itself has a controlled vocabulary (such as industry or job level), perform whitelist matching here and reserve a place for synonym normalization.
Layer 3: Cross-field consistency
A single field being valid does not mean the whole record holds. Typical checks include: when budget is non-null, whether deadline is also non-null (in many business scenarios the two are bound together); whether contact contradicts the job type implied by skills; and whether the field distribution of records with the same title in the same batch is abnormally concentrated. This layer is closest to business semantics and also the one that most needs tests.
Do not forget mechanical validation of evidence: when the value is non-null, evidence must be non-null and should be matchable in the input source text via string containment or fuzzy matching. A failed match does not necessarily mean immediate discard, but at minimum it should be marked low-confidence and sent to a human queue.
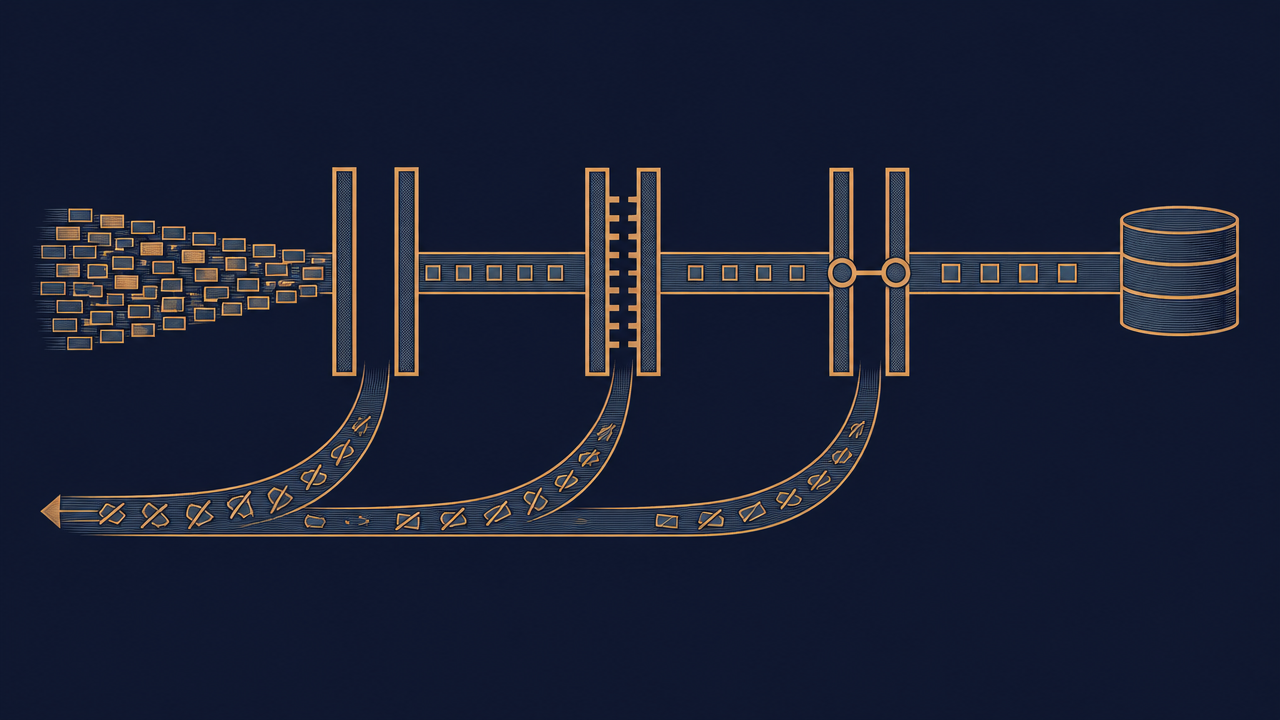
Turn validation failures into the next-round prompt
The worst thing to do after validation failure is to resend the request as-is and hope this time it extracts correctly. Better is to feed the failure reasons back in a structured way:
The previous output failed validation:
- The value "ASAP" for deadline does not conform to the YYYY-MM-DD format
- The evidence for skills[2] could not be found in the source text
Please fix only the issues above, keep the other fields unchanged, and output the complete JSON again.
Three details are worth noting. First, error messages should point to specific field paths so the model can make local corrections rather than redoing the whole thing. Second, explicitly require that "other fields remain unchanged"; otherwise new errors are easily introduced, causing an oscillation where fixing one thing breaks another. Third, set a retry limit (for example, two rounds); once exceeded, put it into the human queue rather than looping infinitely — infinite retries both lengthen latency and drive up costs.
If the same type of error repeatedly appears during retries, that is usually not a model problem but an ambiguous contract. At this point you should revisit the field definitions and examples rather than continuing to add prompts.
How to call and the scope of this article
On HiAPI, glm-5.3 is called through the OpenAI Chat Completions-compatible protocol; JSON object mode is enabled by setting response_format to the object type in the request. For specific parameters and field names, refer to the interface documentation on the model page. The capability flag jsonObject=true means the model supports JSON object mode; it does not mean the interface supports JSON Schema response mode, nor does it mean you can rely on server-side validation against a Schema. The field structure, types, and business constraints in this article are all validated locally after client-side parsing. The extraction logic, quotation fields, and validation layer are all written on your own server; the model is only responsible for producing text according to the contract.
This article discusses only contract design and the validation process, not billing numbers or performance promises; for real-time prices and quotas, refer to the site's pricing panel. Only after field definition, quotation validation, and retry strategy are all done can you move from "format legal" to "semantically usable"; correct format does not mean correct facts, and a fixed seed does not guarantee exact reproduction either, so the retry strategy still needs limits and a human queue.
Related articles
View all articles →-

Guide
Nano Banana Basic Text-to-Image Guide: Aspect Ratio, Negative Space, and Prompt Usage
Use the task API's aspect_ratio and prompt fields to generate clearly composed images for banners and social cards
-

Guide
Kimi K3 Response Handling in Practice: Complete JSON, Stream Interruption, and Retry Boundaries
-

Guide
MiniMax Music 3 Short Song Production Guide: How to Separate Lyrics, Section Tags, and Arrangement Brief
Based on the dual required inputs of the current contract, design a reproducible short song request