ByteDance
OmniHuman 2.0
omnihuman-2.0
ByteDance's second-generation digital human video model: pair a single image of a person or character with a piece of speech or singing, and it generates a performance video in which lip movements, facial expressions, and body motions stay in sync with the audio. A single continuous shot can last up to 5 minutes, and prompts can be added to control actions and camera movement.
Try omnihuman-2.0
Input
Showcases
View all showcasesOutput
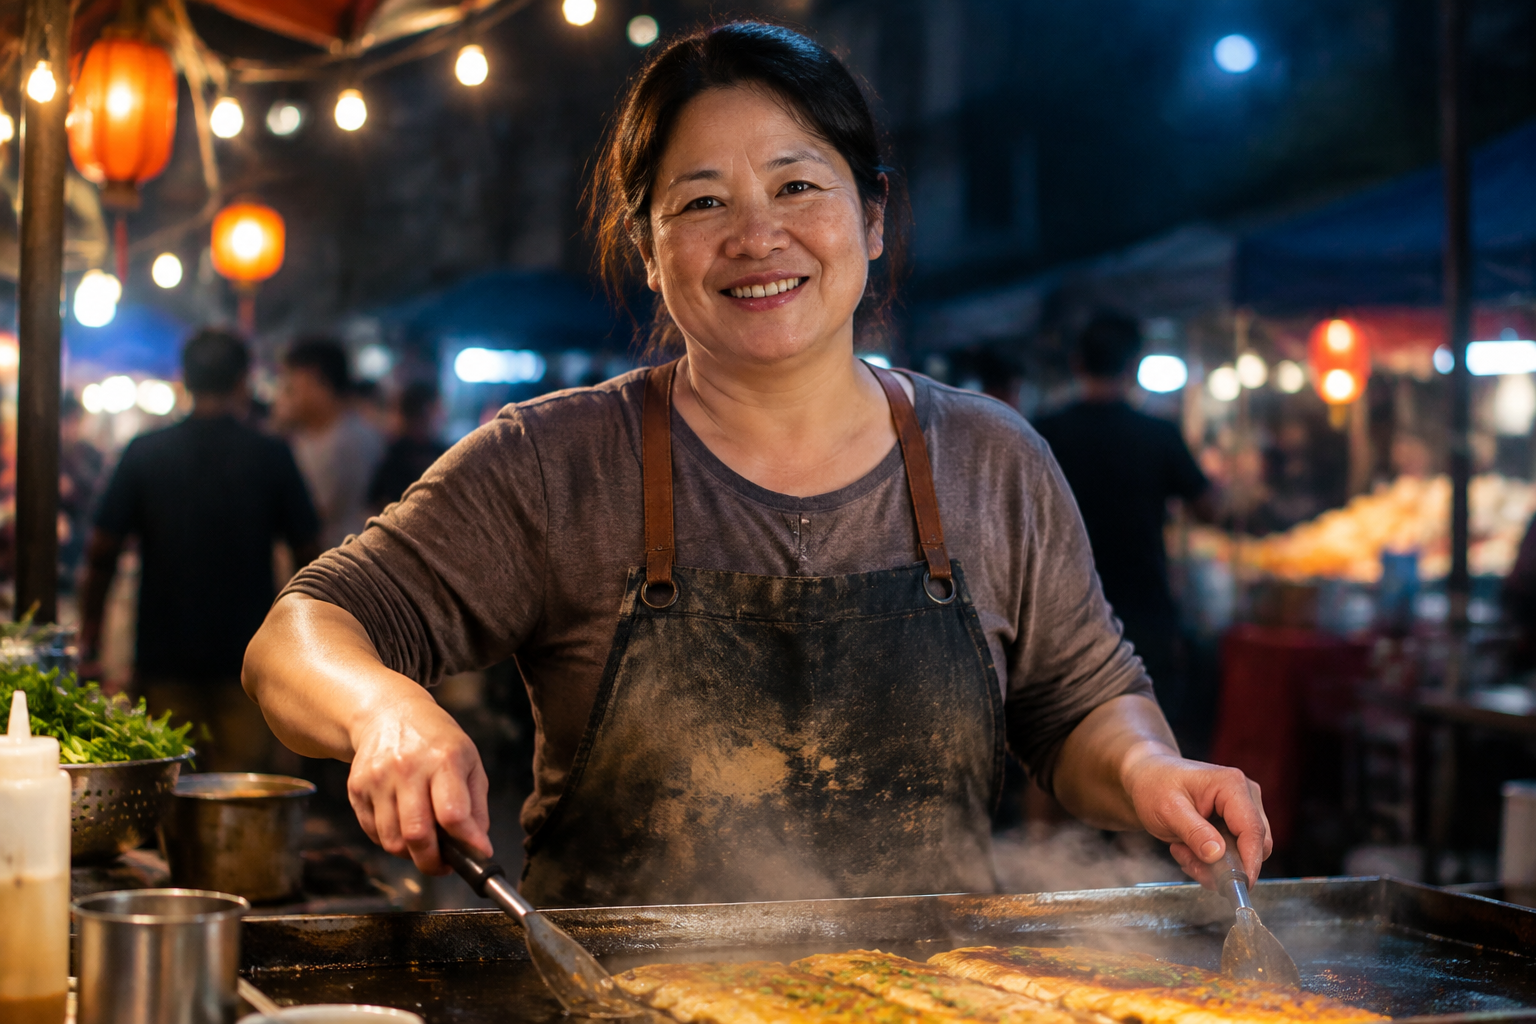
videoNight Market Vendor's Spoken Monologue
Style portrait-avatar · Street food · lip sync
Reference inputs
audio_url
image_url
Prompt
In a night market, a street food vendor with flour-stained apron stands behind a steaming griddle, facing the camera and speaking with a warm, natural, friendly smile, making a small gesture to emphasize their tone, string lights hanging behind them, steam drifting slowly; the camera slowly and gently pushes in.
Copy the full prompt and adapt it for your own generation.
Tags
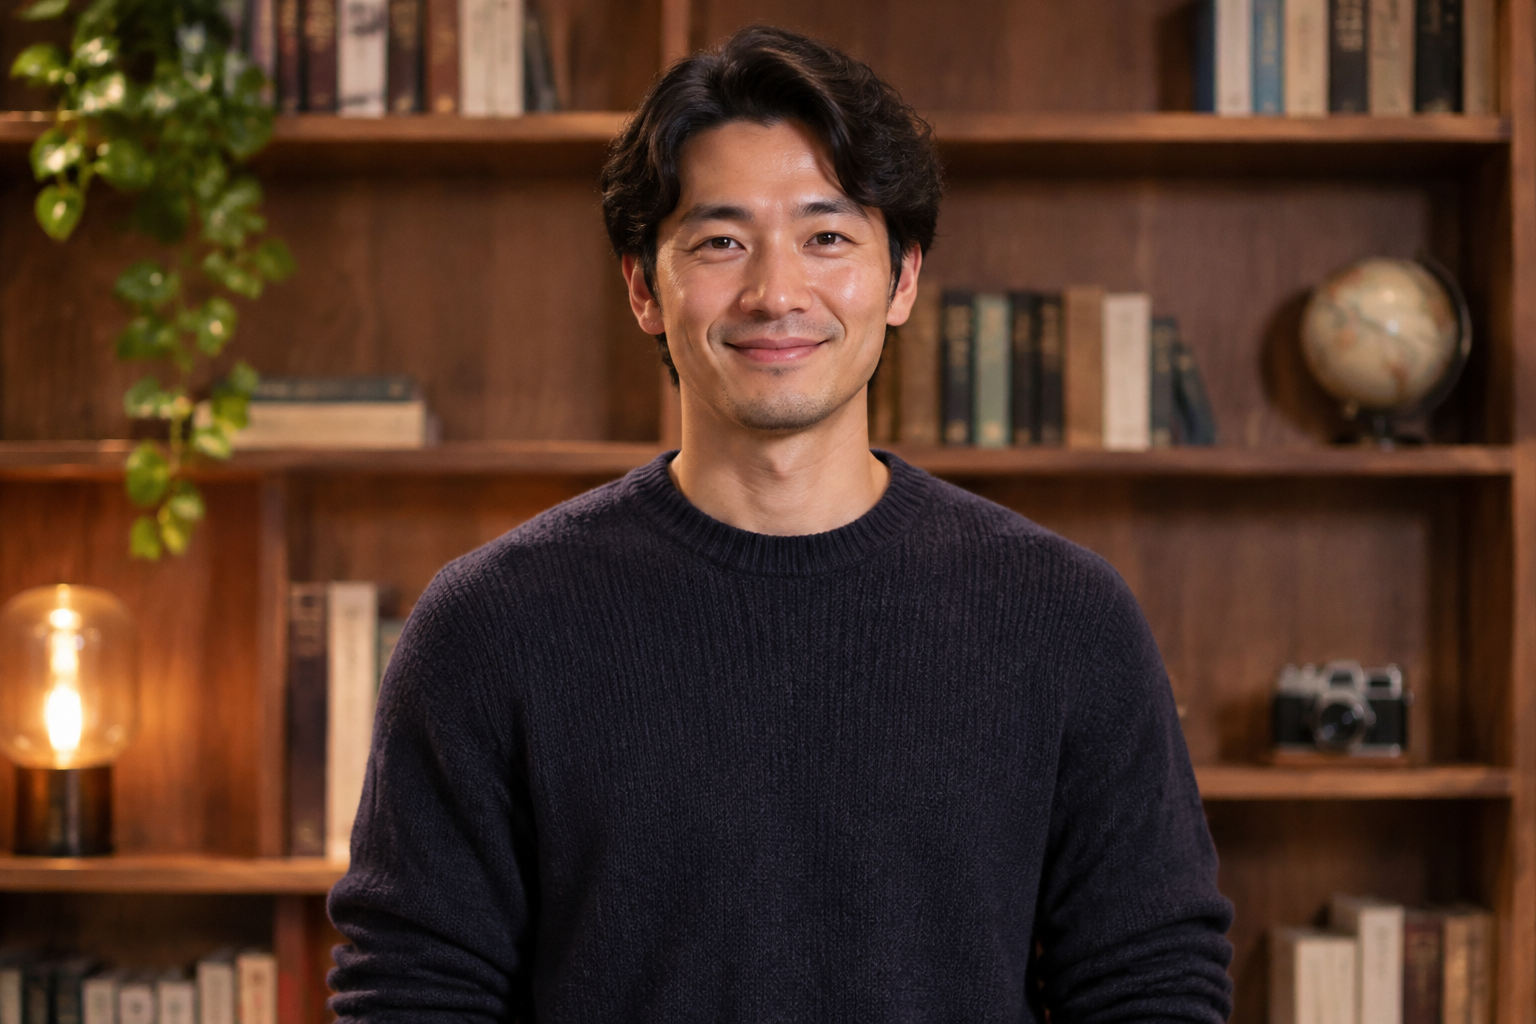
Knowledge Presentation in Front of a Bookshelf · Digital Human Talking-Head Video
Style Spoken presentation · Education · Studio portrait
Reference inputs
audio_url
image_url
Prompt
A composed presenter wearing a dark knit sweater stands in front of a warm wooden bookshelf and speaks to the camera; lip movements are natural, gestures are small, the camera slowly pushes in from a medium shot to a closer framing, soft warm key light.
Copy the full prompt and adapt it for your own generation.
Tags
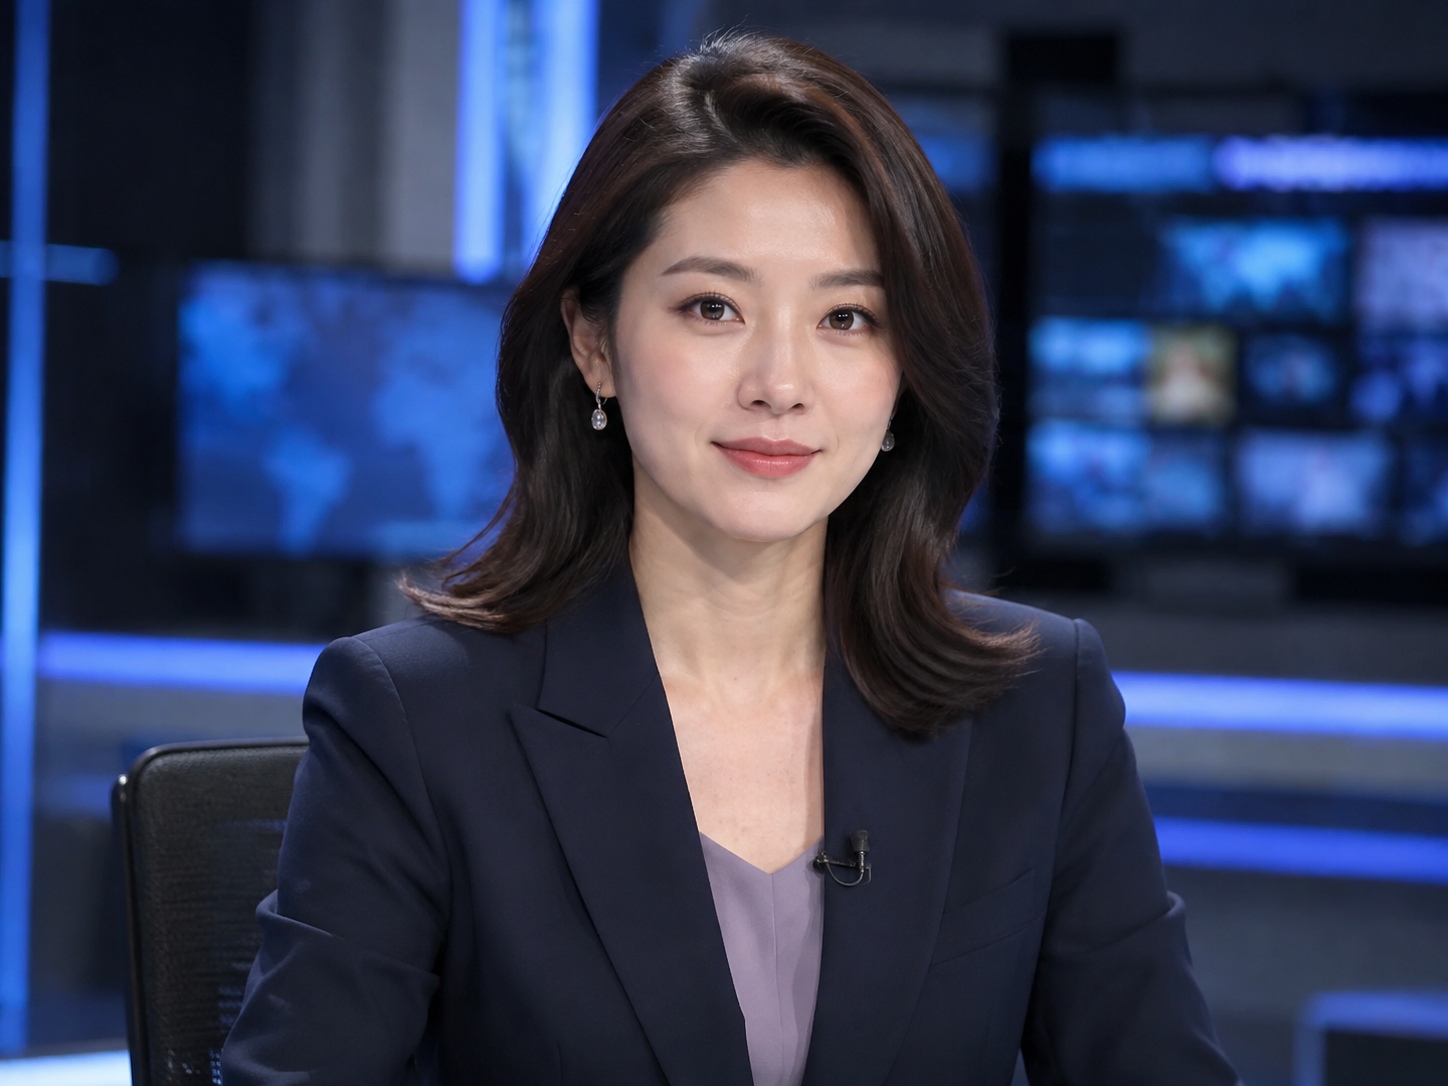
Late-Night Studio · Digital Anchor Voice-Over
Style Broadcast · Spoken presentation · Cinematic
Reference inputs
audio_url
image_url
Prompt
The camera slowly pushes in on a composed female anchor speaking as she sits at a desk in a dimly lit studio; as her tone turns wistful, she gives a slight nod and her expression softens; cool blue and amber studio lighting, with a crisp broadcast texture.
Copy the full prompt and adapt it for your own generation.
Tags
Pricing
omnihuman-2.0 per second
| Unit Price | $0.100 |
|---|
Overview
This is an audio-driven digital human video generation model that takes a photo of a real person or an illustration of a character along with speech or singing audio, and outputs a performance video synchronized with the audio. The video duration follows the audio, and the frame keeps the aspect ratio of the original image; an optional prompt can describe the scene, expressions, gestures, and camera movement. It suits developers and content creators who need character talking-head, singing, or dialogue shots, for use as character performance footage in social media short videos, marketing endorsements, and digital human applications.
Key Highlights
- Audio-driven lip and expression sync — generates matching lip movements, expressions, and body movements based on the rhythm and tone of speech and singing, with video duration matching the audio.
- Image-to-video with original aspect ratio preserved — upload a character image to generate a performance video; the output keeps the image's aspect ratio for easy embedding into existing layouts.
- Prompt-controlled performance and camera movement — an optional prompt describes the scene, expressions, gestures, and camera effects such as a slow push-in.
- A single audio clip covers minutes of performance — driving audio supports 4 to 300 seconds, and the output can extend along with the audio, suiting continuous talking-head or singing segments.
Capabilities
Image plus audio generates character video: provide a character image and driving audio to generate a video of that character performing; the image can be a real person or an illustrated character, and the output keeps the original image's aspect ratio.
Lip-synced performance: the video generates corresponding lip movements and facial expressions following the rhythm of the driving speech or singing, suiting narration, dialogue, and singing content, with video length matching the audio.
Prompt-controlled performance and camera: an optional prompt of up to 300 characters describes the scene, expressions, gestures, and camera movement.
Audio length range: driving audio must be mp3 or wav, 4 to 300 seconds long and no more than 15MB; the output duration corresponds to it, making it easy to plan long continuous performances.
Image specification range: character images support jpeg, png, or webp, no more than 10MB, with an aspect ratio between 0.4 and 2.5 and 300 to 6000 pixels per side.
Use Cases
- Social media talking-head video creators — upload a host's portrait and an explanatory audio clip to generate a character talking-head video, directly usable for short video publishing and daily account updates on social platforms.
- Virtual singing and music performances — pair a singer or virtual persona image with song audio to produce a character singing shot as performance footage for music content.
- Marketing spokesperson clips — pair a brand image with voiceover of promotional copy to generate a spokesperson or host on-camera clip for ad and campaign page display.
- Digital human application developers — integrate the API to submit character images and audio in batches, providing digital human on-camera segments for video creation applications, for pickups or dialogue shot generation.
Limitations and Selection Advice
Driving audio is a required input; video content is driven by the audio, and a character image must also be provided. Input audio duration must be between 4 and 300 seconds; tasks shorter than 4 seconds will fail with a full refund. Character images must meet format and size requirements, with an aspect ratio between 0.4 and 2.5 and 300 to 6000 pixels per side. The prompt is optional, up to 300 characters.
What's new
View changelog →- New model OmniHuman 2.0 is live: turn one portrait and an audio clip into a talking video up to 5 minutes long
Frequently asked questions
View all FAQs →-
Can it generate a video from just one image and one audio clip?
Yes. This model takes a portrait image plus a driving audio clip as input, and only image_url and audio_url are required. Images support jpeg, png, and webp, up to 10MB each, with an aspect ratio between 0.4 and 2.5 and 300 to 6000 pixels per side; audio supports mp3 and wav, 4 to 300 seconds long and no more than 15MB. The video content is driven by the audio, its length matches the audio, and the final video keeps the image's aspect ratio.
-
How long a digital human video can be generated?
A single continuous shot can be up to 5 minutes long, corresponding to an audio limit of 300 seconds, with no need to split and stitch segments. The minimum audio length is 4 seconds; tasks with less than 4 seconds will fail and be fully refunded. When you want a long continuous performance, submit the complete narration or dialogue in one audio track—this is easier than generating in segments and stitching them together, and it is also less prone to lip-sync and facial-expression jumps at the seams.
-
What is the output resolution, and can it produce 1080p?
This model has no resolution parameter, so you cannot specify 1080p. The frame size and resolution of the output video follow the input portrait image — for example, a 960×960 portrait produces a 960×960 video — and both portrait and landscape source material can be used directly. To make the output clearer, use a sharp portrait image with clean framing and clean audio.
-
Do narration, singing, and dialogue require separate models?
No, the same model covers all three audio types—narration, singing, and dialogue—so there is no separate singing mode. Its lip sync, facial expressions, and body movements change in sync with the audio's intonation, rhythm, emotion, and semantics; to switch audio types, you only need to swap the audio itself. This is also the main difference in expressiveness between it and earlier tools that only did lip alignment.
Create a generation task
https://api.hiapi.ai/v1/tasks Headers
AuthorizationstringRequiredAccount API key. Required on every request. Example: Bearer YOUR_HIAPI_API_KEY. Get your API key
Content-TypestringOptionalThe request body is always parsed as JSON; when sent, only application/json (optionally with charset) is accepted — any other value returns 415. Example: application/json.
Idempotency-KeystringOptionalIdempotency key, up to 255 bytes. Retries with the same key from the same account create the task only once; replays return the original taskId.
On network timeouts or client retries, the same key creates the task only once — no double charges (scope: the API key's account). Use a business-unique identifier as the key (e.g. "order-42"); replays return the original taskId, and keys expire 24 hours after the first request. See the Unified Async API overview for the full scenario matrix.
Body
modelstringRequiredCurrent fixed value: omnihuman-2.0
routestringOptionalCurrent fixed value: default
inputobjectRequired
Business parameters for omnihuman-2.0 and route default — see the parameter table below.
promptstringOptionalmaxLength 300Optional parameter used to describe scene, facial expression, gestures, camera movement, and other visual presentation, for example smiling while nodding or a slow push-in.
audio_urlstringRequiredThe URL of the speech or singing audio used to drive lip sync; the video duration matches the audio length, the audio must be 4 to 300 seconds long, in mp3 or wav format, and no larger than 15MB.
image_urlstringRequiredThe URL of the portrait image of the person to be animated, which can be a real person or an illustrated character; jpeg, png, and webp formats are supported, the size must not exceed 10MB, the aspect ratio must be between 0.4 and 2.5, and the pixel count per side must be between 300 and 6000; the output video follows the aspect ratio and resolution of this image.
callbackobjectOptional
Terminal-state notification config. When omitted, no callback is delivered — poll the task yourself. See the callback note below.
Provide callback.url when creating a task and HiAPI POSTs to your service once the task reaches a terminal state — no polling needed. The callback payload mirrors the task detail structure; signature verification, delivery retries and idempotency are documented on the Unified Async API overview page.
urlstringRequiredRequired when callback is present. A POST is sent to this URL once the task reaches a terminal state; must be a valid http(s) URL.
whenstringOptionalDefault: "final"Only final is supported today — notified on both success and fail.
finalstoragestringOptionalDefault: "temp"Artifact storage tier: temp (default, retained about 7 days) or persistent (long-term, billed by size). Insufficient balance or exceeding the storage cap silently downgrades to temp; the effective tier is shown in the task detail response.
temppersistentRequest examples
# Submit an async task; returns a taskId immediately (no waiting for generation)
curl -X POST "https://api.hiapi.ai/v1/tasks" \
  -H "Authorization: Bearer $HIAPI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "omnihuman-2.0",
  "input": {
    "audio_url": "…",
    "image_url": "…"
  }
}'
const res = await fetch("https://api.hiapi.ai/v1/tasks", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.HIAPI_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
model: "omnihuman-2.0",
input: {
"audio_url": "…",
"image_url": "…"
}
}),
});
const task = await res.json();
// { code: 200, message: "success", data: { taskId } }import os, requests
res = requests.post(
"https://api.hiapi.ai/v1/tasks",
headers={"Authorization": f"Bearer {os.environ['HIAPI_API_KEY']}"},
json={
"model": "omnihuman-2.0",
"input": {
"audio_url": "…",
"image_url": "…"
}
},
)
print(res.json()) # { code, message, data: { taskId } }200 OK
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-01HZTQ8BX2N3GM3YFK4Z9D7VQR"
  }
}
400 Bad Request
{
  "code": 400,
  "message": "invalid request",
  "data": null,
  "error_code": "INVALID_REQUEST"
}
Get task detail
https://api.hiapi.ai/v1/tasks/:id Response fields
taskIdstringRequiredTask ID, always prefixed with tk-hiapi-.
modelstringRequiredResolved full model name. Tasks submitted with the route parameter return base@route (e.g. gpt-image-2/text-to-image@ext); otherwise identical to the name passed at creation.
routestringOptionalPresent only when the task was submitted with an explicit route parameter; echoes the submitted value.
statusstringRequiredTask status.
queued Queued, not started yet.
handling Being processed.
archiving Processing finished, artifacts being prepared.
success Terminal: completed, artifacts available (output returned).
fail Terminal: failed (error returned).
After submission, check status: success and fail are terminal, everything else is non-terminal. Poll every 1–3 seconds until terminal. On success, download artifacts from output[].url and transfer them before expireAt; pass storage: "persistent" at creation time when long-term retention is needed.
creatednumberRequiredTask creation time (Unix seconds).
completednumberRequiredUnix seconds when the task reached a terminal state; fixed to 0 while not terminal.
outputarrayOptional
Present only when status == success. Artifact list — always an array; a single task may return multiple types at once (e.g. video + first_frame).
Array [ object ]
Array items
urlstringRequiredArtifact URL, directly downloadable.
typestringRequiredCurrent possible values: video, image, audio, first_frame, last_frame, thumbnail; more may be added later.
expireAtnumberRequiredUnix seconds until which the artifact remains accessible; download or transfer before it expires.
errorobjectOptional
Present only when status == fail.
codestringRequiredBusiness error code.
messagestringRequiredError description.
Response examples
Success
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-01HZTQ8BX2N3GM3YFK4Z9D7VQR",
    "model": "happyhorse-1-0",
    "status": "success",
    "created": 1777282033,
    "completed": 1777282099,
    "output": [
      {
        "url": "https://cdn.hiapi.ai/tasks/.../video.mp4",
        "type": "video",
        "expireAt": 1777886899
      }
    ]
  }
}
Processing (non-terminal)
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-...",
    "model": "happyhorse-1-0",
    "status": "archiving",
    "created": 1777282033,
    "completed": 0
  }
}
Failed
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-...",
    "model": "happyhorse-1-0",
    "status": "fail",
    "created": 1777282033,
    "completed": 1777282099,
    "error": {
      "code": "TASK_FAILED",
      "message": "task failed"
    }
  }
}Articles
View all articles →
Related Models
View all models →Same Type
-
 Wan 2.7 Video Alibaba $0.100 /second
-
 MiniMax H3 MiniMax $0.072 /second
-
 FLUX 3 Video Black Forest Labs $0.090 /second
-
 Vidu Q4 Preview Vidu $0.051 /second
-
 Veo 3.1 Google $0.290 /second
-
 Gemini Omni 1.2 Google $0.023 /second
-
 HeyGen Avatar V HeyGen $0.150 /second
-
 Grok Imagine 1.5 xAI $0.011 /second
-
 LTX 2.5 Fast Lightricks $0.086 /second
-
 Wan 3.0 Video Alibaba $0.040 /second
-
 Kandinsky 6.0 Pro $1.93 /video
-
 P-Video 2 Pro Avatar Pruna AI $0.029 /second