
Guide
Using heygen-avatar-iv for Short-Form Video via the HiAPI API: A Developer Guide
Avatar and audio inputs, script pacing, aspect ratio and duration, and batch generation — with runnable HiAPI requests
On this page
Why heygen-avatar-iv for short-form video
Short-form video has become a default distribution channel for product launches, changelog announcements, docs walkthroughs, and social clips. The bottleneck for most engineering teams is not the editing — it is producing a steady stream of talking-head footage without booking studio time or shipping footage back and forth with a human presenter.
That is the gap avatar video generation fills. You supply a visual identity and an audio/voice source, and the model returns a rendered clip of that avatar speaking the script. heygen-avatar-iv is the endpoint in the HiAPI catalog aimed at this workflow: short, vertical-first clips where a presenter speaks directly to camera.
This model fits when:
- You need volume. Ten localized variants of the same announcement, or a daily clip per release, is a loop, not a shoot.
- The content is script-driven. If the message is in the words, an avatar presenter is enough.
- You want reproducibility. A request is a file you can diff, version, and re-run — unlike a recording session.
- You are already calling APIs. One HTTP call slots into your existing pipeline instead of adding a new tool with its own UI.
It is a poor fit for improvised, gesture-heavy performance, or anything where the physical presence of a specific person is the point. Treat heygen-avatar-iv as a renderer: given the same inputs, you should get the same kind of output, which is exactly what makes it scriptable.
The rest of this guide walks from a single test call to a batch loop, with runnable curl and Python you can adapt. Model details and parameters live on the heygen-avatar-iv model page.
Anatomy of a heygen-avatar-iv request
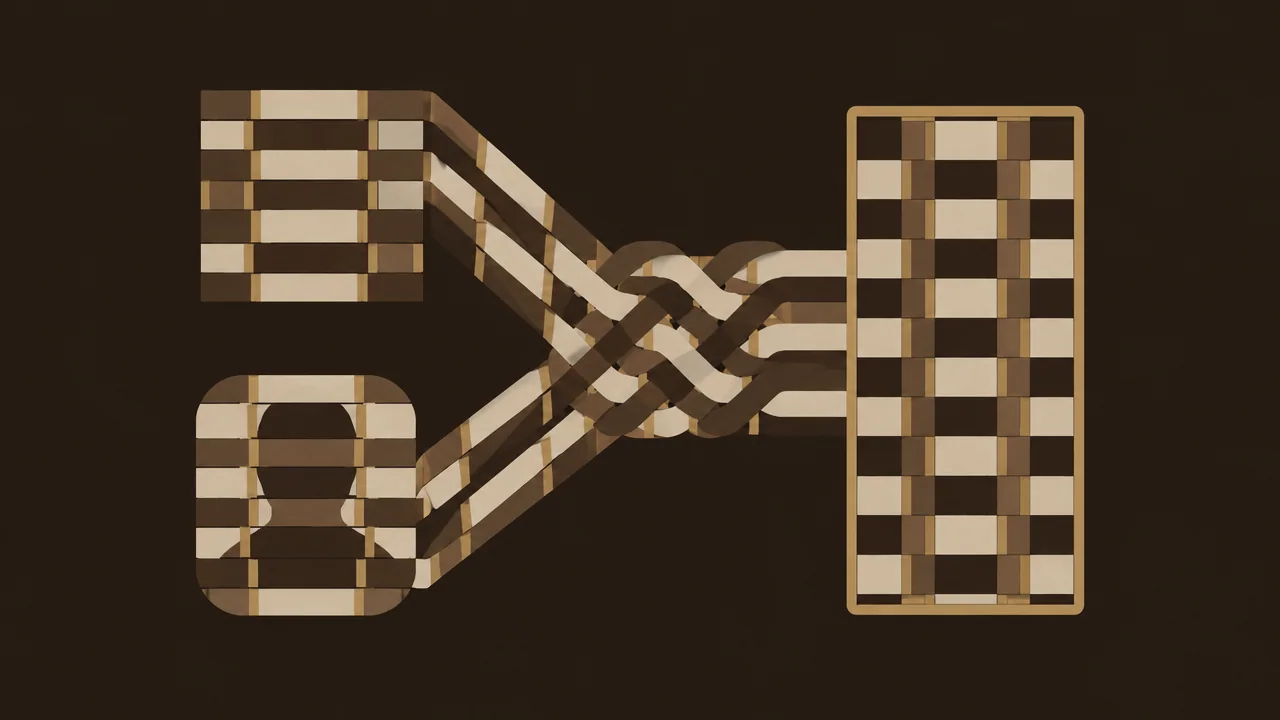
Before writing generation code, model the request as two independent input groups. Almost every early bug comes from blurring them.
Group one: visual identity
This is who appears — the avatar selection that determines the face, framing, and overall look of the presenter. Keep this group stable across a campaign. If you are producing five clips about the same product, they should share one identity block so the series reads as one presenter.
Group two: audio and voice
This is what is said and how. Depending on the request, the audio source may be a voice selection that speaks your script text, or a supplied audio track. This group changes per clip: new script, new pacing, sometimes a new voice for localization.
How they map onto the call
The HiAPI request sends both groups in one payload to the generation endpoint. Conceptually:
request
├── avatar / identity block   → stable across a series
└── audio / voice block       → varies per clip
        └── script text or audio source
Two practical rules follow from this split:
- Parameterize the audio group, freeze the identity group. In code, keep the identity as module-level constants and pass script and voice as function arguments. This makes a series visually consistent by construction.
- Change one group at a time when debugging. If a clip looks wrong, swap only the identity; if it sounds wrong, swap only the audio group. Two-variable debugging on a paid render call is expensive.
Also decide early whether your audio group is text-driven or track-driven, because that choice shapes the pacing section below — a supplied track dictates timing, while generated speech follows your script.
Exact field names, accepted values, and defaults are listed on the model page; read them once and pin them in a config object rather than scattering literals through your code.
Making your first call with curl
Start with one short clip. The goal of this call is not output quality — it is proving credentials, payload shape, and download path end to end before you automate anything.
Set your key as an environment variable so it never lands in shell history in plaintext:
export HIAPI_API_KEY="your_key_here"
Then send a minimal request. Substitute your own avatar selection and a single short line of script:
curl -X POST "https://api.hiapi.ai/v1/generate" \
  -H "Authorization: Bearer $HIAPI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "heygen-avatar-iv",
    "input": {
      "avatar": "<avatar_identifier>",
      "script": "This is a thirty second test of the avatar pipeline. If you can read this line on screen, the request shape is correct.",
      "voice": "<voice_identifier>",
      "aspect_ratio": "9:16",
      "duration": 30
    }
  }'
What to check, in order:
- Authentication. A credential error here means stop — nothing downstream matters.
- Payload validation. A schema error names the offending field. Fix one field at a time.
- Job acceptance. A successful call returns a job or task reference, not necessarily a finished file. Generation is asynchronous; note the identifier.
- Retrieval. Use the returned reference to poll status or fetch the result URL, per the response contract on the model page.
- Playback. Download the clip and watch it. Confirm framing, orientation, and that the spoken line matches your script.
Keep this curl command in a scratch file with your real identifiers filled in. It becomes your control experiment: when the Python version misbehaves, run the curl again to prove whether the problem is your code or your inputs.
Moving to Python for repeatable generation
Once the curl call works, wrap it in a function. The point is not abstraction for its own sake — it is making every parameter an explicit argument so a clip is fully described by its call site.
import os
import requests

API_URL = "https://api.hiapi.ai/v1/generate"
API_KEY = os.environ["HIAPI_API_KEY"]

# Stable across a series
AVATAR = "<avatar_identifier>"


def generate_clip(script: str, voice: str, aspect_ratio: str = "9:16",
                  duration: int = 30) -> dict:
    payload = {
        "model": "heygen-avatar-iv",
        "input": {
            "avatar": AVATAR,
            "script": script,
            "voice": voice,
            "aspect_ratio": aspect_ratio,
            "duration": duration,
        },
    }
    resp = requests.post(
        API_URL,
        headers={
            "Authorization": f"Bearer {API_KEY}",
            "Content-Type": "application/json",
        },
        json=payload,
        timeout=120,
    )
    resp.raise_for_status()
    return resp.json()


if __name__ == "__main__":
    job = generate_clip(
        script="This is a thirty second test of the avatar pipeline.",
        voice="<voice_identifier>",
    )
    print(job)
Design notes that pay off later:
- Defaults mirror your most common clip. If most output is vertical and short, default those and override rarely.
- Identity at module level. Avatar selection lives in one place, so a rebrand is a one-line change.
- Return the full response. Do not immediately extract a URL and throw away the job object; you will want the identifier for logging and retries.
- Raise on HTTP errors. Silent failures in a batch loop are worse than a crash.
- Handle the async step explicitly. Add a small
poll(job_id)helper rather than sleeping inside the generator function.
Pin the response-handling logic to the documented contract on the model page — field names for job status and result retrieval are the parts most likely to drift from your assumptions.
Writing and pacing the spoken script
Avatar video is audio-first. A script that reads fine on a page often runs long when spoken, and trimming after generation means paying to render text you will cut.
Write to length first, then trim
Estimate duration before you call the API. A comfortable speaking pace is roughly 130–160 words per minute; use the low end for technical content where viewers need to follow. So a 30-second clip wants roughly 65–80 words, and a 60-second clip roughly 130–160. Draft to that budget, read it aloud with a timer, and cut. If you must cut, cut whole sentences rather than words — sentence-level cuts keep the rhythm intact.
Structure for the ear
- Short sentences. One idea per sentence. Subordinate clauses are where comprehension drops off.
- No visual-only references. "As you can see below" does not work without the slide.
- Front-load the point. Short-form viewers decide in the first seconds; put the claim in the first sentence.
- Spell out what TTS would mangle. Acronyms, version strings, and product names with unusual casing should be written the way they should be pronounced.
Pace on a timeline
Lay the script out as timed blocks against your target length:
0–5s    Hook: the claim or problem
5–20s   Body: the mechanism, two or three sentences
20–28s  Detail: the one number or example worth keeping
28–30s  Close: the single call to action
This block structure doubles as a review artifact — a reviewer can reject a block without you re-rendering anything. Keep each clip's script in its own file, versioned alongside the code that renders it, and the batch loop in the next section becomes fully reproducible.
Setting aspect ratio, duration, and output
Decide orientation and length from the destination platform before the first render. Re-rendering a finished clip in a second orientation is pure waste, and re-editing a too-long clip means regenerating audio too.
Aspect ratio
- 9:16 vertical — the default for short-form feeds: shorts, reels, stories, and mobile-first placements. Design framing for this first; crop-down to other ratios from a vertical master when possible.
- 16:9 horizontal — embedded players, landing pages, docs videos, and presentation contexts.
- 1:1 square — feed placements that favor squares. Useful as a secondary derivative.
If your campaign needs two orientations, treat them as two distinct jobs with separate scripts, not one script rendered twice — a line that fits a 30-second vertical often leaves dead air in a shorter square cut.
Duration
Set duration from the script budget in the previous section, not the other way around. Pass a duration that matches your actual spoken length; a clip that is padded or cut mid-sentence reads as broken. Keep per-platform targets in config so they are easy to tune:
TARGETS = {
    "vertical": {"aspect_ratio": "9:16", "duration": 30},
    "horizontal": {"aspect_ratio": "16:9", "duration": 45},
}
Output
Download and store the finished clip yourself rather than relying on transient result URLs. A simple convention — {clip_id}-{orientation}-{version}.mp4 — keeps derivatives traceable and makes it obvious when a file is stale. Record the job identifier alongside the file so any clip can be traced back to its exact request.
Billing follows the generation you request — by duration and count of clips — so trimming a script before rendering is the cheapest optimization available to you. Current rates are on the pricing panel.
Batching multiple clips
With a working function, batching is a loop over a job list. The discipline that matters is that every job is a complete description of one clip.
JOBS = [
    {"id": "launch-vertical", "script_file": "scripts/launch.txt",
     "voice": "<voice_a>", "aspect_ratio": "9:16", "duration": 30},
    {"id": "launch-square", "script_file": "scripts/launch_sq.txt",
     "voice": "<voice_a>", "aspect_ratio": "1:1", "duration": 20},
    {"id": "changelog-vertical", "script_file": "scripts/changelog.txt",
     "voice": "<voice_b>", "aspect_ratio": "9:16", "duration": 30},
]

results = []
for job in JOBS:
    with open(job["script_file"]) as f:
        script = f.read().strip()
    print(f"submitting {job['id']} ({len(script.split())} words)")
    resp = generate_clip(
        script=script,
        voice=job["voice"],
        aspect_ratio=job["aspect_ratio"],
        duration=job["duration"],
    )
    results.append({"id": job["id"], "job": resp})
Patterns worth adopting:
- Scripts as files, not string literals. They get reviewed, diffed, and reused across orientations.
- Word-count logging. Printing the word count per job catches a script that will overrun its duration before you spend a render.
- Stable job ids. Use them in output filenames and logs so a failed clip is identifiable in a run of twenty.
- Fail soft, then report. Wrap each submission in a try/except, collect failures, and continue — one bad script should not abort the batch.
- Respect rate limits and concurrency. Start sequential; add a bounded worker pool only after the sequential run is reliable.
- Persist the results list. Write job ids to a JSON file so a partially completed batch can be resumed rather than restarted.
Common failure points and checks
These are the issues that surface first. Each has a cheap isolation check.
Malformed inputs
Schema errors are the most common first failure. Check: run the original curl command with the same identifiers. If curl succeeds and Python fails, the bug is in your serialization — usually a type mismatch such as a string where an integer duration is expected, or a trailing newline from a script file.
Mismatched audio and script
If the voice says something other than the on-screen intent, or the clip is silent, the audio group is wrong. Check: confirm whether the request is text-driven or track-driven and that you passed the matching field. A supplied track plus a script field is a classic silent conflict — decide which one wins and remove the other.
Wrong orientation or letterboxing
The clip comes back with bars or an unexpected frame. Check: verify aspect_ratio is actually reaching the payload — a default in your function can silently override the value you thought you passed. Log the assembled payload before sending.
Duration mismatch
The clip is cut mid-sentence or trails off. Check: compare script word count against the duration budget. Fix the script, not the duration, unless the target itself is wrong.
Identity drift across a series
Clips in one campaign look like different presenters. Check: confirm the avatar identifier is sourced from one constant, not per-job config.
Truncated or missing output
A job succeeds but the file is incomplete. Check: confirm the job reached a terminal success state before downloading, and that you followed the retrieval contract on the model page rather than guessing a URL.
The general rule: one test clip, one curl request, one variable at a time. Start with a single short vertical render through the heygen-avatar-iv model, verify it end to end, and only then let the loop scale.
Related articles
View all articles →-

Guide
gpt-6.2-sol Getting Started Guide: Capability Boundaries, API Integration, and Token Pricing Essentials
Integration decisions and practical essentials for engineering teams
-

Guide
gpt-6.2-astra Getting Started Guide: Text Model Capability Boundaries, Integration Essentials, and Cost Control
-

Guide
Tripo H3.1 Getting Started Guide: Choosing Among Three Input Modes, Parameters, and Pricing
A practical guide for developers on 3D generation integration decisions and cost control