
Comparison
gemini-4-argon Model Selection and Migration Guide: API Capabilities, Context, and Cost
From API capabilities, context, and reasoning effort to cost, an actionable model selection framework for the same family

On this page
First, clarify the boundaries of gemini-4-argon
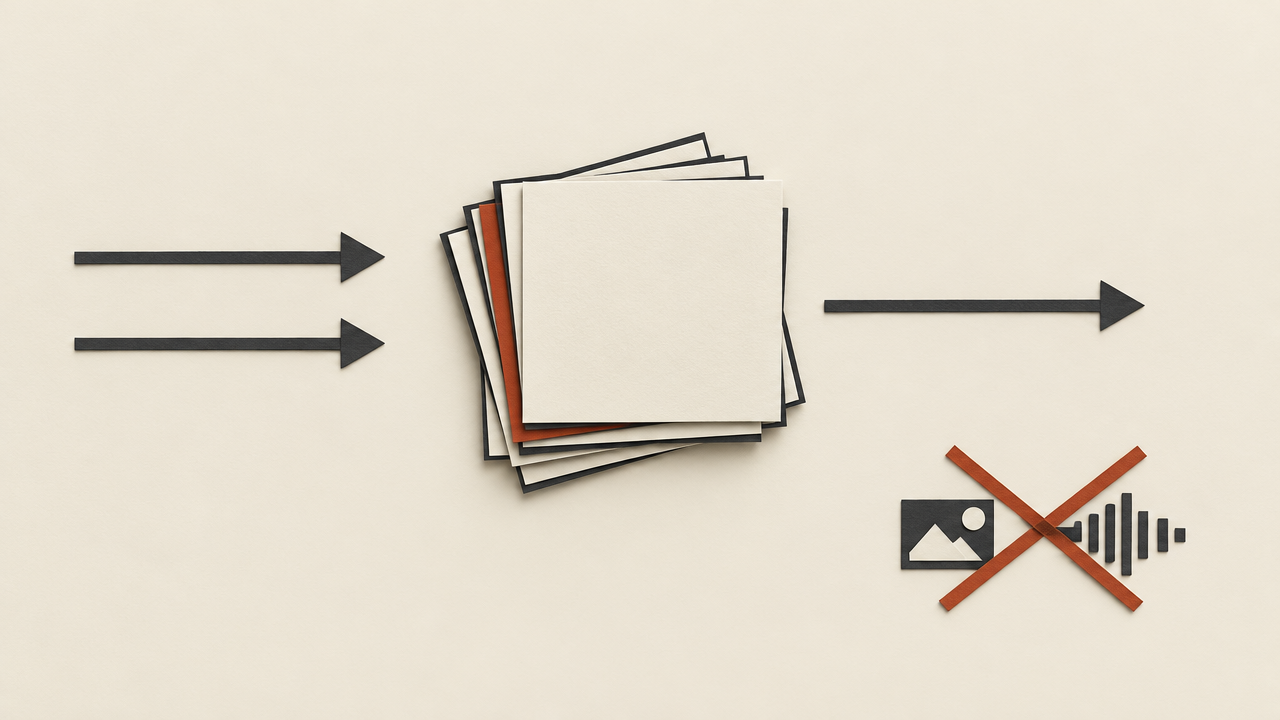
The first step in selection is not how strong it is, but whether it can be used in your current pipeline. gemini-4-argon is called through the Chat Completions-compatible API (https://api.hiapi.ai/v1/chat/completions) and supports streaming output. Each model has two routes: the standard route (model name without a suffix) and the Vertex route (model name with @vertex, such as gemini-4-carbon@vertex). Input supports only text and images, and output is text.
API shape: what Chat Completions compatibility means
If your stack already uses a Chat Completions-compatible client, integration mainly means pointing the SDK's base_url to https://api.hiapi.ai/v1, requesting https://api.hiapi.ai/v1/chat/completions, and choosing a model name. The standard route uses the model name without a suffix, and the Vertex route uses the @vertex suffix; the two routes are priced separately, so both must be included in the cost model during selection. Streaming output suits interactive scenarios because incremental results can be read continuously during generation.
Input boundaries: text and images
Input supports only text and images. If the pipeline involves other modalities, they must be converted to text or images before the call; raw files cannot be handed directly to this API. Image input can be used for tasks that require reading images; the output side is text only, so any stage that needs image, audio, or video artifacts must be handled by other services.
Capability boundaries: no tool calling or structured output
This API currently does not support tool calling / function calling, web search, computer use, or structured output / JSON mode. Pipelines that need external tools, real-time retrieval, or strict JSON output must be orchestrated in the application layer: your code performs tool execution and retrieval, then passes the results as text input; JSON structure is constrained through prompts and validated with fallbacks in the parsing layer.
Context and output limits
The context is 1,048,576 tokens, and the maximum single output is 65,536 tokens. Long-document tasks can fit the entire document, but costs should still be estimated from input and output lengths; the output limit is a hard constraint, so overlong generation requires splitting the task.
A quick exclusion check
Write three lines at the top of the evaluation sheet: whether the input is only text and images, whether the pipeline depends on tool calling or JSON mode, and whether the context and output limits are sufficient. If any line fails, mark gemini-4-argon as "not applicable for now" and record the reason, rather than continuing to quality evaluation—this saves a great deal of wasted trial-and-error time.
Which dimensions to compare across models
The most common mistake in model comparison is making decisions based on a single score from a public leaderboard. Leaderboards measure general capability, while your system cares about performance on specific tasks, specific latency budgets, and specific failure modes. It is recommended to fix five dimensions, each with a measurable proxy metric.
Within HiAPI, the positioning of the three models can serve directly as the first layer of screening: Carbon is the strongest model in the Gemini 4 family, aimed at the most complex multi-step, long-horizon tasks; Argon suits most software engineering and knowledge work, balancing capability and cost; 3.8 Flash is fast and inexpensive, suitable for high-concurrency, low-latency tasks.
Quality
Do not describe quality as "feels better"; ground it in pass rates on specific tasks: field accuracy for extraction tasks, confusion matrices for classification tasks, human ratings or rule-check pass rates for generation tasks. Quality must be measured on your own evaluation set, not cited from someone else's conclusions.
Latency
Distinguish first-token latency from overall completion time. Interactive scenarios (real-time completion, conversation) are sensitive to first-token latency; batch scenarios care more about throughput and total time. Also record how latency changes with long input, because token-priced models often come with performance degradation as context grows.
Stability
This includes timeout rate, error rate, rate-limit trigger frequency, and output-format compliance rate. Many "poor results" issues are actually occasional output-format non-compliance causing parse failures, and such issues are amplified under high concurrency.
Cost
Cost cannot be judged by unit price alone; look at cost per unit of business output: how many tokens a real task consumes on average, what the retry rate is, and whether longer prompts are needed to compensate for capability gaps. A cheap model that needs two retries may have a higher real cost. Current prices for the three models are as follows (USD / million tokens, input / cached input / output):
- gemini-4-carbon and gemini-4-argon: standard route 1.00 / 0.05 / 5.00; @vertex route 1.64 / 0.09 / 8.20.
- gemini-3.8-flash: standard route 0.19 / 0.02 / 0.92; @vertex route 0.62 / 0.07 / 3.08.
During selection, estimate input and output separately: long-document Q&A mainly consumes input, while generation tasks mainly consume output.
Capability boundaries
Explicitly record what the model is not good at: whether it tends to lose middle information in long text, whether it tends to over-expand output, and whether it is unstable with specific languages or domain vocabulary. Boundary information is more decision-relevant than strength information because it determines how much engineering fallback you need. The context limit of 1,048,576 tokens and the single-output limit of 65,536 tokens are hard boundaries; reasoning_effort can be low / medium / high, and the level should be chosen based on actual task evaluation—fix the same level when comparing quality and token consumption. The API does not support tool calling, web search, computer use, or structured output, so pipelines involving these capabilities need application-layer supplementation.
Turn these five dimensions into a fixed template and fill in the same table every time you evaluate similar models, so conclusions are comparable.
Match models by task type
Different task types are sensitive to different aspects of a model. Below are judgment approaches for common text tasks to help choose among Carbon, Argon, and 3.8 Flash.
Extraction and structured transformation
Converting unstructured text into JSON, entities, and field values. This API does not support structured output / JSON mode, so format compliance must be ensured through prompt constraints and parsing-layer validation; the model's "creativity" requirement is low, while instruction-following requirements are high. If the current model's main pain point is occasional extra explanations causing parse failures, it is worth putting Argon or Flash into the candidate set for a comparison round, but parse failure rate should be treated as an independent metric.
Classification and routing
Label determination, intent recognition, content grading. Tasks are short and call volume is high, so 3.8 Flash's speed and price better suit high-concurrency, low-latency scenarios; if classification requires multi-step reasoning or higher accuracy, then evaluate Argon. Such tasks usually do not require frequent model changes unless the error rate becomes a bottleneck.
Summarization and rewriting
Output length is controllable and quality can be human-evaluated. Argon suits most knowledge work, while Carbon is for long-text tasks requiring multi-step reasoning; for such tasks, pay special attention to output token volume: whether the model tends to be verbose and whether it obeys length constraints directly determines cost. During evaluation, use "proportion meeting length constraints" as an independent metric.
Long-document Q&A
Multi-segment input requiring locating key information. The 1,048,576-token context can hold an entire long document, but under token-based pricing, input costs must be estimated carefully, and this is also a typical scenario for testing whether the model loses middle information. It is recommended to prepare separate samples where "the answer is in the middle of the document."
Generation tasks (copy, explanations, code comments)
Quality evaluation is subjective, so use rule checks plus sampled human ratings, and avoid drawing conclusions from a single example. Carbon targets the most complex multi-step, long-horizon tasks, Argon suits most software engineering and knowledge work, and 3.8 Flash suits high-concurrency, low-latency generation; when downstream systems depend on format, output stability still requires close monitoring.
Judgment principles: the more structured the task, the shorter the output, and the stricter the format requirements, the more suitable Flash or Argon is for comparison; the more complex the task, the more steps involved, and the more long-horizon reasoning is needed, the more Carbon should be evaluated; pipelines that depend on tool calling, web search, or strict JSON mode need application-layer capabilities added first.
Cost estimation methods for token-based pricing
In cost estimation under token-based pricing, errors mainly come from three places: substituting averages for distributions, ignoring retries, and ignoring prompt bloat. Below is a reusable estimation process.
Step 1: Obtain the real length distribution
Collect the distribution of input lengths and output lengths from online logs or offline samples, looking at at least P50 and P90. Averages severely underestimate cost because a small number of overlong requests often contribute most token consumption. If your business has cases where "a few users upload entire documents," model that separately.
Step 2: Break down the token composition of each call
The total tokens of a call usually include: system prompt, conversation history or context, user input, and model output. System prompts and context are hidden costs—the more conversation turns, the greater the cumulative consumption. For multi-turn scenarios, estimate by total session tokens, not per turn.
Step 3: Introduce retry and failure coefficients
Actual consumption = consumption of successful calls + consumption from retries. The retry rate comes from re-requests after timeouts, rate limits, and format non-compliance. This coefficient is often overlooked but has a significant impact under high concurrency. When evaluating a new model, record its retry rate as well, because a "cheaper but more failure-prone" model may have a higher real cost.
Step 4: Consider prompt structure
Fixed system prompts and common knowledge snippets can be placed first, with variable content later; this mainly affects maintenance and latency and is not treated as a cost-reduction mechanism.
Step 5: Convert to unit business cost
In the end, do not stop at "how much per million tokens"; convert to business metrics: how many tokens per customer service session, per generated piece of content, per ticket. Only business-metric numbers can be compared alongside revenue and labor costs. Plug your own length distribution into the input and output unit prices above.
Conclusion: selection under token-based pricing is essentially comparing "tokens required to complete the same business action × unit price × retry coefficient," not comparing unit prices themselves.
Build your own small-scale evaluation
Public leaderboards cannot replace your evaluation. The good news is that an adequate evaluation set does not need to be large; the key is being fixed and reproducible.
Build a fixed evaluation set
Sample from real requests, covering the task types, length ranges, and image-input scenarios you care about, and prepare expected results or validation rules for each sample. The sample size should be sufficient to cover major failure modes, and keep a long-term-unchanged "core set" for cross-model, cross-time comparison.
Call candidate models in parallel
For the same batch of samples, use identical prompts and identical parameters (including reasoning_effort level and route selection) to call candidate models separately (including gemini-4-argon and existing models), recording output, elapsed time, token usage, and error information. The key is controlling variables: do not optimize prompts separately for one model, or the comparison loses meaning; if optimization is needed, do a separate round comparing "each model's best prompt."
Automated scoring
Automate whatever can be checked by rules (format, fields, length, keyword coverage), and use small-sample human ratings for the remaining subjective parts. Organize the scoring sheet by the five dimensions above and output a comparison table with one score or pass rate per model per item.
Look at differences, not absolute scores
The focus of comparison is "on which samples the two models perform differently." Checking divergent samples one by one often reveals the real differences in capability boundaries. These divergence points are the basis for migration decisions.
Record reproducible information
Save sample versions, prompt versions, call parameters (including standard or @vertex route and reasoning_effort level), and timestamps. Models are updated and conclusions expire; keeping metadata lets you know where differences come from during the next re-evaluation.
A small but fixed evaluation set is far more valuable than a large-scale but irreproducible "trial impression."
Considerations for migrating to gemini-4-argon
Migration complexity usually lies not in the calls themselves, but in adapting prompts, output parsing, and fault-tolerance strategies.
Prompt adaptation
Different models respond to instructions in different styles: some prefer concise answers, others tend to expand with explanations. During migration, first run the existing prompts and record which instructions fail. Common adjustments include: writing implicit requirements as explicit constraints, placing output-format requirements earlier, and reducing reliance on "the model will understand on its own." Do not rewrite all prompts at once; change and verify them one by one.
Output parsing
Assume output may contain extra wrapper text, and the parsing layer must be fault-tolerant: first attempt structured parsing, then do fallback extraction if that fails, and only then retry. Because the API does not support JSON mode, parse failure rate should especially be a monitoring metric during migration; it reflects real usability better than model self-evaluation.
Timeouts and retries
Reset timeout thresholds; do not reuse the old model's configuration. Retries should have limits and backoff, and distinguish retryable errors (timeouts, rate limits) from non-retryable errors (parameter errors, content violations). The retry strategy directly affects token consumption and should be included in cost estimation during migration evaluation.
Canary rollout and rollback
Start with a small-traffic canary rollout, split by business dimension (for example, a certain entry point or a certain task type), and compare the old and new models' metrics on the same traffic. Keep a rollback path: model selection and route (standard or @vertex) should be configuration items rather than hardcoded, so rollback requires only configuration changes, not code changes. Also prepare data consistency handling after rollback to avoid mixing old and new outputs and causing downstream anomalies.
Regression cases
Solidify the core samples from the evaluation set as regression cases and run them on every prompt or parameter change. Migration is not a one-time action; subsequent model updates also need this regression protection.
Reusable selection review checklist
The checklist below is for item-by-item confirmation before launch and can also serve as a fixed appendix to the selection document for team retrospectives.
Boundary confirmation
- Is the pipeline's input only text and images? Have other modalities been converted before the call?
- Does the pipeline require tool calling, web search, computer use, or structured output? If so, has this been supplemented in the application layer?
- Do the 1,048,576-token context and 65,536-token single output cover the real length distribution?
- Has the standard route or @vertex route been confirmed, and the corresponding unit price included in the budget?
Evaluation validity
- Is a fixed evaluation set used, with samples drawn from the real request distribution?
- Do all five dimensions (quality, latency, stability, cost, capability boundaries) have measurable metrics?
- Are comparisons made after fixing the reasoning_effort level and route?
- Have divergent samples against the existing model been checked one by one, with capability boundaries recorded?
Cost basis
- Is estimation based on P50 and P90 length distributions rather than averages?
- Are system prompts, context accumulation, retries, and failure coefficients included?
- Are input and output unit prices used, rather than estimating only by input price?
- Has the result been converted to unit business cost rather than left at token unit price?
Engineering adaptation
- Have prompts been validated and adjusted one by one for the new model?
- Does output parsing have fault-tolerant and fallback paths?
- Have timeout, retry, and backoff strategies been reset with limits?
- Have the model and route been abstracted as configuration items, so rollback requires no code changes?
Launch and observability
- Is a small-traffic canary rollout done first, with observation windows and comparison metrics defined?
- Are regression cases solidified to cover subsequent prompt and parameter changes?
- Are sample versions, prompt versions, and call parameters recorded to ensure conclusions are reproducible?
The purpose of this checklist is not only to prevent omissions, but to turn a selection conclusion into a reusable team asset: when the next model launches, you can update only the evaluation data instead of rebuilding the judgment framework from scratch. The endpoint of selection is not "which model was chosen," but "a process for making choices continuously."
Related articles
View all articles →-

Comparison
Gemini 4 Series and 3.8 Flash Model Selection: API, Cost, and Migration
Based on the Chat Completions-compatible API, compare the task positioning, reasoning effort, and token cost of the three model lines
-

Comparison
How to Choose gemini-4-carbon: A Selection Guide by Task, Context, Reasoning Effort, and Cost
Make decisions across four dimensions: task requirements, context, reasoning effort, and cost
-

Comparison
HiAPI vs KIE: A line-by-line price comparison of 10 models (November 2026)
A line-by-line price comparison of 10 models, plus top-up rules and a one-week usage example
4 min read