
Guide
Getting Started with gemini-4-hydrogen: Capability Boundaries, Key Parameters, and Integration Practices
A Text Model Integration and Selection Reference for Engineering Teams
On this page
gemini-4-hydrogen's Positioning and Capability Boundaries
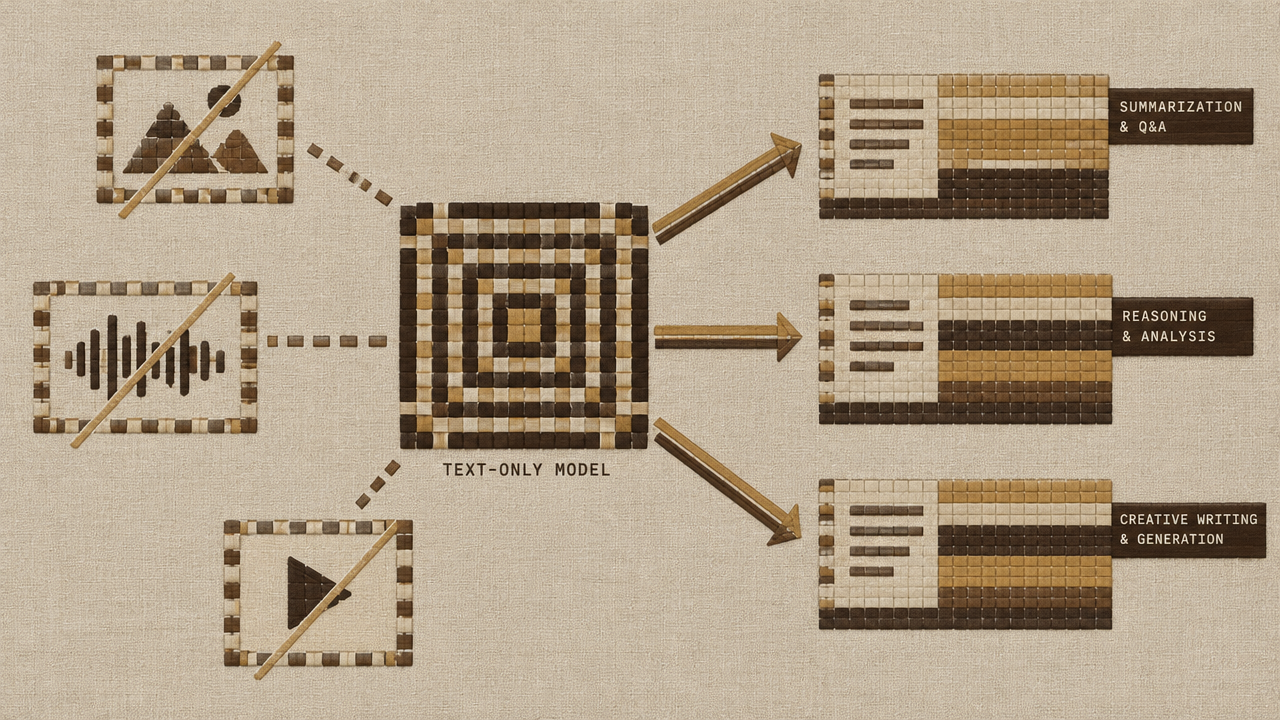
gemini-4-hydrogen is a text model launched by Google. Its output type is plain text—which determines where you should place it in your architecture: in text-in, text-out stages, not as a link in a multimodal pipeline.
What It Excels At
From an engineering perspective, the most typical landing points for a plain-text-output model are tasks where "the intermediate product is just a piece of text":
- Structured extraction and transformation: converting unstructured text into agreed formats such as JSON, table rows, or field lists;
- Summarization and rewriting: compressing long documents, adjusting tone, unifying multilingual phrasing;
- Classification and judgment: intent recognition, content grading, ticket routing—trading short outputs for low latency;
- Generation-type assistance: pre-human-review steps such as draft writing, code comment completion, and prompt expansion;
- Dialogue and Q&A: organizing answers given retrieval context.
What these tasks share: the input can be serialized as text, the output can be parsed by downstream programs, and the results can be sampled for review.
What It Is Not Suitable For
Also as an engineering judgment, clear boundaries need to be drawn in advance:
- Do not expect it to directly produce images, audio, or video. The output form is text; chains involving multimodal generation must be assembled elsewhere;
- Do not treat it as a strongly deterministic calculator. Logic such as precise arithmetic and strict rule validation should be handled by code, not the model;
- Do not let it make factual assertions without context. For scenarios requiring external knowledge, first use retrieval to place the material into the input, then have it organize the answer;
- Do not treat it as the sole information source for real-time events. The model's internal knowledge has a cutoff boundary; content with high timeliness requirements must be injected by your system.
Writing these points into the team's design docs is far cheaper than patching things downstream after the fact.
Things to Confirm Before Integration
Before writing the first line of calling code, several things are worth confirming clearly; otherwise, the debugging phase will be filled with many ineffective investigations.
Clarify Task Shape and Output Contract
First answer three questions: Is the input single-turn or multi-turn? Is the output free text, or must it conform to a certain structure? Can downstream tolerate retries on failure? These three answers directly determine how you write prompts, how you set the output length limit, and how you validate.
Credentials and Invocation Entry Point
Regardless of which integration method you ultimately use, you need a set of manageable, rotatable API credentials, and do not write credentials into frontend code or commit them to the repository. The recommended approach: store credentials in server-side environment variables or a secret management service, have the backend be the unified exit for model calls, and let the frontend communicate only with your backend. This avoids leaks and also facilitates later quota management and auditing by business dimension.
Network and Timeout Budget
The time for a single text model request varies with input length and output length. Before launch, determine: What is the maximum response time your business can accept? Based on that, work backward to request timeouts, retry counts, and degradation strategies. Many reports of "model instability" are actually mismatches between timeout settings and business expectations.
Observability Before Features
Before writing business logic, define the log fields first: request ID, input token count, output token count, elapsed time, error code. These items are almost essential later for cost accounting and issue diagnosis; adding them afterward often requires changing a round of code.
Compliance and Data Boundaries
Confirm whether the content you intend to send contains sensitive information such as user privacy, keys, or internal documents, and clarify which fields must be desensitized before being sent to the model.
Invocation Parameters and Request Organization Points
A typical invocation consists of three parts: input content, control parameters, and returned result. What truly affects result quality and cost is usually only a few parameters.
How to Organize Input Content
Think of the input as three layers: "instruction + context + data to be processed":
- Put the instruction first, stating the role and task goal;
- Put the context (retrieved materials, conversation history) in the middle, with clear separation;
- Put the data to be processed last, adjacent to the object the instruction asks to act on.
For multi-turn conversations, keep the most recent several turns rather than stacking history indefinitely—the longer the history, the more input-side consumption, and noise dilutes key information. For content requiring long-term memory, it is recommended to summarize it and inject the summary rather than carrying the full original text.
Key Parameters
- Output length limit: This is the most easily overlooked parameter, yet it affects both cost and experience. Setting it too small causes answers to be truncated; setting it too large leaves the model room to become "verbose". It is recommended to tier it by task type: give classification tasks a very small limit, and only open it up for long-form generation.
- Sampling parameters such as temperature/top-p: For tasks requiring stable output such as extraction, classification, and format conversion, lower the randomness; copywriting generation can be moderately opened up. Keep them consistent within the same business for easier regression comparison.
- Stop conditions: If your downstream requires the output to end at a certain point (for example, only taking the first JSON paragraph), constraining with stop sequences is more reliable than post-hoc regex trimming.
- Structured output constraints: When programmatic parsing is needed, provide field names, types, and examples in the instruction, and explicitly state "output only JSON, without accompanying explanation".
Several Experiences in Request Organization
- Separate prompts from business code and make them versionable templates for easy A/B comparison;
- Add parsing fallbacks for output: on parse failure, log the raw return rather than directly throwing an error to the user;
- Set idempotency keys for the same request to avoid duplicate billing and duplicate side effects caused by retries;
- For long-input scenarios, split and filter first, keeping irrelevant paragraphs out of the model—this is the most direct way to save money.
How to Estimate and Control Costs Under Token-Based Pricing
gemini-4-hydrogen is priced per token. This means your cost is almost entirely determined by two things: how many tokens are sent in per request, and how many tokens the model spits out. For price figures, refer to the site's pricing panel; here we only discuss methods.
Build an Estimation Habit
Do not estimate by feel. The approach: first run a batch of real samples, record the input token and output token counts for each request, and group statistics by business scenario for averages and percentiles. Use "average token count × daily average call volume" to get an order-of-magnitude estimate, then use P95 to see the worst case. You will find that distributions vary greatly across scenarios, and estimating with a uniform average often leads to serious deviations.
Specific Levers for Cost Control
- Compress input: Remove repeated system prompts, trim irrelevant context, and summarize long documents before sending. The input side is usually the main cost, and the benefits are most direct;
- Limit output: Use output length limits and instructions such as "please answer concisely" to directly cut redundant output;
- Tiered invocation: Solve simple classification and format validation with small requests, and only make full invocations when generation capability is truly needed;
- Caching and deduplication: Cache results for identical or highly similar requests, especially batch offline tasks;
- Batching and asynchrony: Accumulate non-real-time tasks for batch processing to reduce repeated fixed overhead.
Turn Cost into an Observable Metric
Record token consumption in logs by business line, and build daily/weekly trend dashboards. When consumption rises abnormally on a certain day, it usually corresponds to three types of causes: growth in call volume, longer input (for example, the context assembly logic changed), or longer output (for example, the prompt was modified). Making these three points into monitoring items can save a lot of after-the-fact investigation.
One final reminder: do not optimize cost at the expense of output quality. Build an evaluation set first, then talk about compression.
Integration and Multi-Model Comparison on an Aggregated API Platform
For most teams, the biggest cost during the selection phase is not writing code, but "changing the integration layer every time you switch models". Using a unified entry point can minimize this cost.
Benefits of a Unified Interface
On an aggregated API platform, model invocation is unified into the same request structure: the same authentication method, the same message format, the same return parsing logic. When switching models, usually only the model identifier needs to be changed, and business code basically stays untouched. The direct benefits are:
- The integration layer is written once and shared by multiple models;
- Lateral comparison during the evaluation phase can be done at low cost;
- Production can do canary releases and rapid rollback—when a model has problems, switching to an alternative only requires changing configuration.
For integration information and availability of this model, see the model page: /models/gemini-4-hydrogen.
Run a Same-Task Comparison
Do not just look at leaderboards. Instead, prepare your own evaluation set covering 20 to 50 samples from the real business distribution, including simple cases, edge cases, and long-input cases, and then:
- Run multiple candidate models with the same prompt template;
- Record output quality (manual or rule-based scoring), elapsed time, and token consumption;
- Focus on pass rate and failure modes, not average scores;
- Attribute samples with obvious differences: is it an instruction-following issue, a format issue, or long-context truncation?
Switch and Coexistence Strategy
Evaluation conclusions are often not "use only one model" but "divide work by scenario". For example: use a low-latency model for classification and extraction, and use a model with better output quality for long-form generation. A unified entry point lets this division of labor be expressed at the configuration layer without maintaining multiple SDKs. It is also recommended to keep a configuration switch for the model identifier in the integration layer, combined with gradual canary releases to increase traffic step by step.
Pre-Launch Validation Checklist and Common Issue Troubleshooting
Pre-Launch Validation Checklist
Run through these steps in order before considering scaling up:
- Smoke test: Can the shortest request return normally, and are authentication and network connectivity working;
- Format validation: In structured output scenarios, what is the parse success rate for batch samples, and what do parse failures look like;
- Edge inputs: How do overly long input, empty input, and input containing special characters and multiple languages perform respectively;
- Output length: Is output truncated in the worst case, and can downstream recognize truncation;
- Concurrency and timeout: At expected peak concurrency, are the timeout rate and error rate acceptable;
- Degradation path: When the primary model is unavailable, does the chain of switching to an alternative or returning a fallback result actually work;
- Cost baseline: Record token consumption under one round of typical traffic as the baseline for subsequent monitoring.
Common Issues and Troubleshooting Order
Request timeout: First check whether the input is too long (especially whether an entire document was stuffed in), then check whether the output limit is set too large, and finally confirm whether the client timeout and retry strategy are reasonable. Retries need backoff to avoid cascading failures.
Output truncated: Check the output length limit and whether the prompt requests overly long content; sometimes improper stop sequence settings cause early termination.
Output unstable, format sometimes good and sometimes bad: Prioritize reducing sampling randomness; next check whether instructions are clear (are field names, types, and examples complete); then check whether contradictory examples are mixed into the input.
Content deviates from instructions: A common cause is overly long context diluting key instructions. Moving the instruction to the end of the input and repeating it once, or compressing the context, usually improves it.
Abnormally rising costs: Attribute according to the three items mentioned earlier—call volume, input length, output length—and compare them one by one against log trends.
Results not reproducible: Record request parameters and template versions; model output itself has randomness, so do not expect verbatim reproduction, and validation should be based on rules or manual scoring.
Embedding this checklist into the release process is much more stable than improvising on each launch. For specific details of selection and integration, start by confirming on the model page /models/gemini-4-hydrogen.
Related articles
View all articles →-

Guide
Nano Banana Basic Text-to-Image Guide: Aspect Ratio, Negative Space, and Prompt Usage
Use the task API's aspect_ratio and prompt fields to generate clearly composed images for banners and social cards
-

Guide
Kimi K3 Response Handling in Practice: Complete JSON, Stream Interruption, and Retry Boundaries
-

Guide
GLM 5.3 Structured Extraction in Practice: Give Every JSON Field Textual Grounding
Use JSON object mode for field extraction, and use missing values, quotations, and business validation to stop errors before they enter the database