
Pruna AI
P-Video 2 Pro Avatar
p-video-2-pro-avatar
Pruna AI's portrait-driven talking video model generates lip-synced, expressive talking-head clips from a single portrait image. It can be driven by uploaded audio or read a script aloud directly using built-in text-to-speech, making it well suited for batch production of course explainers, multilingual dubbing, and digital human short videos
Try p-video-2-pro-avatar
Input
Showcases
View all showcasesOutput
videoVisual Notes on Cinematic Language · Digital Human Voiceover Explaining Motion Terms
Style Spoken presentation · camera-language · studio
Reference inputs
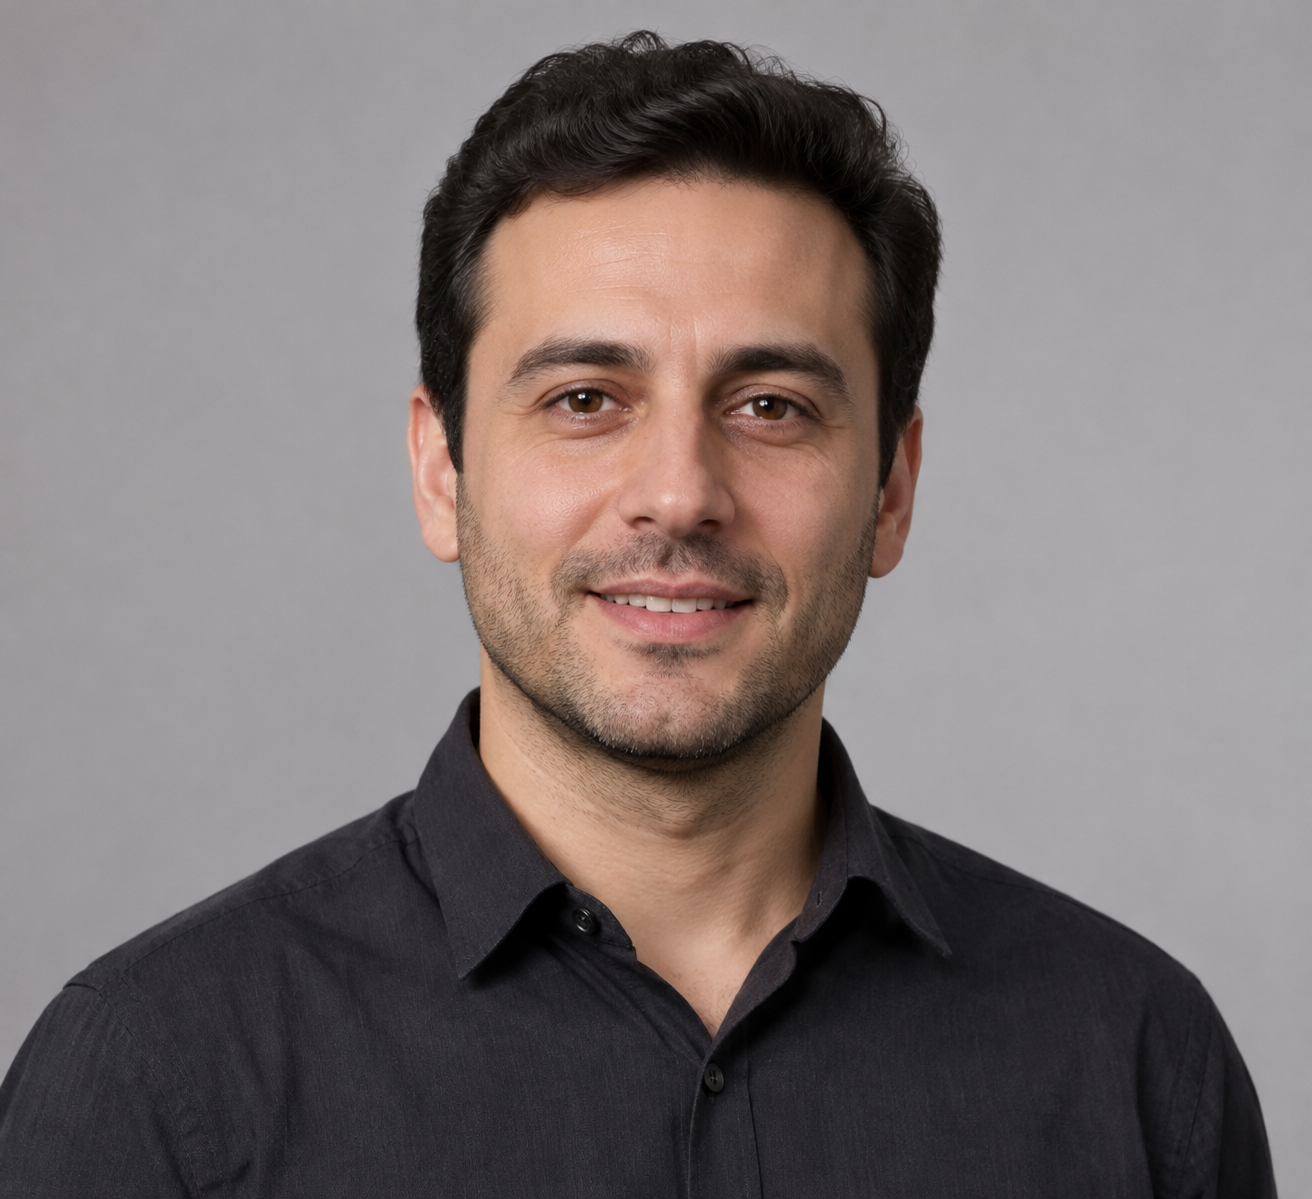
Portrait image
Prompt
A calm instructor in a dark shirt stands in front of a soft light-gray studio backdrop, facing the camera and explaining each camera movement term one by one. Shoulders and head shift gently with the rhythm of speech, expression focused and restrained, gaze steady toward the lens. Neutral soft key light comes from the front side, complemented by subtle bounce fill, creating a quiet classroom atmosphere with realistic skin texture; the instructor blinks naturally and gives slight nods as sentences land.
Copy the full prompt and adapt it for your own generation.
Tags
A Curator's Monologue After the Museum Closes
Style Talking portrait · Museum · Culture
Reference inputs
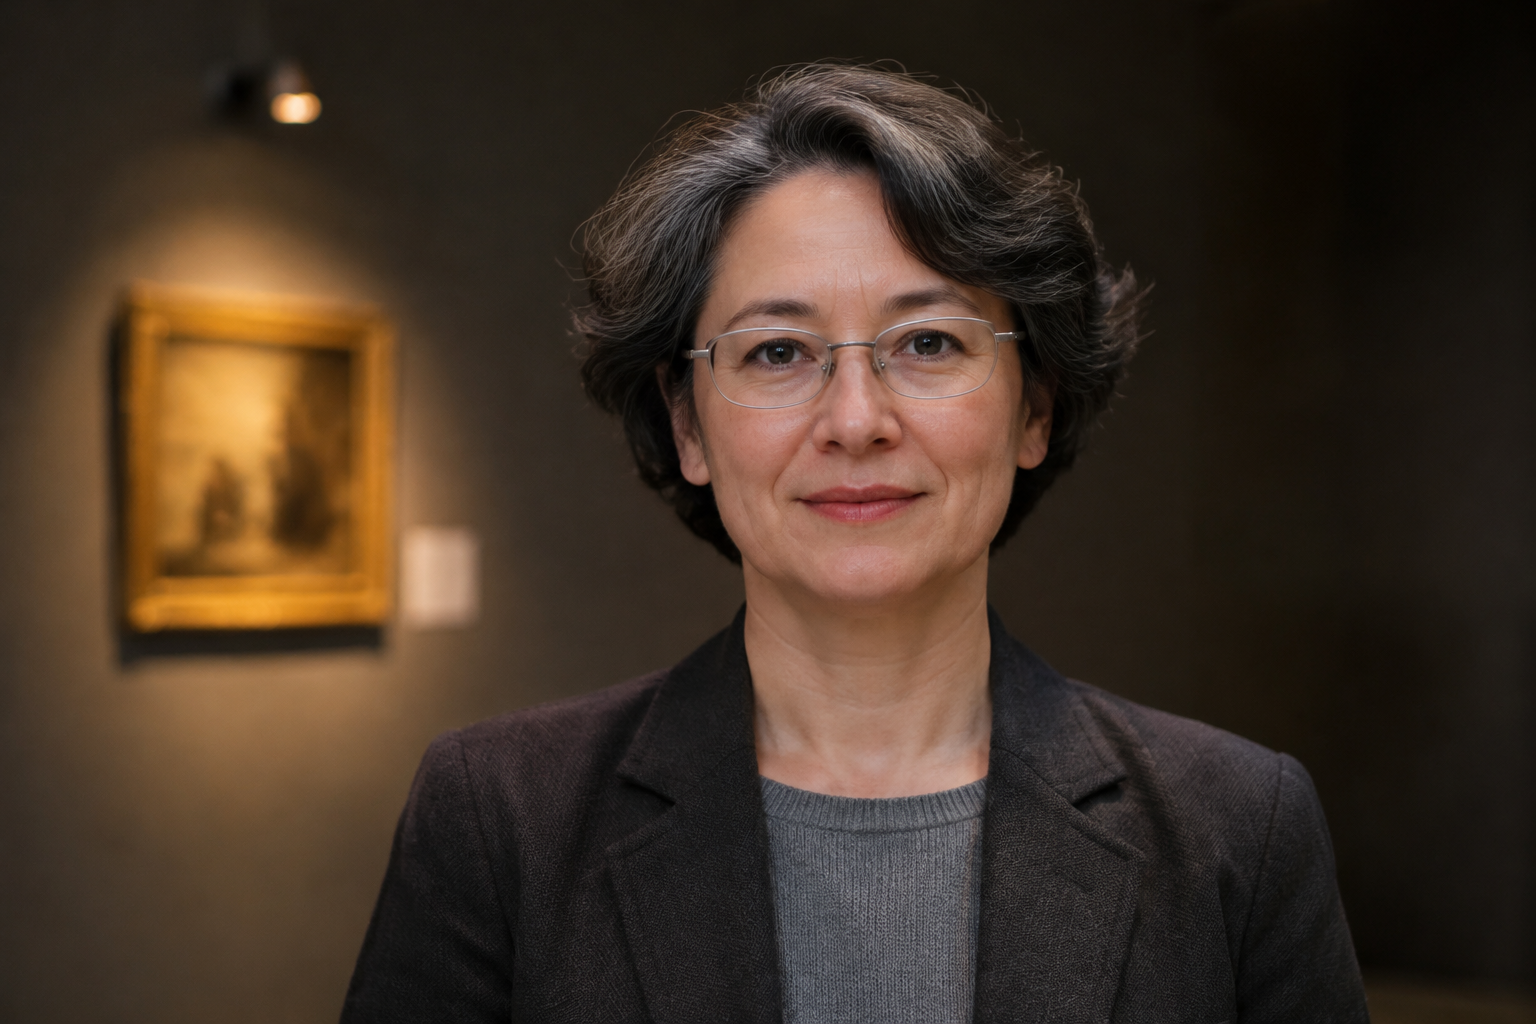
Portrait image
Prompt
A middle-aged female curator sits on the edge of a gallery bench, with a softly lit exhibition wall behind her shoulder; she calmly speaks to the camera about an exhibit, giving a slight nod, blinking naturally, her expression composed and gentle; shallow depth of field, warm tungsten gallery lighting with soft falloff, a quiet museum atmosphere, with only subtle movements of her face and shoulders.
Copy the full prompt and adapt it for your own generation.
Tags
Pricing
p-video-2-pro-avatar per second
| Specifications | Unit Price |
|---|---|
| 480P | $0.0286 |
| 768P | $0.0572 |
| 1080P | $0.0858 |
| 2K | $0.1143 |
| 4K | $0.1715 |
Positioning Overview
A video generation model for digital human talking-head scenarios: upload a single portrait as the first frame, then provide speech audio or input script text to generate a video of the person speaking. The script is read aloud by built-in speech synthesis, with multiple voice options and languages, and prompts describe the person's movements and expressions while speaking. It is suitable for content creators who need a real-person on-camera presence, such as course explanations, marketing talking-head videos, and short social videos, eliminating the need for filming and lip-syncing.
Core Highlights
- A single portrait drives a talking video — only one portrait is needed as the first frame, with no existing video footage required, to generate footage of the person speaking.
- Two driving modes: audio and script — you can upload speech audio of no more than 3 minutes, or input a script that is read aloud by built-in speech synthesis, with the video length following the speech.
- Prompts control expressions and movements — use prompts to describe the person's appearance, movements, and expressions while speaking, and set a random seed to reproduce results.
- Multiple resolution tiers cover production needs — choose from five resolution tiers: 480p, 768p, 1080p, 2k, and 4k, making it easy to select image quality based on the publishing platform.
Capability Description
Portrait-driven talking video: provide a portrait in jpg, jpeg, png, or webp format via an HTTPS link as the first frame to generate a video of the person speaking, with the visual content described by a prompt covering their appearance, movements, and expressions.
Upload audio to drive lip-sync: provide an HTTPS speech audio link; the video length matches the audio, up to 3 minutes; when using the 4k specification, the audio can be up to 125 seconds. In this case, the script, voice, language, and speech style settings no longer take effect.
Script-to-speech driving: when no audio is provided, input a script of up to 5000 characters, which is read aloud by built-in speech synthesis to generate the video; the script language must be selected from ten given languages, and a speech style description of up to 1000 characters can be used to describe the tone and pacing.
Voice and visual parameter selection: choose one of 30 built-in voices to read the script, use a prompt of up to 2000 characters to describe the visuals, and set a random seed between 0 and 2147483647; choose one resolution from 480p, 768p, 1080p, 2k, and 4k, with 768p as the default.
Applicable Scenarios
- Batch talking-head videos for course instructors — instructors provide a portrait and explanation script to batch-generate on-camera explanation videos for online courses or knowledge programs.
- Real-person talking-head marketing assets — operations teams use a product spokesperson's portrait together with promotional copy to generate talking-head clips for feed ads or brand social accounts.
- Turning existing recordings into finished videos — creators upload their own recordings and portraits so the on-screen lip-sync matches the recording, directly producing short videos for social platforms.
- Converting static portraits into talking videos — use existing photos of people together with scripts or audio to generate speaking footage with expressions and lip-sync for digital human programs or showcase pages.
Limitations and Selection Advice
Scripts and prompts have length limits: prompts up to 2000 characters, scripts up to 5000 characters, and speech style descriptions up to 1000 characters. The built-in voices do not support Chinese; the script language must be selected from English, Spanish, French, German, Italian, Portuguese (Brazil), Japanese, Korean, and Hindi. Video length is determined by the speech, up to 3 minutes; when using the 4k specification, the audio can be up to 125 seconds.
What's new
View changelog →- New model P-Video 2 Pro Avatar is live: turn one portrait plus audio or a script into a talking video up to 3 minutes long
Frequently asked questions
View all FAQs →-
What audio can be used to drive the digital human?
Pass an HTTPS audio link via audio_url. The video length equals the audio duration, up to a maximum of 3 minutes (4k up to a maximum of 125 seconds). Once audio is provided, script, voice, voice_language, and voice_prompt no longer take effect; if both are provided, the audio takes precedence.
-
How long can the script text be?
The script field allows up to 5000 characters, but the video length is ultimately determined by the duration of the built-in TTS reading the script aloud, with an upper limit of 3 minutes; when approaching the limit, it is recommended to first trim the text or generate it in segments.
-
How can I write better prompts for talking-head videos?
The prompt describes the person's appearance, movements, and demeanor while speaking, without writing any dialogue. It is recommended to write in the order of "person's appearance → range of movement → expression and gaze → camera feel", for example, "a man in a dark suit, sitting naturally, occasionally nodding, smiling at the camera, fixed medium shot", kept within 2000 characters; the default value is only "The person is talking."
-
Which languages and voices are supported?
voice_language supports 10 languages: American English, British English, Spanish, French, German, Italian, Brazilian Portuguese, Japanese, Korean, and Hindi; Chinese is not currently included. voice offers 30 preset voices, with gender indicated in the name; the default is Zephyr (Female). The text in script must match the selected language.
Create a generation task
https://api.hiapi.ai/v1/tasks Headers
AuthorizationstringRequiredAccount API key. Required on every request. Example: Bearer YOUR_HIAPI_API_KEY. Get your API key
Content-TypestringOptionalThe request body is always parsed as JSON; when sent, only application/json (optionally with charset) is accepted — any other value returns 415. Example: application/json.
Idempotency-KeystringOptionalIdempotency key, up to 255 bytes. Retries with the same key from the same account create the task only once; replays return the original taskId.
On network timeouts or client retries, the same key creates the task only once — no double charges (scope: the API key's account). Use a business-unique identifier as the key (e.g. "order-42"); replays return the original taskId, and keys expire 24 hours after the first request. See the Unified Async API overview for the full scenario matrix.
Body
modelstringRequiredCurrent fixed value: p-video-2-pro-avatar
routestringOptionalCurrent fixed value: default
inputobjectRequired
Business parameters for p-video-2-pro-avatar and route default — see the parameter table below.
seedintegerOptionalmin 0max 2147483647Random seed, an integer from 0–2147483647; passing the same seed while keeping other inputs unchanged helps reproduce results. If not provided, it is random.
voicestringOptionalDefault: "Zephyr (Female)"The voice used for the built-in text-to-speech, default Zephyr (Female). This parameter is ignored when audio_url is provided.
Zephyr (Female)Puck (Male)Charon (Male)Kore (Female)Fenrir (Male)Leda (Female)Orus (Male)Aoede (Female)Show all (22)Show less
Callirrhoe (Female)Autonoe (Female)Enceladus (Male)Iapetus (Male)Umbriel (Male)Algenib (Male)Despina (Female)Erinome (Female)Laomedeia (Female)Achernar (Female)Algieba (Male)Schedar (Male)Gacrux (Female)Pulcherrima (Female)Achird (Male)Zubenelgenubi (Male)Vindemiatrix (Female)Sadachbia (Male)Sadaltager (Male)Sulafat (Female)Alnilam (Male)Rasalgethi (Male)promptstringOptionalDefault: "The person is talking."maxLength 2000A description of the video content, explaining the person's appearance, actions, and behavior while speaking; default is "The person is talking.".
scriptstringOptionalmaxLength 5000The exact script the digital human will read aloud, written in the selected voice_language (Chinese is not supported). Required when audio_url is not provided; the reading duration determines the video length, up to 3 minutes.
audio_urlstringOptionalpattern ^https://An HTTPS URL of the speech audio, up to 3 minutes (up to 125 seconds at 4k resolution); the video length matches the audio. When provided, script, voice, voice_language, and voice_prompt are all ignored.
image_urlstringRequiredpattern ^https://An HTTPS URL of the speaking person's portrait image, used as the video's first frame; supports jpg, jpeg, png, and webp formats.
resolutionstringOptionalDefault: "768p"Output resolution, options are 480p, 768p, 1080p, 2k, 4k, default 768p; higher resolution costs more.
480p768p1080p2k4kvoice_promptstringOptionalDefault: "Say the following."maxLength 1000A voice style instruction describing the delivery such as tone, pacing, accent, or emotion; it is not read aloud. Default is "Say the following.". Ignored when audio_url is provided.
voice_languagestringOptionalDefault: "English (US)"The language used for the script text, default English (US). Ignored when audio_url is provided.
English (US)English (UK)SpanishFrenchGermanItalianPortuguese (Brazil)JapaneseShow all (2)Show less
KoreanHindicallbackobjectOptional
Terminal-state notification config. When omitted, no callback is delivered — poll the task yourself. See the callback note below.
Provide callback.url when creating a task and HiAPI POSTs to your service once the task reaches a terminal state — no polling needed. The callback payload mirrors the task detail structure; signature verification, delivery retries and idempotency are documented on the Unified Async API overview page.
urlstringRequiredRequired when callback is present. A POST is sent to this URL once the task reaches a terminal state; must be a valid http(s) URL.
whenstringOptionalDefault: "final"Only final is supported today — notified on both success and fail.
finalstoragestringOptionalDefault: "temp"Artifact storage tier: temp (default, retained about 7 days) or persistent (long-term, billed by size). Insufficient balance or exceeding the storage cap silently downgrades to temp; the effective tier is shown in the task detail response.
temppersistentRequest examples
# Submit an async task; returns a taskId immediately (no waiting for generation)
curl -X POST "https://api.hiapi.ai/v1/tasks" \
  -H "Authorization: Bearer $HIAPI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "p-video-2-pro-avatar",
  "input": {
    "voice": "Zephyr (Female)",
    "prompt": "The person is talking.",
    "image_url": "…",
    "resolution": "768p",
    "voice_prompt": "Say the following.",
    "voice_language": "English (US)"
  }
}'
const res = await fetch("https://api.hiapi.ai/v1/tasks", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.HIAPI_API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
model: "p-video-2-pro-avatar",
input: {
"voice": "Zephyr (Female)",
"prompt": "The person is talking.",
"image_url": "…",
"resolution": "768p",
"voice_prompt": "Say the following.",
"voice_language": "English (US)"
}
}),
});
const task = await res.json();
// { code: 200, message: "success", data: { taskId } }import os, requests
res = requests.post(
"https://api.hiapi.ai/v1/tasks",
headers={"Authorization": f"Bearer {os.environ['HIAPI_API_KEY']}"},
json={
"model": "p-video-2-pro-avatar",
"input": {
"voice": "Zephyr (Female)",
"prompt": "The person is talking.",
"image_url": "…",
"resolution": "768p",
"voice_prompt": "Say the following.",
"voice_language": "English (US)"
}
},
)
print(res.json()) # { code, message, data: { taskId } }200 OK
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-01HZTQ8BX2N3GM3YFK4Z9D7VQR"
  }
}
400 Bad Request
{
  "code": 400,
  "message": "invalid request",
  "data": null,
  "error_code": "INVALID_REQUEST"
}
Get task detail
https://api.hiapi.ai/v1/tasks/:id Response fields
taskIdstringRequiredTask ID, always prefixed with tk-hiapi-.
modelstringRequiredResolved full model name. Tasks submitted with the route parameter return base@route (e.g. gpt-image-2/text-to-image@ext); otherwise identical to the name passed at creation.
routestringOptionalPresent only when the task was submitted with an explicit route parameter; echoes the submitted value.
statusstringRequiredTask status.
queued Queued, not started yet.
handling Being processed.
archiving Processing finished, artifacts being prepared.
success Terminal: completed, artifacts available (output returned).
fail Terminal: failed (error returned).
After submission, check status: success and fail are terminal, everything else is non-terminal. Poll every 1–3 seconds until terminal. On success, download artifacts from output[].url and transfer them before expireAt; pass storage: "persistent" at creation time when long-term retention is needed.
creatednumberRequiredTask creation time (Unix seconds).
completednumberRequiredUnix seconds when the task reached a terminal state; fixed to 0 while not terminal.
outputarrayOptional
Present only when status == success. Artifact list — always an array; a single task may return multiple types at once (e.g. video + first_frame).
Array [ object ]
Array items
urlstringRequiredArtifact URL, directly downloadable.
typestringRequiredCurrent possible values: video, image, audio, first_frame, last_frame, thumbnail; more may be added later.
expireAtnumberRequiredUnix seconds until which the artifact remains accessible; download or transfer before it expires.
errorobjectOptional
Present only when status == fail.
codestringRequiredBusiness error code.
messagestringRequiredError description.
Response examples
Success
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-01HZTQ8BX2N3GM3YFK4Z9D7VQR",
    "model": "happyhorse-1-0",
    "status": "success",
    "created": 1777282033,
    "completed": 1777282099,
    "output": [
      {
        "url": "https://cdn.hiapi.ai/tasks/.../video.mp4",
        "type": "video",
        "expireAt": 1777886899
      }
    ]
  }
}
Processing (non-terminal)
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-...",
    "model": "happyhorse-1-0",
    "status": "archiving",
    "created": 1777282033,
    "completed": 0
  }
}
Failed
{
  "code": 200,
  "message": "success",
  "data": {
    "taskId": "tk-hiapi-...",
    "model": "happyhorse-1-0",
    "status": "fail",
    "created": 1777282033,
    "completed": 1777282099,
    "error": {
      "code": "TASK_FAILED",
      "message": "task failed"
    }
  }
}Articles
View all articles →
Related Models
View all models →Same Type
-
 Veo 3.1 Lite Google $0.060 /second
-
 Kandinsky 6.0 Pro $1.93 /video
-
 Gemini Omni 1.1 Google $0.450 /video
-
 Grok Imagine 1.5 xAI $0.011 /second
-
 Seedance 2.0 ByteDance $0.017 /second
-
 MiniMax H3 MiniMax $0.072 /second
-
 P-Video 2 Pro Replace Pruna AI $0.036 /second
-
 Wan 3.0 Video Alibaba $0.040 /second
-
 Wan 2.6 Flash Alibaba $0.043 /second
-
 PixVerse V6 Max PixVerse $0.030 /second
-
 HeyGen Avatar IV HeyGen $0.150 /second
-
 FLUX 3 Video Black Forest Labs $0.090 /second